MapReduce: Simplified Data Processing on Large Clusters
Google, Inc.
Abstract
MapReduce is a programming model and an associated implementation for processing and generating large data sets. Users specify a map function that processes a key/value pair to generate a set of intermediate key/value pairs, and a reduce function that merges all intermediate values associated with the same intermediate key. Many real world tasks are expressible in this model, as shown in the paper.
Programs written in this functional style are automatically parallelized and executed on a large cluster of commodity machines. The run-time system takes care of the details of partitioning the input data, scheduling the program’s execution across a set of machines, handling machine failures, and managing the required inter-machine communication. This allows programmers without any experience with parallel and distributed systems to easily utilize the resources of a large distributed system.
Our implementation of MapReduce runs on a large cluster of commodity machines and is highly scalable: a typical MapReduce computation processes many terabytes of data on thousands of machines. Programmers find the system easy to use: hundreds of MapReduce programs have been implemented and upwards of one thousand MapReduce jobs are executed on Google’s clusters every day.
MapReduce: Xử lý dữ liệu đơn giản hóa trên các cụm lớn
Jeffrey Dean and Sanjay Ghemawat jeff@google.com, sanjay@google.com
Google, Inc.
Tóm tắt
MapReduce là một mô hình lập trình và một triển khai đi kèm để xử lý và tạo ra các tập dữ liệu lớn. Người dùng đặc tả một hàm map xử lý một cặp khóa/giá trị để tạo ra một tập các cặp khóa/giá trị trung gian, và một hàm reduce hợp nhất tất cả các giá trị trung gian được liên kết với cùng một khóa trung gian. Nhiều tác vụ thực tế có thể được biểu diễn trong mô hình này, như được trình bày trong bài báo.
Các chương trình được viết theo kiểu hàm này được tự động song song hóa và thực thi trên một cụm lớn các máy phổ thông. Hệ thống thời gian chạy xử lý các chi tiết của việc phân vùng dữ liệu đầu vào, lập lịch thực thi chương trình trên một tập hợp các máy, xử lý các sự cố của máy, và quản lý việc giao tiếp liên máy cần thiết. Điều này cho phép các lập trình viên không có kinh nghiệm về các hệ thống song song và phân tán dễ dàng sử dụng các tài nguyên của một hệ thống phân tán lớn.
Triển khai MapReduce của chúng tôi chạy trên một cụm lớn các máy phổ thông và có khả năng mở rộng cao: một tính toán MapReduce điển hình xử lý nhiều terabyte dữ liệu trên hàng nghìn máy. Các lập trình viên nhận thấy hệ thống dễ sử dụng: hàng trăm chương trình MapReduce đã được triển khai và hơn một nghìn công việc MapReduce được thực thi trên các cụm của Google mỗi ngày.
1 Introduction
1 Giới thiệu
Over the past five years, the authors and many others at Google have implemented hundreds of special-purpose computations that process large amounts of raw data, such as crawled documents, web request logs, etc., to compute various kinds of derived data, such as inverted indices, various representations of the graph structure of web documents, summaries of the number of pages crawled per host, the set of most frequent queries in a given day, etc. Most such computations are conceptually straightforward. However, the input data is usually large and the computations have to be distributed across hundreds or thousands of machines in order to finish in a reasonable amount of time. The issues of how to parallelize the computation, distribute the data, and handle failures conspire to obscure the original simple computation with large amounts of complex code to deal with these issues.
Trong năm năm qua, các tác giả và nhiều người khác tại Google đã triển khai hàng trăm phép tính chuyên dụng xử lý lượng lớn dữ liệu thô, chẳng hạn như các tài liệu được thu thập, nhật ký yêu cầu web, v.v., để tính toán nhiều loại dữ liệu dẫn xuất, chẳng hạn như các chỉ mục đảo, các dạng biểu diễn khác nhau của cấu trúc đồ thị của các tài liệu web, các bản tóm tắt về số trang được thu thập trên mỗi host, tập hợp các truy vấn thường xuyên nhất trong một ngày nhất định, v.v. Hầu hết các phép tính như vậy đều đơn giản về mặt khái niệm. Tuy nhiên, dữ liệu đầu vào thường rất lớn và các phép tính phải được phân tán trên hàng trăm hoặc hàng nghìn máy để hoàn thành trong khoảng thời gian hợp lý. Các vấn đề về cách song song hóa tính toán, phân phối dữ liệu và xử lý sự cố kết hợp lại làm che khuất phép tính đơn giản ban đầu bằng một lượng lớn mã phức tạp để giải quyết những vấn đề này.
As a reaction to this complexity, we designed a new abstraction that allows us to express the simple computations we were trying to perform but hides the messy details of parallelization, fault-tolerance, data distribution and load balancing in a library. Our abstraction is inspired by the map and reduce primitives present in Lisp and many other functional languages. We realized that most of our computations involved applying a map operation to each logical “record” in our input in order to compute a set of intermediate key/value pairs, and then applying a reduce operation to all the values that shared the same key, in order to combine the derived data appropriately. Our use of a functional model with user-specified map and reduce operations allows us to parallelize large computations easily and to use re-execution as the primary mechanism for fault tolerance.
Để đáp lại sự phức tạp này, chúng tôi thiết kế một trừu tượng hóa mới cho phép biểu đạt các phép tính đơn giản mà chúng tôi muốn thực hiện, nhưng che giấu các chi tiết rắc rối của việc song song hóa, khả năng chịu lỗi, phân phối dữ liệu và cân bằng tải trong một thư viện. Trừu tượng hóa của chúng tôi được lấy cảm hứng từ các nguyên thủy map và reduce có trong Lisp và nhiều ngôn ngữ hàm khác. Chúng tôi nhận thấy rằng hầu hết các phép tính của mình đều bao gồm việc áp dụng một thao tác map lên mỗi “bản ghi” logic trong đầu vào để tính một tập các cặp khóa/giá trị trung gian, sau đó áp dụng một thao tác reduce lên tất cả các giá trị có cùng khóa, nhằm kết hợp dữ liệu dẫn xuất một cách thích hợp. Việc sử dụng mô hình hàm với các thao tác map và reduce do người dùng chỉ định cho phép chúng tôi dễ dàng song song hóa các phép tính lớn và sử dụng việc thực thi lại làm cơ chế chính để chịu lỗi.
The major contributions of this work are a simple and powerful interface that enables automatic parallelization and distribution of large-scale computations, combined with an implementation of this interface that achieves high performance on large clusters of commodity PCs.
Những đóng góp chính của công trình này là một giao diện đơn giản và mạnh mẽ cho phép tự động song song hóa và phân phối các phép tính quy mô lớn, kết hợp với một triển khai của giao diện này đạt hiệu năng cao trên các cụm PC phổ thông.
Section 2 describes the basic programming model and gives several examples. Section 3 describes an implementation of the MapReduce interface tailored towards our cluster-based computing environment. Section 4 describes several refinements of the programming model that we have found useful. Section 5 has performance measurements of our implementation for a variety of tasks. Section 6 explores the use of MapReduce within Google including our experiences in using it as the basis for a rewrite of our production indexing system. Section 7 discusses related and future work.
Mục 2 mô tả mô hình lập trình cơ bản và đưa ra một số ví dụ. Mục 3 mô tả một triển khai của giao diện MapReduce được điều chỉnh cho môi trường tính toán dựa trên cụm của chúng tôi. Mục 4 mô tả một số cải tiến của mô hình lập trình mà chúng tôi nhận thấy hữu ích. Mục 5 trình bày các phép đo hiệu năng của triển khai của chúng tôi đối với nhiều loại tác vụ. Mục 6 khảo sát việc sử dụng MapReduce trong Google, bao gồm kinh nghiệm của chúng tôi khi sử dụng nó làm nền tảng để viết lại hệ thống lập chỉ mục phục vụ sản xuất. Mục 7 thảo luận về các công trình liên quan và công việc trong tương lai.
2 Programming Model
2 Mô hình lập trình
The computation takes a set of input key/value pairs, and produces a set of output key/value pairs. The user of the MapReduce library expresses the computation as two functions: Map and Reduce.
Tính toán nhận một tập các cặp khóa/giá trị đầu vào và tạo ra một tập các cặp khóa/giá trị đầu ra. Người dùng của thư viện MapReduce biểu diễn phép tính dưới dạng hai hàm: Map và Reduce.
Map, written by the user, takes an input pair and produces a set of intermediate key/value pairs. The MapReduce library groups together all intermediate values associated with the same intermediate key and passes them to the Reduce function.
Map, do người dùng viết, nhận một cặp đầu vào và tạo ra một tập các cặp khóa/giá trị trung gian. Thư viện MapReduce nhóm tất cả các giá trị trung gian gắn với cùng một khóa trung gian và truyền chúng cho hàm Reduce.
The Reduce function, also written by the user, accepts an intermediate key and a set of values for that key. It merges together these values to form a possibly smaller set of values. Typically just zero or one output value is produced per Reduce invocation. The intermediate values are supplied to the user’s reduce function via an iterator. This allows us to handle lists of values that are too large to fit in memory.
Hàm Reduce, cũng do người dùng viết, nhận một khóa trung gian và một tập các giá trị của khóa đó. Nó hợp nhất các giá trị này để tạo thành một tập giá trị có thể nhỏ hơn. Thông thường, mỗi lần gọi Reduce chỉ tạo ra không hoặc một giá trị đầu ra. Các giá trị trung gian được cung cấp cho hàm reduce của người dùng thông qua một bộ lặp (iterator). Điều này cho phép chúng tôi xử lý các danh sách giá trị quá lớn để chứa trong bộ nhớ.
2.1 Example
2.1 Ví dụ
Consider the problem of counting the number of occurrences of each word in a large collection of documents. The user would write code similar to the following pseudo-code:
Xét bài toán đếm số lần xuất hiện của mỗi từ trong một tập hợp lớn các tài liệu. Người dùng sẽ viết mã tương tự mã giả sau:
              map(String key, String value):
    // key: document name
    // value: document contents
    for each word w in value:
        EmitIntermediate(w, "1");

reduce(String key, Iterator values):
    // key: a word
    // values: a list of counts
    int result = 0;
    for each v in values:
        result += ParseInt(v);
    Emit(AsString(result));
              map(String key, String value):
    // key: document name
    // value: document contents
    for each word w in value:
        EmitIntermediate(w, "1");

reduce(String key, Iterator values):
    // key: a word
    // values: a list of counts
    int result = 0;
    for each v in values:
        result += ParseInt(v);
    Emit(AsString(result));
The map function emits each word plus an associated count of occurrences (just ‘1’ in this simple example). The reduce function sums together all counts emitted for a particular word.
Hàm map phát ra mỗi từ cùng với số lần xuất hiện tương ứng (chỉ là ‘1’ trong ví dụ đơn giản này). Hàm reduce cộng tất cả các số đếm được phát ra cho một từ cụ thể.
In addition, the user writes code to fill a mapreduce specification object with the names of the input and output files, and optional tuning parameters. The user then invokes the MapReduce function, passing it the specification object. The user’s code is linked together with the MapReduce library (implemented in C++). Appendix A contains the full program text for this example.
Ngoài ra, người dùng viết mã để điền vào một đối tượng đặc tả mapreduce tên của các file đầu vào và đầu ra, cùng các tham số tinh chỉnh tùy chọn. Sau đó, người dùng gọi hàm MapReduce, truyền cho nó đối tượng đặc tả. Mã của người dùng được liên kết với thư viện MapReduce (được triển khai bằng C++). Phụ lục A chứa toàn bộ văn bản chương trình cho ví dụ này.
2.2 Types
2.2 Các kiểu
Even though the previous pseudo-code is written in terms of string inputs and outputs, conceptually the map and reduce functions supplied by the user have associated types:
Mặc dù mã giả trước đó được viết theo các đầu vào và đầu ra kiểu chuỗi, về mặt khái niệm, các hàm map và reduce do người dùng cung cấp có các kiểu tương ứng:
              map     (k1,v1)          → list(k2,v2)
reduce  (k2,list(v2))    → list(v2)
              map     (k1,v1)          → list(k2,v2)
reduce  (k2,list(v2))    → list(v2)
I.e., the input keys and values are drawn from a different domain than the output keys and values. Furthermore, the intermediate keys and values are from the same domain as the output keys and values.
Tức là, các khóa và giá trị đầu vào được lấy từ một miền khác với miền của các khóa và giá trị đầu ra. Hơn nữa, các khóa và giá trị trung gian thuộc cùng miền với các khóa và giá trị đầu ra.
Our C++ implementation passes strings to and from the user-defined functions and leaves it to the user code to convert between strings and appropriate types.
Cài đặt C++ của chúng tôi truyền các chuỗi đến và đi từ các hàm do người dùng định nghĩa và để mã của người dùng chuyển đổi giữa các chuỗi và các kiểu thích hợp.
2.3 More Examples
2.3 Thêm ví dụ
Here are a few simple examples of interesting programs that can be easily expressed as MapReduce computations.
Dưới đây là một vài ví dụ đơn giản về các chương trình thú vị có thể dễ dàng được biểu diễn dưới dạng các phép tính MapReduce.
Distributed Grep: The map function emits a line if it matches a supplied pattern. The reduce function is an identity function that just copies the supplied intermediate data to the output.
Grep phân tán: Hàm map phát ra một dòng nếu nó khớp với mẫu được cung cấp. Hàm reduce là một hàm đồng nhất, chỉ sao chép dữ liệu trung gian được cung cấp sang đầu ra.
Count of URL Access Frequency: The map function processes logs of web page requests and outputs . The reduce function adds together all values for the same URL and emits a pair.
Đếm tần suất truy cập URL: Hàm map xử lý các nhật ký yêu cầu trang web và xuất . Hàm reduce cộng tất cả các giá trị của cùng một URL và phát ra một cặp .
Reverse Web-Link Graph: The map function outputs pairs for each link to a target URL found in a page named source. The reduce function concatenates the list of all source URLs associated with a given target URL and emits the pair:
Đồ thị liên kết Web đảo: Hàm map xuất các cặp cho mỗi liên kết đến một URL đích được tìm thấy trong một trang có tên source. Hàm reduce nối danh sách tất cả các URL nguồn gắn với một URL đích cho trước và phát ra cặp:
Term-Vector per Host: A term vector summarizes the most important words that occur in a document or a set of documents as a list of pairs. The map function emits a pair for each input document (where the hostname is extracted from the URL of the document). The reduce function is passed all per-document term vectors for a given host. It adds these term vectors together, throwing away infrequent terms, and then emits a final pair.
Vectơ thuật ngữ theo máy chủ: Một vectơ thuật ngữ tóm tắt các từ quan trọng nhất xuất hiện trong một tài liệu hoặc một tập tài liệu dưới dạng một danh sách các cặp . Hàm map phát ra một cặp cho mỗi tài liệu đầu vào (trong đó hostname được trích xuất từ URL của tài liệu). Hàm reduce nhận tất cả các vectơ thuật ngữ theo từng tài liệu của một máy chủ cho trước. Nó cộng các vectơ thuật ngữ này lại với nhau, loại bỏ các thuật ngữ ít xuất hiện, rồi phát ra một cặp cuối cùng.
Inverted Index: The map function parses each document, and emits a sequence of pairs. The reduce function accepts all pairs for a given word, sorts the corresponding document IDs and emits a pair. The set of all output pairs forms a simple inverted index. It is easy to augment this computation to keep track of word positions.
Chỉ mục đảo: Hàm map phân tích từng tài liệu và phát ra một chuỗi các cặp . Hàm reduce nhận tất cả các cặp của một từ cho trước, sắp xếp các ID tài liệu tương ứng và phát ra một cặp . Tập hợp tất cả các cặp đầu ra tạo thành một chỉ mục đảo đơn giản. Có thể dễ dàng mở rộng phép tính này để theo dõi vị trí của các từ.
Distributed Sort: The map function extracts the key from each record, and emits a pair. The reduce function emits all pairs unchanged. This computation depends on the partitioning facilities described in Section 4.1 and the ordering properties described in Section 4.2.
Sắp xếp phân tán: Hàm map trích xuất khóa từ mỗi bản ghi và phát ra một cặp . Hàm reduce phát ra tất cả các cặp không thay đổi. Phép tính này phụ thuộc vào các cơ chế phân vùng được mô tả trong Mục 4.1 và các thuộc tính thứ tự được mô tả trong Mục 4.2.
3 Implementation
3 Cài đặt
Many different implementations of the MapReduce interface are possible. The right choice depends on the environment. For example, one implementation may be suitable for a small shared-memory machine, another for a large NUMA multi-processor, and yet another for an even larger collection of networked machines.
Có thể có nhiều cách cài đặt khác nhau cho giao diện MapReduce. Lựa chọn phù hợp phụ thuộc vào môi trường. Ví dụ, một cài đặt có thể phù hợp với một máy nhỏ có bộ nhớ chia sẻ, một cài đặt khác cho một máy đa bộ xử lý NUMA lớn, và một cài đặt khác nữa cho một tập hợp các máy được kết nối mạng thậm chí còn lớn hơn.
This section describes an implementation targeted to the computing environment in wide use at Google: large clusters of commodity PCs connected together with switched Ethernet [4]. In our environment:
Phần này mô tả một cài đặt hướng tới môi trường tính toán được sử dụng rộng rãi tại Google: các cụm lớn gồm các PC phổ thông được kết nối với nhau bằng Ethernet chuyển mạch [4]. Trong môi trường của chúng tôi:
(1) Machines are typically dual-processor x86 processors running Linux, with 2-4 GB of memory per machine.
(1) Các máy thường là các bộ xử lý x86 hai bộ xử lý chạy Linux, với 2-4 GB bộ nhớ trên mỗi máy.
(2) Commodity networking hardware is used – typically either 100 megabits/second or 1 gigabit/second at the machine level, but averaging considerably less in overall bisection bandwidth.
(2) Phần cứng mạng phổ thông được sử dụng – thường là 100 megabits/second hoặc 1 gigabit/second ở mức máy, nhưng trung bình thấp hơn đáng kể xét về băng thông chia đôi tổng thể.
(3) A cluster consists of hundreds or thousands of machines, and therefore machine failures are common.
(3) Một cluster bao gồm hàng trăm hoặc hàng nghìn máy, và do đó sự cố máy xảy ra thường xuyên.
(4) Storage is provided by inexpensive IDE disks attached directly to individual machines. A distributed file system [8] developed in-house is used to manage the data stored on these disks. The file system uses replication to provide availability and reliability on top of unreliable hardware.
(4) Lưu trữ được cung cấp bởi các ổ đĩa IDE giá rẻ được gắn trực tiếp vào từng máy riêng lẻ. Một hệ thống file phân tán [8] được phát triển nội bộ được sử dụng để quản lý dữ liệu được lưu trữ trên các ổ đĩa này. Hệ thống file sử dụng sao chép để cung cấp tính sẵn sàng và độ tin cậy trên phần cứng không đáng tin cậy.
(5) Users submit jobs to a scheduling system. Each job consists of a set of tasks, and is mapped by the scheduler to a set of available machines within a cluster.
(5) Người dùng gửi các job đến một hệ thống lập lịch. Mỗi job bao gồm một tập hợp các tác vụ, và được bộ lập lịch ánh xạ tới một tập hợp các máy khả dụng trong một cluster.
3.1 Execution Overview
3.1 Tổng quan về thực thi
The Map invocations are distributed across multiple machines by automatically partitioning the input data into a set of splits. The input splits can be processed in parallel by different machines. Reduce invocations are distributed by partitioning the intermediate key space into pieces using a partitioning function (e.g., hash(key) mod ). The number of partitions () and the partitioning function are specified by the user.
Các lời gọi Map được phân tán trên nhiều máy bằng cách tự động phân vùng dữ liệu đầu vào thành một tập hợp gồm phần chia. Các phần chia đầu vào có thể được xử lý song song bởi các máy khác nhau. Các lời gọi Reduce được phân tán bằng cách phân vùng không gian khóa trung gian thành phần bằng cách sử dụng một hàm phân vùng (ví dụ, hash(key) mod ). Số lượng phân vùng () và hàm phân vùng được người dùng chỉ định.
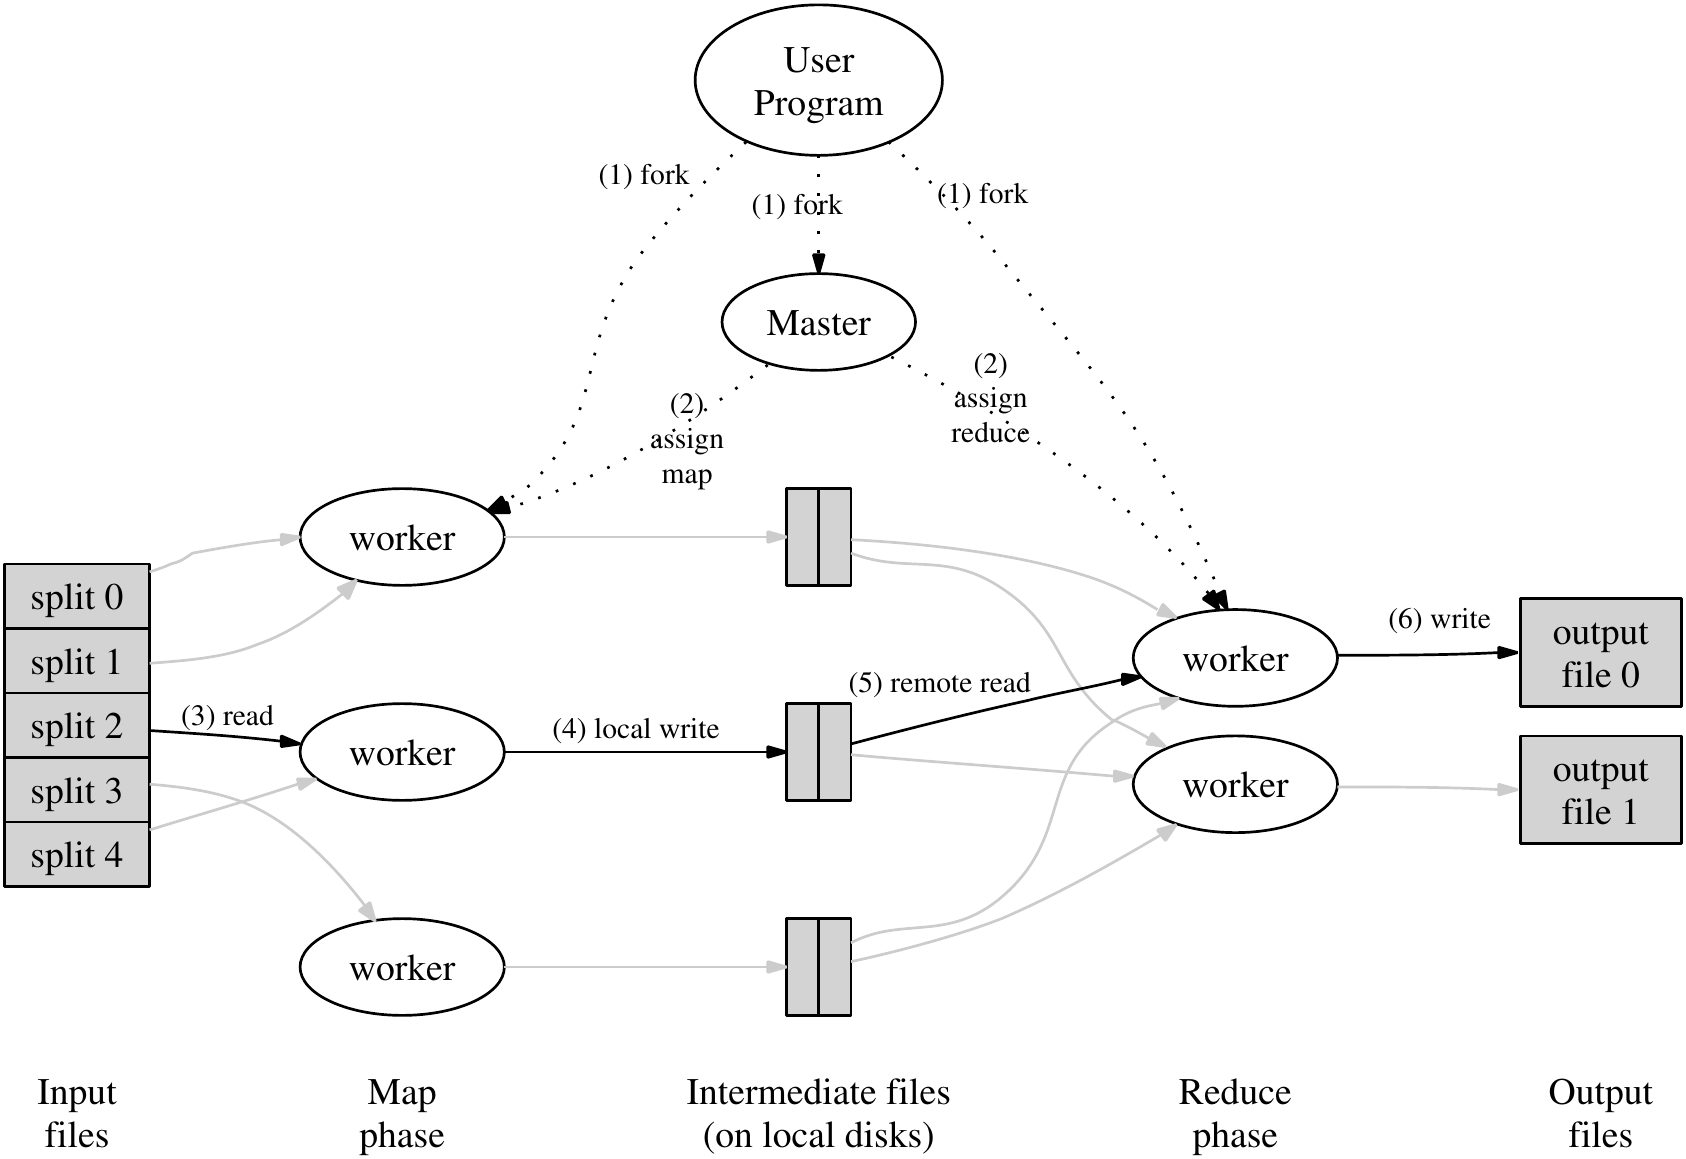
Figure 1 shows the overall flow of a MapReduce operation in our implementation. When the user program calls the MapReduce function, the following sequence of actions occurs (the numbered labels in Figure 1 correspond to the numbers in the list below):
Figure 1 cho thấy luồng tổng thể của một thao tác MapReduce trong cài đặt của chúng tôi. Khi chương trình người dùng gọi hàm MapReduce, chuỗi hành động sau đây xảy ra (các nhãn được đánh số trong Figure 1 tương ứng với các số trong danh sách dưới đây):
- The MapReduce library in the user program first splits the input files into pieces of typically 16 megabytes to 64 megabytes (MB) per piece (controllable by the user via an optional parameter). It then starts up many copies of the program on a cluster of machines.
- Thư viện MapReduce trong chương trình người dùng trước tiên chia các file đầu vào thành phần, thường có kích thước từ 16 megabytes đến 64 megabytes (MB) cho mỗi phần (có thể được người dùng điều khiển thông qua một tham số tùy chọn). Sau đó nó khởi động nhiều bản sao của chương trình trên một cluster các máy.
- One of the copies of the program is special – the master. The rest are workers that are assigned work by the master. There are map tasks and reduce tasks to assign. The master picks idle workers and assigns each one a map task or a reduce task.
- Một trong các bản sao của chương trình là đặc biệt – master. Các bản sao còn lại là các worker được master gán công việc. Có tác vụ map và tác vụ reduce cần được gán. Master chọn các worker đang rảnh và gán cho mỗi worker một tác vụ map hoặc một tác vụ reduce.
- A worker who is assigned a map task reads the contents of the corresponding input split. It parses key/value pairs out of the input data and passes each pair to the user-defined Map function. The intermediate key/value pairs produced by the Map function are buffered in memory.
- Một worker được gán một tác vụ map đọc nội dung của phần chia đầu vào tương ứng. Nó phân tích cú pháp các cặp khóa/giá trị từ dữ liệu đầu vào và truyền từng cặp cho hàm Map do người dùng định nghĩa. Các cặp khóa/giá trị trung gian được tạo bởi hàm Map được lưu trong bộ đệm trong bộ nhớ.
- Periodically, the buffered pairs are written to local disk, partitioned into regions by the partitioning function. The locations of these buffered pairs on the local disk are passed back to the master, who is responsible for forwarding these locations to the reduce workers.
- Định kỳ, các cặp được lưu trong bộ đệm được ghi vào đĩa cục bộ, được phân vùng thành vùng bởi hàm phân vùng. Vị trí của các cặp được lưu trong bộ đệm này trên đĩa cục bộ được truyền trở lại master, bộ phận chịu trách nhiệm chuyển tiếp các vị trí này tới các worker reduce.
- When a reduce worker is notified by the master about these locations, it uses remote procedure calls to read the buffered data from the local disks of the map workers. When a reduce worker has read all intermediate data, it sorts it by the intermediate keys so that all occurrences of the same key are grouped together. The sorting is needed because typically many different keys map to the same reduce task. If the amount of intermediate data is too large to fit in memory, an external sort is used.
- Khi một worker reduce được master thông báo về các vị trí này, nó sử dụng các lời gọi thủ tục từ xa để đọc dữ liệu được lưu trong bộ đệm từ các đĩa cục bộ của các worker map. Khi một worker reduce đã đọc toàn bộ dữ liệu trung gian, nó sắp xếp dữ liệu theo các khóa trung gian sao cho mọi lần xuất hiện của cùng một khóa được nhóm lại với nhau. Việc sắp xếp là cần thiết vì thông thường nhiều khóa khác nhau được ánh xạ tới cùng một tác vụ reduce. Nếu lượng dữ liệu trung gian quá lớn để vừa trong bộ nhớ, một phép sắp xếp ngoài được sử dụng.
- The reduce worker iterates over the sorted intermediate data and, for each unique intermediate key encountered, it passes the key and the corresponding set of intermediate values to the user’s Reduce function. The output of the Reduce function is appended to a final output file for this reduce partition.
- Worker reduce duyệt qua dữ liệu trung gian đã sắp xếp và với mỗi khóa trung gian duy nhất gặp được, nó truyền khóa đó cùng với tập các giá trị trung gian tương ứng tới hàm Reduce của người dùng. Đầu ra của hàm Reduce được nối thêm vào một file đầu ra cuối cùng cho phân vùng reduce này.
- When all map tasks and reduce tasks have been completed, the master wakes up the user program. At this point, the MapReduce call in the user program returns back to the user code.
- Khi tất cả các tác vụ map và tác vụ reduce đã hoàn thành, master đánh thức chương trình người dùng. Tại thời điểm này, lời gọi MapReduce trong chương trình người dùng trả quyền điều khiển trở lại mã của người dùng.
After successful completion, the output of the mapreduce execution is available in the output files (one per reduce task, with file names as specified by the user). Typically, users do not need to combine these output files into one file – they often pass these files as input to another MapReduce call, or use them from another distributed application that is able to deal with input that is partitioned into multiple files.
Sau khi hoàn thành thành công, đầu ra của thực thi mapreduce có sẵn trong các file đầu ra (mỗi file cho một tác vụ reduce, với tên file do người dùng chỉ định). Thông thường, người dùng không cần kết hợp các file đầu ra này thành một file – họ thường truyền các file này làm đầu vào cho một lời gọi MapReduce khác, hoặc sử dụng chúng từ một ứng dụng phân tán khác có khả năng xử lý đầu vào được phân vùng thành nhiều file.
3.2 Master Data Structures
3.2 Cấu trúc dữ liệu của Master
The master keeps several data structures. For each map task and reduce task, it stores the state (idle, in-progress, or completed), and the identity of the worker machine (for non-idle tasks).
Master duy trì một số cấu trúc dữ liệu. Đối với mỗi tác vụ map và tác vụ reduce, nó lưu trữ trạng thái (idle, in-progress, hoặc completed), và định danh của máy worker (đối với các tác vụ không ở trạng thái idle).
The master is the conduit through which the location of intermediate file regions is propagated from map tasks to reduce tasks. Therefore, for each completed map task, the master stores the locations and sizes of the intermediate file regions produced by the map task. Updates to this location and size information are received as map tasks are completed. The information is pushed incrementally to workers that have in-progress reduce tasks.
Master là kênh thông qua đó vị trí của các vùng file trung gian được truyền từ các tác vụ map tới các tác vụ reduce. Vì vậy, đối với mỗi tác vụ map đã hoàn thành, master lưu trữ vị trí và kích thước của vùng file trung gian được tạo ra bởi tác vụ map đó. Các cập nhật về thông tin vị trí và kích thước này được nhận khi các tác vụ map hoàn thành. Thông tin được đẩy tăng dần tới các worker đang có các tác vụ reduce đang tiến hành.
3.3 Fault Tolerance
3.3 Khả năng chịu lỗi
Since the MapReduce library is designed to help process very large amounts of data using hundreds or thousands of machines, the library must tolerate machine failures gracefully.
Vì thư viện MapReduce được thiết kế để giúp xử lý lượng dữ liệu rất lớn bằng cách sử dụng hàng trăm hoặc hàng nghìn máy, thư viện phải có khả năng chịu các sự cố máy một cách linh hoạt.
Worker Failure
Lỗi của Worker
The master pings every worker periodically. If no response is received from a worker in a certain amount of time, the master marks the worker as failed. Any map tasks completed by the worker are reset back to their initial idle state, and therefore become eligible for scheduling on other workers. Similarly, any map task or reduce task in progress on a failed worker is also reset to idle and becomes eligible for rescheduling.
Bộ master ping tới mọi worker theo định kỳ. Nếu không nhận được phản hồi từ một worker trong một khoảng thời gian nhất định, master đánh dấu worker đó là đã gặp sự cố. Bất kỳ tác vụ map nào được worker hoàn thành đều được đặt lại về trạng thái nhàn rỗi ban đầu, và do đó trở nên đủ điều kiện để được lập lịch trên các worker khác. Tương tự, bất kỳ tác vụ map hoặc reduce nào đang thực thi trên một worker đã gặp sự cố cũng được đặt lại về trạng thái nhàn rỗi và trở nên đủ điều kiện để được lập lịch lại.
Completed map tasks are re-executed on a failure because their output is stored on the local disk(s) of the failed machine and is therefore inaccessible. Completed reduce tasks do not need to be re-executed since their output is stored in a global file system.
Các tác vụ map đã hoàn thành được thực thi lại khi xảy ra sự cố vì đầu ra của chúng được lưu trên các đĩa cục bộ của máy đã gặp sự cố và do đó không thể truy cập được. Các tác vụ reduce đã hoàn thành không cần được thực thi lại vì đầu ra của chúng được lưu trong một hệ thống file toàn cục.
When a map task is executed first by worker and then later executed by worker (because failed), all workers executing reduce tasks are notified of the re-execution. Any reduce task that has not already read the data from worker A will read the data from worker B.
Khi một tác vụ map được thực thi lần đầu bởi worker và sau đó được thực thi lại bởi worker (vì đã gặp sự cố), tất cả worker đang thực thi các tác vụ reduce được thông báo về việc thực thi lại. Bất kỳ tác vụ reduce nào chưa đọc dữ liệu từ worker A sẽ đọc dữ liệu từ worker B.
MapReduce is resilient to large-scale worker failures. For example, during one MapReduce operation, network maintenance on a running cluster was causing groups of 80 machines at a time to become unreachable for several minutes. The MapReduce master simply re-executed the work done by the unreachable worker machines, and continued to make forward progress, eventually completing the MapReduce operation.
MapReduce có khả năng chống chịu với các sự cố worker ở quy mô lớn. Ví dụ, trong một phép tính MapReduce, việc bảo trì mạng trên một cluster đang chạy đã khiến các nhóm gồm 80 máy mỗi lần không thể truy cập được trong vài phút. Master MapReduce chỉ đơn giản thực thi lại công việc do các máy worker không thể truy cập thực hiện, và tiếp tục tiến triển, cuối cùng hoàn thành phép tính MapReduce.
Master Failure
Sự cố master
It is easy to make the master write periodic checkpoints of the master data structures described above. If the master task dies, a new copy can be started from the last checkpointed state. However, given that there is only a single master, its failure is unlikely; therefore our current implementation aborts the MapReduce computation if the master fails. Clients can check for this condition and retry the MapReduce operation if they desire.
Dễ dàng khiến master ghi các điểm kiểm tra định kỳ của các cấu trúc dữ liệu master được mô tả ở trên. Nếu tác vụ master bị dừng, một bản sao mới có thể được khởi động từ trạng thái được lưu tại điểm kiểm tra gần nhất. Tuy nhiên, do chỉ có một master duy nhất, khả năng xảy ra sự cố của nó là thấp; vì vậy triển khai hiện tại của chúng tôi hủy bỏ phép tính MapReduce nếu master gặp sự cố. Các máy khách có thể kiểm tra điều kiện này và thử lại phép tính MapReduce nếu muốn.
Semantics in the Presence of Failures
Ngữ nghĩa khi có sự cố
When the user-supplied map and reduce operators are deterministic functions of their input values, our distributed implementation produces the same output as would have been produced by a non-faulting sequential execution of the entire program.
Khi các toán tử map và reduce do người dùng cung cấp là các hàm tất định của các giá trị đầu vào, triển khai phân tán của chúng tôi tạo ra cùng một đầu ra như đầu ra được tạo ra bởi một thực thi tuần tự không có lỗi của toàn bộ chương trình.
We rely on atomic commits of map and reduce task outputs to achieve this property. Each in-progress task writes its output to private temporary files. A reduce task produces one such file, and a map task produces such files (one per reduce task). When a map task completes, the worker sends a message to the master and includes the names of the temporary files in the message. If the master receives a completion message for an already completed map task, it ignores the message. Otherwise, it records the names of files in a master data structure.
Chúng tôi dựa vào các lần commit nguyên tử của đầu ra của các tác vụ map và reduce để đạt được tính chất này. Mỗi tác vụ đang thực thi ghi đầu ra của nó vào các file tạm riêng tư. Một tác vụ reduce tạo ra một file như vậy, còn một tác vụ map tạo ra file như vậy (mỗi file tương ứng với một tác vụ reduce). Khi một tác vụ map hoàn thành, worker gửi một thông báo tới master và bao gồm tên của file tạm trong thông báo. Nếu master nhận được thông báo hoàn thành cho một tác vụ map đã hoàn thành trước đó, nó bỏ qua thông báo này. Ngược lại, nó ghi lại tên của file trong một cấu trúc dữ liệu master.
When a reduce task completes, the reduce worker atomically renames its temporary output file to the final output file. If the same reduce task is executed on multiple machines, multiple rename calls will be executed for the same final output file. We rely on the atomic rename operation provided by the underlying file system to guarantee that the final file system state contains just the data produced by one execution of the reduce task.
Khi một tác vụ reduce hoàn thành, worker reduce đổi tên nguyên tử file đầu ra tạm thời của nó thành file đầu ra cuối cùng. Nếu cùng một tác vụ reduce được thực thi trên nhiều máy, nhiều lời gọi đổi tên sẽ được thực hiện cho cùng một file đầu ra cuối cùng. Chúng tôi dựa vào thao tác đổi tên nguyên tử do hệ thống file bên dưới cung cấp để đảm bảo rằng trạng thái hệ thống file cuối cùng chỉ chứa dữ liệu được tạo ra bởi một lần thực thi của tác vụ reduce.
The vast majority of our map and reduce operators are deterministic, and the fact that our semantics are equivalent to a sequential execution in this case makes it very easy for programmers to reason about their program’s behavior. When the map and/or reduce operators are non-deterministic, we provide weaker but still reasonable semantics. In the presence of non-deterministic operators, the output of a particular reduce task is equivalent to the output for produced by a sequential execution of the non-deterministic program. However, the output for a different reduce task may correspond to the output for produced by a different sequential execution of the non-deterministic program.
Phần lớn các toán tử map và reduce của chúng tôi là tất định, và việc ngữ nghĩa của chúng tôi tương đương với một thực thi tuần tự trong trường hợp này khiến các lập trình viên rất dễ suy luận về hành vi của chương trình của họ. Khi các toán tử map và/hoặc reduce là không tất định, chúng tôi cung cấp ngữ nghĩa yếu hơn nhưng vẫn hợp lý. Với các toán tử không tất định, đầu ra của một tác vụ reduce cụ thể tương đương với đầu ra cho được tạo ra bởi một thực thi tuần tự của chương trình không tất định. Tuy nhiên, đầu ra của một tác vụ reduce khác có thể tương ứng với đầu ra cho được tạo ra bởi một thực thi tuần tự khác của chương trình không tất định.
Consider map task and reduce tasks and . Let be the execution of that committed (there is exactly one such execution). The weaker semantics arise because may have read the output produced by one execution of and may have read the output produced by a different execution of .
Xét tác vụ map và các tác vụ reduce và . Gọi là thực thi của đã được commit (có đúng một thực thi như vậy). Ngữ nghĩa yếu hơn xuất hiện vì có thể đã đọc đầu ra được tạo bởi một lần thực thi của và có thể đã đọc đầu ra được tạo bởi một lần thực thi khác của .
3.4 Locality
3.4 Tính cục bộ
Network bandwidth is a relatively scarce resource in our computing environment. We conserve network bandwidth by taking advantage of the fact that the input data (managed by GFS [8]) is stored on the local disks of the machines that make up our cluster. GFS divides each file into 64 MB blocks, and stores several copies of each block (typically 3 copies) on different machines. The MapReduce master takes the location information of the input files into account and attempts to schedule a map task on a machine that contains a replica of the corresponding input data. Failing that, it attempts to schedule a map task near a replica of that task’s input data (e.g., on a worker machine that is on the same network switch as the machine containing the data). When running large MapReduce operations on a significant fraction of the workers in a cluster, most input data is read locally and consumes no network bandwidth.
Băng thông mạng là một tài nguyên tương đối khan hiếm trong môi trường tính toán của chúng tôi. Chúng tôi tiết kiệm băng thông mạng bằng cách tận dụng thực tế rằng dữ liệu đầu vào (được quản lý bởi GFS [8]) được lưu trên các đĩa cục bộ của các máy tạo nên cluster của chúng tôi. GFS chia mỗi file thành các khối 64 MB, và lưu nhiều bản sao của mỗi khối (thông thường 3 bản sao) trên các máy khác nhau. Master MapReduce xem xét thông tin vị trí của các file đầu vào và cố gắng lập lịch một tác vụ map trên một máy chứa bản sao của dữ liệu đầu vào tương ứng. Nếu không thành công, nó cố gắng lập lịch một tác vụ map gần một bản sao của dữ liệu đầu vào của tác vụ đó (ví dụ, trên một máy worker nằm trên cùng bộ chuyển mạch mạng với máy chứa dữ liệu). Khi chạy các phép toán MapReduce lớn trên một phần đáng kể các worker trong một cluster, phần lớn dữ liệu đầu vào được đọc cục bộ và không tiêu tốn băng thông mạng.
3.5 Task Granularity
3.5 Độ hạt của tác vụ
We subdivide the map phase into pieces and the reduce phase into pieces, as described above. Ideally, and should be much larger than the number of worker machines. Having each worker perform many different tasks improves dynamic load balancing, and also speeds up recovery when a worker fails: the many map tasks it has completed can be spread out across all the other worker machines.
Chúng tôi chia nhỏ giai đoạn map thành phần và giai đoạn reduce thành phần, như đã mô tả ở trên. Lý tưởng nhất, và nên lớn hơn nhiều so với số lượng máy worker. Việc để mỗi worker thực hiện nhiều tác vụ khác nhau cải thiện cân bằng tải động, đồng thời cũng tăng tốc quá trình khôi phục khi một worker gặp sự cố: nhiều tác vụ map mà nó đã hoàn thành có thể được phân tán trên tất cả các máy worker khác.
There are practical bounds on how large and can be in our implementation, since the master must make scheduling decisions and keeps state in memory as described above. (The constant factors for memory usage are small however: the piece of the state consists of approximately one byte of data per map task/reduce task pair.)
Có các cận thực tế về độ lớn của và trong triển khai của chúng tôi, vì master phải đưa ra quyết định lập lịch và duy trì trạng thái trong bộ nhớ như đã mô tả ở trên. (Tuy nhiên, các hệ số hằng của việc sử dụng bộ nhớ là nhỏ: phần của trạng thái bao gồm xấp xỉ một byte dữ liệu cho mỗi cặp tác vụ map/tác vụ reduce.)
Furthermore, is often constrained by users because the output of each reduce task ends up in a separate output file. In practice, we tend to choose so that each individual task is roughly 16 MB to 64 MB of input data (so that the locality optimization described above is most effective), and we make a small multiple of the number of worker machines we expect to use. We often perform MapReduce computations with and , using 2,000 worker machines.
Hơn nữa, thường bị người dùng giới hạn vì đầu ra của mỗi tác vụ reduce cuối cùng được ghi vào một file đầu ra riêng biệt. Trong thực tế, chúng tôi có xu hướng chọn sao cho mỗi tác vụ riêng lẻ có khoảng 16 MB đến 64 MB dữ liệu đầu vào (để tối ưu hóa locality được mô tả ở trên đạt hiệu quả cao nhất), và chúng tôi đặt là một bội số nhỏ của số máy worker mà chúng tôi dự kiến sử dụng. Chúng tôi thường thực hiện các tính toán MapReduce với và , sử dụng 2,000 máy worker.
3.6 Backup Tasks
3.6 Các tác vụ dự phòng
One of the common causes that lengthens the total time taken for a MapReduce operation is a “straggler”: a machine that takes an unusually long time to complete one of the last few map or reduce tasks in the computation. Stragglers can arise for a whole host of reasons. For example, a machine with a bad disk may experience frequent correctable errors that slow its read performance from 30 MB/s to 1 MB/s. The cluster scheduling system may have scheduled other tasks on the machine, causing it to execute the MapReduce code more slowly due to competition for CPU, memory, local disk, or network bandwidth. A recent problem we experienced was a bug in machine initialization code that caused processor caches to be disabled: computations on affected machines slowed down by over a factor of one hundred.
Một trong những nguyên nhân phổ biến làm kéo dài tổng thời gian thực hiện một thao tác MapReduce là một “straggler”: một máy mất thời gian dài bất thường để hoàn thành một trong vài tác vụ map hoặc reduce cuối cùng trong phép tính. Straggler có thể phát sinh do rất nhiều nguyên nhân. Ví dụ, một máy có ổ đĩa bị lỗi có thể gặp các lỗi có thể sửa chữa thường xuyên làm giảm hiệu năng đọc của nó từ 30 MB/s xuống 1 MB/s. Hệ thống lập lịch cụm có thể đã lập lịch các tác vụ khác trên máy đó, khiến nó thực thi mã MapReduce chậm hơn do cạnh tranh về CPU, bộ nhớ, ổ đĩa cục bộ hoặc băng thông mạng. Một vấn đề gần đây mà chúng tôi gặp phải là một lỗi trong mã khởi tạo máy khiến các cache của bộ xử lý bị vô hiệu hóa: các phép tính trên những máy bị ảnh hưởng chậm hơn hơn một trăm lần.
We have a general mechanism to alleviate the problem of stragglers. When a MapReduce operation is close to completion, the master schedules backup executions of the remaining in-progress tasks. The task is marked as completed whenever either the primary or the backup execution completes. We have tuned this mechanism so that it typically increases the computational resources used by the operation by no more than a few percent. We have found that this significantly reduces the time to complete large MapReduce operations. As an example, the sort program described in Section 5.3 takes 44% longer to complete when the backup task mechanism is disabled.
Chúng tôi có một cơ chế tổng quát để giảm nhẹ vấn đề của các straggler. Khi một thao tác MapReduce gần hoàn thành, master lập lịch các thực thi dự phòng của các tác vụ còn đang tiến hành. Tác vụ được đánh dấu là đã hoàn thành bất cứ khi nào thực thi chính hoặc thực thi dự phòng hoàn thành. Chúng tôi đã tinh chỉnh cơ chế này để nó thường làm tăng các tài nguyên tính toán được sử dụng bởi thao tác không quá vài phần trăm. Chúng tôi nhận thấy rằng cơ chế này làm giảm đáng kể thời gian hoàn thành các thao tác MapReduce lớn. Ví dụ, chương trình sort được mô tả trong Section 5.3 mất nhiều hơn 44% thời gian để hoàn thành khi cơ chế tác vụ dự phòng bị vô hiệu hóa.
4 Refinements
4 Các tinh chỉnh
Although the basic functionality provided by simply writing Map and Reduce functions is sufficient for most needs, we have found a few extensions useful. These are described in this section.
Mặc dù chức năng cơ bản được cung cấp chỉ bằng cách viết các hàm Map và Reduce là đủ cho hầu hết nhu cầu, chúng tôi đã nhận thấy một vài phần mở rộng hữu ích. Các phần mở rộng này được mô tả trong phần này.
4.1 Partitioning Function
4.1 Hàm phân vùng
The users of MapReduce specify the number of reduce tasks/output files that they desire (). Data gets partitioned across these tasks using a partitioning function on the intermediate key. A default partitioning function is provided that uses hashing (e.g. “hash(key) mod ”). This tends to result in fairly well-balanced partitions. In some cases, however, it is useful to partition data by some other function of the key. For example, sometimes the output keys are URLs, and we want all entries for a single host to end up in the same output file. To support situations like this, the user of the MapReduce library can provide a special partitioning function. For example, using “hash(Hostname(urlkey)) mod ” as the partitioning function causes all URLs from the same host to end up in the same output file.
Người dùng MapReduce chỉ định số lượng tác vụ reduce/tệp đầu ra mà họ mong muốn (). Dữ liệu được phân vùng trên các tác vụ này bằng cách sử dụng một hàm phân vùng trên khóa trung gian. Một hàm phân vùng mặc định được cung cấp, sử dụng phép băm (ví dụ: “hash(key) mod ”). Điều này thường tạo ra các phân vùng được cân bằng khá tốt. Tuy nhiên, trong một số trường hợp, việc phân vùng dữ liệu bằng một hàm khác của khóa là hữu ích. Ví dụ, đôi khi các khóa đầu ra là các URL, và chúng tôi muốn tất cả các mục nhập cho một host duy nhất kết thúc trong cùng một tệp đầu ra. Để hỗ trợ các tình huống như vậy, người dùng của thư viện MapReduce có thể cung cấp một hàm phân vùng đặc biệt. Ví dụ, sử dụng “hash(Hostname(urlkey)) mod ” làm hàm phân vùng khiến tất cả URL từ cùng một host kết thúc trong cùng một tệp đầu ra.
4.2 Ordering Guarantees
4.2 Các đảm bảo về thứ tự
We guarantee that within a given partition, the intermediate key/value pairs are processed in increasing key order. This ordering guarantee makes it easy to produce a sorted output file per partition, which is useful when the output file format needs to support efficient random access lookups by key, or users of the output find it convenient to have the data sorted.
Chúng tôi đảm bảo rằng trong một phân vùng nhất định, các cặp khóa/giá trị trung gian được xử lý theo thứ tự khóa tăng dần. Đảm bảo về thứ tự này giúp dễ dàng tạo ra một tệp đầu ra đã sắp xếp cho mỗi phân vùng, điều này hữu ích khi định dạng tệp đầu ra cần hỗ trợ các thao tác tra cứu truy cập ngẫu nhiên hiệu quả theo khóa, hoặc người dùng của đầu ra thấy thuận tiện khi dữ liệu được sắp xếp.
4.3 Combiner Function
4.3 Hàm Combiner
In some cases, there is significant repetition in the intermediate keys produced by each map task, and the user-specified Reduce function is commutative and associative. A good example of this is the word counting example in Section 2.1. Since word frequencies tend to follow a Zipf distribution, each map task will produce hundreds or thousands of records of the form . All of these counts will be sent over the network to a single reduce task and then added together by the Reduce function to produce one number. We allow the user to specify an optional Combiner function that does partial merging of this data before it is sent over the network.
Trong một số trường hợp, có sự lặp lại đáng kể trong các khóa trung gian được tạo ra bởi mỗi tác vụ map, và hàm Reduce do người dùng chỉ định có tính giao hoán và kết hợp. Một ví dụ điển hình là ví dụ đếm từ trong Section 2.1. Vì tần suất từ có xu hướng tuân theo phân phối Zipf, mỗi tác vụ map sẽ tạo ra hàng trăm hoặc hàng nghìn bản ghi có dạng . Tất cả các số đếm này sẽ được gửi qua mạng đến một tác vụ reduce duy nhất và sau đó được cộng lại bởi hàm Reduce để tạo ra một số. Chúng tôi cho phép người dùng chỉ định một hàm Combiner tùy chọn thực hiện việc gộp một phần dữ liệu này trước khi nó được gửi qua mạng.
The Combiner function is executed on each machine that performs a map task. Typically the same code is used to implement both the combiner and the reduce functions. The only difference between a reduce function and a combiner function is how the MapReduce library handles the output of the function. The output of a reduce function is written to the final output file. The output of a combiner function is written to an intermediate file that will be sent to a reduce task.
Hàm Combiner được thực thi trên mỗi máy thực hiện một tác vụ map. Thông thường cùng một mã được sử dụng để triển khai cả hàm combiner và hàm reduce. Khác biệt duy nhất giữa một hàm reduce và một hàm combiner là cách thư viện MapReduce xử lý đầu ra của hàm. Đầu ra của một hàm reduce được ghi vào tệp đầu ra cuối cùng. Đầu ra của một hàm combiner được ghi vào một tệp trung gian sẽ được gửi đến một tác vụ reduce.
Partial combining significantly speeds up certain classes of MapReduce operations. Appendix A contains an example that uses a combiner.
Việc kết hợp một phần giúp tăng tốc đáng kể một số lớp thao tác MapReduce. Appendix A chứa một ví dụ sử dụng một combiner.
4.4 Input and Output Types
4.4 Các kiểu đầu vào và đầu ra
The MapReduce library provides support for reading input data in several different formats. For example, “text” mode input treats each line as a key/value pair: the key is the offset in the file and the value is the contents of the line. Another common supported format stores a sequence of key/value pairs sorted by key. Each input type implementation knows how to split itself into meaningful ranges for processing as separate map tasks (e.g. text mode’s range splitting ensures that range splits occur only at line boundaries). Users can add support for a new input type by providing an implementation of a simple reader interface, though most users just use one of a small number of predefined input types.
Thư viện MapReduce cung cấp hỗ trợ đọc dữ liệu đầu vào ở nhiều định dạng khác nhau. Ví dụ, đầu vào ở chế độ “text” xem mỗi dòng là một cặp khóa/giá trị: khóa là vị trí lệch trong tệp và giá trị là nội dung của dòng. Một định dạng được hỗ trợ phổ biến khác lưu trữ một chuỗi các cặp khóa/giá trị được sắp xếp theo khóa. Mỗi triển khai kiểu đầu vào biết cách chia chính nó thành các phạm vi có ý nghĩa để xử lý như các tác vụ map riêng biệt (ví dụ: việc chia phạm vi của chế độ text đảm bảo rằng các điểm chia phạm vi chỉ xảy ra tại ranh giới dòng). Người dùng có thể thêm hỗ trợ cho một kiểu đầu vào mới bằng cách cung cấp một triển khai của giao diện reader đơn giản, mặc dù hầu hết người dùng chỉ sử dụng một trong một số ít kiểu đầu vào được định nghĩa trước.
A reader does not necessarily need to provide data read from a file. For example, it is easy to define a reader that reads records from a database, or from data structures mapped in memory.
Một reader không nhất thiết cần cung cấp dữ liệu được đọc từ một tệp. Ví dụ, dễ dàng định nghĩa một reader đọc các bản ghi từ một cơ sở dữ liệu, hoặc từ các cấu trúc dữ liệu được ánh xạ trong bộ nhớ.
In a similar fashion, we support a set of output types for producing data in different formats and it is easy for user code to add support for new output types.
Theo cách tương tự, chúng tôi hỗ trợ một tập hợp các kiểu đầu ra để tạo dữ liệu ở các định dạng khác nhau và mã người dùng dễ dàng thêm hỗ trợ cho các kiểu đầu ra mới.
4.5 Side-effects
4.5 Side-effects
In some cases, users of MapReduce have found it convenient to produce auxiliary files as additional outputs from their map and/or reduce operators. We rely on the application writer to make such side-effects atomic and idempotent. Typically the application writes to a temporary file and atomically renames this file once it has been fully generated.
Trong một số trường hợp, người dùng MapReduce nhận thấy thuận tiện khi tạo các tệp phụ như các đầu ra bổ sung từ các toán tử map và/hoặc reduce của họ. Chúng tôi dựa vào người viết ứng dụng để làm cho các side-effect như vậy có tính nguyên tử và idempotent. Thông thường ứng dụng ghi vào một tệp tạm thời và đổi tên nguyên tử tệp này sau khi nó đã được tạo hoàn chỉnh.
We do not provide support for atomic two-phase commits of multiple output files produced by a single task. Therefore, tasks that produce multiple output files with cross-file consistency requirements should be deterministic. This restriction has never been an issue in practice.
Chúng tôi không cung cấp hỗ trợ cho các commit hai pha nguyên tử của nhiều tệp đầu ra được tạo bởi một tác vụ duy nhất. Vì vậy, các tác vụ tạo ra nhiều tệp đầu ra với các yêu cầu về tính nhất quán giữa các tệp nên có tính xác định. Hạn chế này chưa từng là một vấn đề trong thực tế.
4.6 Skipping Bad Records
4.6 Bỏ qua các bản ghi lỗi
Sometimes there are bugs in user code that cause the Map or Reduce functions to crash deterministically on certain records. Such bugs prevent a MapReduce operation from completing. The usual course of action is to fix the bug, but sometimes this is not feasible; perhaps the bug is in a third-party library for which source code is unavailable. Also, sometimes it is acceptable to ignore a few records, for example when doing statistical analysis on a large data set. We provide an optional mode of execution where the MapReduce library detects which records cause deterministic crashes and skips these records in order to make forward progress.
Đôi khi có các lỗi trong mã người dùng khiến các hàm Map hoặc Reduce bị crash một cách xác định trên một số bản ghi nhất định. Các lỗi như vậy ngăn một thao tác MapReduce hoàn thành. Cách xử lý thông thường là sửa lỗi, nhưng đôi khi điều này không khả thi; có thể lỗi nằm trong một thư viện bên thứ ba mà mã nguồn không có sẵn. Ngoài ra, đôi khi việc bỏ qua một vài bản ghi là chấp nhận được, ví dụ khi thực hiện phân tích thống kê trên một tập dữ liệu lớn. Chúng tôi cung cấp một chế độ thực thi tùy chọn trong đó thư viện MapReduce phát hiện các bản ghi gây ra crash xác định và bỏ qua các bản ghi này để tiếp tục tiến trình.
Each worker process installs a signal handler that catches segmentation violations and bus errors. Before invoking a user Map or Reduce operation, the MapReduce library stores the sequence number of the argument in a global variable. If the user code generates a signal, the signal handler sends a “last gasp” UDP packet that contains the sequence number to the MapReduce master. When the master has seen more than one failure on a particular record, it indicates that the record should be skipped when it issues the next re-execution of the corresponding Map or Reduce task.
Mỗi tiến trình worker cài đặt một bộ xử lý tín hiệu bắt các lỗi vi phạm phân đoạn và lỗi bus. Trước khi gọi một thao tác Map hoặc Reduce của người dùng, thư viện MapReduce lưu số thứ tự của đối số vào một biến toàn cục. Nếu mã nguồn của người dùng tạo ra một tín hiệu, bộ xử lý tín hiệu gửi một gói UDP “last gasp” chứa số thứ tự tới master MapReduce. Khi master đã thấy nhiều hơn một sự cố trên một bản ghi cụ thể, nó chỉ ra rằng bản ghi đó nên được bỏ qua khi nó phát hành lần thực thi lại tiếp theo của tác vụ Map hoặc Reduce tương ứng.
4.7 Local Execution
4.7 Thực thi cục bộ
Debugging problems in Map or Reduce functions can be tricky, since the actual computation happens in a distributed system, often on several thousand machines, with work assignment decisions made dynamically by the master. To help facilitate debugging, profiling, and small-scale testing, we have developed an alternative implementation of the MapReduce library that sequentially executes all of the work for a MapReduce operation on the local machine. Controls are provided to the user so that the computation can be limited to particular map tasks. Users invoke their program with a special flag and can then easily use any debugging or testing tools they find useful (e.g. gdb).
Việc gỡ lỗi các vấn đề trong các hàm Map hoặc Reduce có thể phức tạp, vì tính toán thực tế diễn ra trong một hệ thống phân tán, thường trên vài nghìn máy, với các quyết định gán công việc được master đưa ra một cách động. Để hỗ trợ việc gỡ lỗi, lập hồ sơ và kiểm thử quy mô nhỏ, chúng tôi đã phát triển một triển khai thay thế của thư viện MapReduce, thực thi tuần tự toàn bộ công việc của một thao tác MapReduce trên máy cục bộ. Các điều khiển được cung cấp cho người dùng để tính toán có thể được giới hạn ở các tác vụ map cụ thể. Người dùng gọi chương trình của họ với một cờ đặc biệt và sau đó có thể dễ dàng sử dụng bất kỳ công cụ gỡ lỗi hoặc kiểm thử nào mà họ thấy hữu ích (ví dụ: gdb).
4.8 Status Information
4.8 Thông tin trạng thái
The master runs an internal HTTP server and exports a set of status pages for human consumption. The status pages show the progress of the computation, such as how many tasks have been completed, how many are in progress, bytes of input, bytes of intermediate data, bytes of output, processing rates, etc. The pages also contain links to the standard error and standard output files generated by each task. The user can use this data to predict how long the computation will take, and whether or not more resources should be added to the computation. These pages can also be used to figure out when the computation is much slower than expected.
Master chạy một server HTTP nội bộ và xuất ra một tập hợp các trang trạng thái để con người sử dụng. Các trang trạng thái hiển thị tiến trình của tính toán, chẳng hạn như có bao nhiêu tác vụ đã hoàn thành, bao nhiêu tác vụ đang được thực hiện, byte của đầu vào, byte của dữ liệu trung gian, byte của đầu ra, tốc độ xử lý, v.v. Các trang này cũng chứa các liên kết tới các file lỗi tiêu chuẩn và đầu ra tiêu chuẩn được tạo bởi mỗi tác vụ. Người dùng có thể sử dụng dữ liệu này để dự đoán tính toán sẽ mất bao lâu và liệu có nên thêm nhiều tài nguyên hơn vào tính toán hay không. Các trang này cũng có thể được sử dụng để xác định khi nào tính toán chậm hơn nhiều so với dự kiến.
In addition, the top-level status page shows which workers have failed, and which map and reduce tasks they were processing when they failed. This information is useful when attempting to diagnose bugs in the user code.
Ngoài ra, trang trạng thái cấp cao nhất hiển thị những worker nào đã gặp sự cố, và những tác vụ map và reduce nào chúng đang xử lý khi gặp sự cố. Thông tin này hữu ích khi cố gắng chẩn đoán lỗi trong mã nguồn của người dùng.
4.9 Counters
4.9 Bộ đếm
The MapReduce library provides a counter facility to count occurrences of various events. For example, user code may want to count total number of words processed or the number of German documents indexed, etc.
Thư viện MapReduce cung cấp một tiện ích bộ đếm để đếm sự xuất hiện của các sự kiện khác nhau. Ví dụ, mã nguồn của người dùng có thể muốn đếm tổng số từ đã được xử lý hoặc số tài liệu tiếng Đức đã được lập chỉ mục, v.v.
To use this facility, user code creates a named counter object and then increments the counter appropriately in the Map and/or Reduce function. For example:
Để sử dụng tiện ích này, mã nguồn của người dùng tạo một đối tượng bộ đếm có tên và sau đó tăng bộ đếm một cách thích hợp trong hàm Map và/hoặc Reduce. Ví dụ:
              Counter* uppercase;
uppercase = GetCounter("uppercase");

map(String name, String contents):
  for each word w in contents:
    if (IsCapitalized(w)):
      uppercase->Increment();
    EmitIntermediate(w, "1");
              Counter* uppercase;
uppercase = GetCounter("uppercase");

map(String name, String contents):
  for each word w in contents:
    if (IsCapitalized(w)):
      uppercase->Increment();
    EmitIntermediate(w, "1");
The counter values from individual worker machines are periodically propagated to the master (piggybacked on the ping response). The master aggregates the counter values from successful map and reduce tasks and returns them to the user code when the MapReduce operation is completed. The current counter values are also displayed on the master status page so that a human can watch the progress of the live computation. When aggregating counter values, the master eliminates the effects of duplicate executions of the same map or reduce task to avoid double counting. (Duplicate executions can arise from our use of backup tasks and from re-execution of tasks due to failures.)
Các giá trị bộ đếm từ từng máy worker được truyền định kỳ tới master (được gắn kèm trong phản hồi ping). Master tổng hợp các giá trị bộ đếm từ các tác vụ map và reduce thành công và trả chúng về mã nguồn của người dùng khi thao tác MapReduce hoàn tất. Các giá trị bộ đếm hiện tại cũng được hiển thị trên trang trạng thái của master để con người có thể theo dõi tiến trình của tính toán đang chạy. Khi tổng hợp các giá trị bộ đếm, master loại bỏ ảnh hưởng của các lần thực thi trùng lặp của cùng một tác vụ map hoặc reduce để tránh đếm kép. (Các lần thực thi trùng lặp có thể phát sinh từ việc chúng tôi sử dụng các tác vụ sao lưu và từ việc thực thi lại các tác vụ do sự cố.)
Some counter values are automatically maintained by the MapReduce library, such as the number of input key/value pairs processed and the number of output key/value pairs produced.
Một số giá trị bộ đếm được thư viện MapReduce tự động duy trì, chẳng hạn như số cặp khóa/giá trị đầu vào đã được xử lý và số cặp khóa/giá trị đầu ra đã được tạo ra.
Users have found the counter facility useful for sanity checking the behavior of MapReduce operations. For example, in some MapReduce operations, the user code may want to ensure that the number of output pairs produced exactly equals the number of input pairs processed, or that the fraction of German documents processed is within some tolerable fraction of the total number of documents processed.
Người dùng nhận thấy tiện ích bộ đếm hữu ích để kiểm tra tính hợp lý của hành vi các thao tác MapReduce. Ví dụ, trong một số thao tác MapReduce, mã nguồn của người dùng có thể muốn đảm bảo rằng số cặp đầu ra được tạo ra chính xác bằng số cặp đầu vào đã được xử lý, hoặc rằng tỷ lệ tài liệu tiếng Đức được xử lý nằm trong một tỷ lệ chấp nhận được nào đó của tổng số tài liệu đã được xử lý.
5 Performance
5 Hiệu năng
In this section we measure the performance of MapReduce on two computations running on a large cluster of machines. One computation searches through approximately one terabyte of data looking for a particular pattern. The other computation sorts approximately one terabyte of data.
Trong phần này, chúng tôi đo hiệu năng của MapReduce trên hai phép tính chạy trên một cụm lớn gồm nhiều máy. Một phép tính tìm kiếm trong khoảng một terabyte dữ liệu để tìm một mẫu cụ thể. Phép tính còn lại sắp xếp khoảng một terabyte dữ liệu.
These two programs are representative of a large subset of the real programs written by users of MapReduce – one class of programs shuffles data from one representation to another, and another class extracts a small amount of interesting data from a large data set.
Hai chương trình này đại diện cho một tập con lớn các chương trình thực tế do người dùng MapReduce viết – một lớp chương trình xáo trộn dữ liệu từ một biểu diễn này sang một biểu diễn khác, và một lớp khác trích xuất một lượng nhỏ dữ liệu đáng quan tâm từ một tập dữ liệu lớn.
5.1 Cluster Configuration
5.1 Cấu hình cụm
All of the programs were executed on a cluster that consisted of approximately 1800 machines. Each machine had two 2GHz Intel Xeon processors with Hyper-Threading enabled, 4GB of memory, two 160GB IDE disks, and a gigabit Ethernet link. The machines were arranged in a two-level tree-shaped switched network with approximately 100-200 Gbps of aggregate bandwidth available at the root. All of the machines were in the same hosting facility and therefore the round-trip time between any pair of machines was less than a millisecond.
Tất cả các chương trình được thực thi trên một cụm gồm khoảng 1800 máy. Mỗi máy có hai bộ xử lý Intel Xeon 2GHz với Hyper-Threading được bật, 4GB bộ nhớ, hai ổ đĩa IDE 160GB và một liên kết Ethernet gigabit. Các máy được bố trí trong một mạng chuyển mạch hình cây hai cấp với băng thông tổng hợp khoảng 100-200 Gbps khả dụng tại nút gốc. Tất cả các máy nằm trong cùng một cơ sở lưu trữ và do đó thời gian khứ hồi giữa bất kỳ cặp máy nào đều nhỏ hơn một mili giây.
Out of the 4GB of memory, approximately 1-1.5GB was reserved by other tasks running on the cluster. The programs were executed on a weekend afternoon, when the CPUs, disks, and network were mostly idle.
Trong 4GB bộ nhớ, khoảng 1-1.5GB được dành riêng cho các tác vụ khác đang chạy trên cụm. Các chương trình được thực thi vào một buổi chiều cuối tuần, khi CPU, ổ đĩa và mạng phần lớn ở trạng thái nhàn rỗi.
5.2 Grep
5.2 Grep
The grep program scans through 100-byte records, searching for a relatively rare three-character pattern (the pattern occurs in 92,337 records). The input is split into approximately 64MB pieces (), and the entire output is placed in one file ().
Chương trình grep quét qua bản ghi 100-byte, tìm kiếm một mẫu ba ký tự tương đối hiếm (mẫu xuất hiện trong 92,337 bản ghi). Đầu vào được chia thành các phần khoảng 64MB (), và toàn bộ đầu ra được đặt trong một file ().
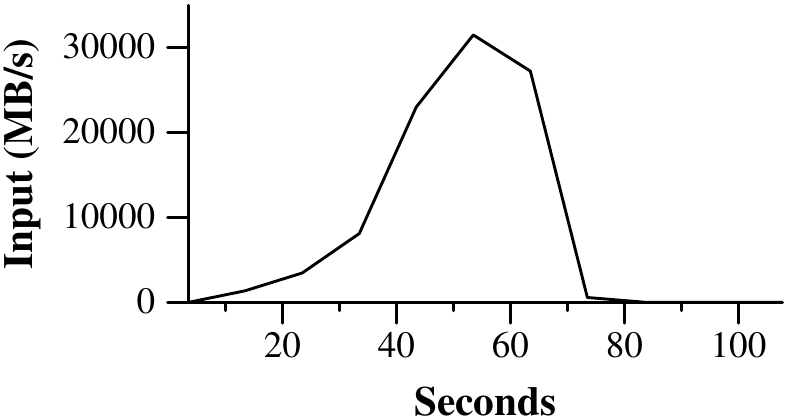
Figure 2 shows the progress of the computation over time. The Y-axis shows the rate at which the input data is scanned. The rate gradually picks up as more machines are assigned to this MapReduce computation, and peaks at over 30 GB/s when 1764 workers have been assigned. As the map task finishes, the rate starts dropping and hits zero about 80 seconds into the computation. The entire computation takes approximately 150 seconds from start to finish. This includes about a minute of startup overhead. The overhead is due to the propagation of the program to all worker machines, and delays interacting with GFS to open the set of 1000 input files and to get the information needed for the locality optimization.
Hình 2 cho thấy tiến trình của phép tính theo thời gian. Trục Y biểu diễn tốc độ quét dữ liệu đầu vào. Tốc độ tăng dần khi có thêm máy được phân công cho phép tính MapReduce này, và đạt đỉnh trên 30 GB/s khi 1764 worker được phân công. Khi tác vụ map hoàn tất, tốc độ bắt đầu giảm và chạm mức 0 khoảng 80 giây sau khi phép tính bắt đầu. Toàn bộ phép tính mất khoảng 150 giây từ đầu đến cuối. Khoảng một phút trong số đó là chi phí phụ trội khởi động. Chi phí phụ trội này là do việc truyền chương trình đến tất cả các máy worker, cũng như các độ trễ khi tương tác với GFS để mở tập gồm 1000 file đầu vào và lấy thông tin cần thiết cho tối ưu hóa tính cục bộ.
5.3 Sort
5.3 Sort
The sort program sorts 100-byte records (approximately one terabyte of data). This program is modeled after the TeraSort benchmark [10].
Chương trình sort sắp xếp bản ghi 100-byte (khoảng một terabyte dữ liệu). Chương trình này được mô hình hóa theo phép đo chuẩn TeraSort [10].
The sorting program consists of less than 50 lines of user code. A three-line Map function extracts a 10-byte sorting key from a text line and emits the key and the
Chương trình sắp xếp gồm chưa đến 50 dòng mã của người dùng. Một hàm Map ba dòng trích xuất một khóa sắp xếp 10-byte từ một dòng văn bản và phát ra khóa cùng
(a) Normal execution
(a) Thực thi bình thường
(b) No backup tasks
(b) Không có tác vụ dự phòng
(c) 200 tasks killed original text line as the intermediate key/value pair. We used a built-in Identity function as the Reduce operator. This function passes the intermediate key/value pair unchanged as the output key/value pair. The final sorted output is written to a set of 2-way replicated GFS files (i.e., 2 terabytes are written as the output of the program).
(c) 200 tác vụ bị hủy dòng văn bản gốc dưới dạng cặp khóa/giá trị trung gian. Chúng tôi sử dụng hàm Identity tích hợp sẵn làm toán tử Reduce. Hàm này truyền cặp khóa/giá trị trung gian không thay đổi thành cặp khóa/giá trị đầu ra. Đầu ra đã sắp xếp cuối cùng được ghi vào một tập các file GFS được sao chép 2 chiều (tức là 2 terabyte được ghi làm đầu ra của chương trình).
As before, the input data is split into 64MB pieces (). We partition the sorted output into 4000 files (). The partitioning function uses the initial bytes of the key to segregate it into one of pieces.
Như trước đây, dữ liệu đầu vào được chia thành các phần 64MB (). Chúng tôi phân vùng đầu ra đã sắp xếp thành 4000 file (). Hàm phân vùng sử dụng các byte đầu tiên của khóa để phân tách nó vào một trong phần.
Our partitioning function for this benchmark has built-in knowledge of the distribution of keys. In a general sorting program, we would add a pre-pass MapReduce operation that would collect a sample of the keys and use the distribution of the sampled keys to compute split-points for the final sorting pass.
Hàm phân vùng của chúng tôi cho phép đo chuẩn này có kiến thức tích hợp về phân phối của các khóa. Trong một chương trình sắp xếp tổng quát, chúng tôi sẽ thêm một phép tính MapReduce tiền xử lý để thu thập một mẫu các khóa và sử dụng phân phối của các khóa được lấy mẫu để tính các điểm phân tách cho lượt sắp xếp cuối cùng.
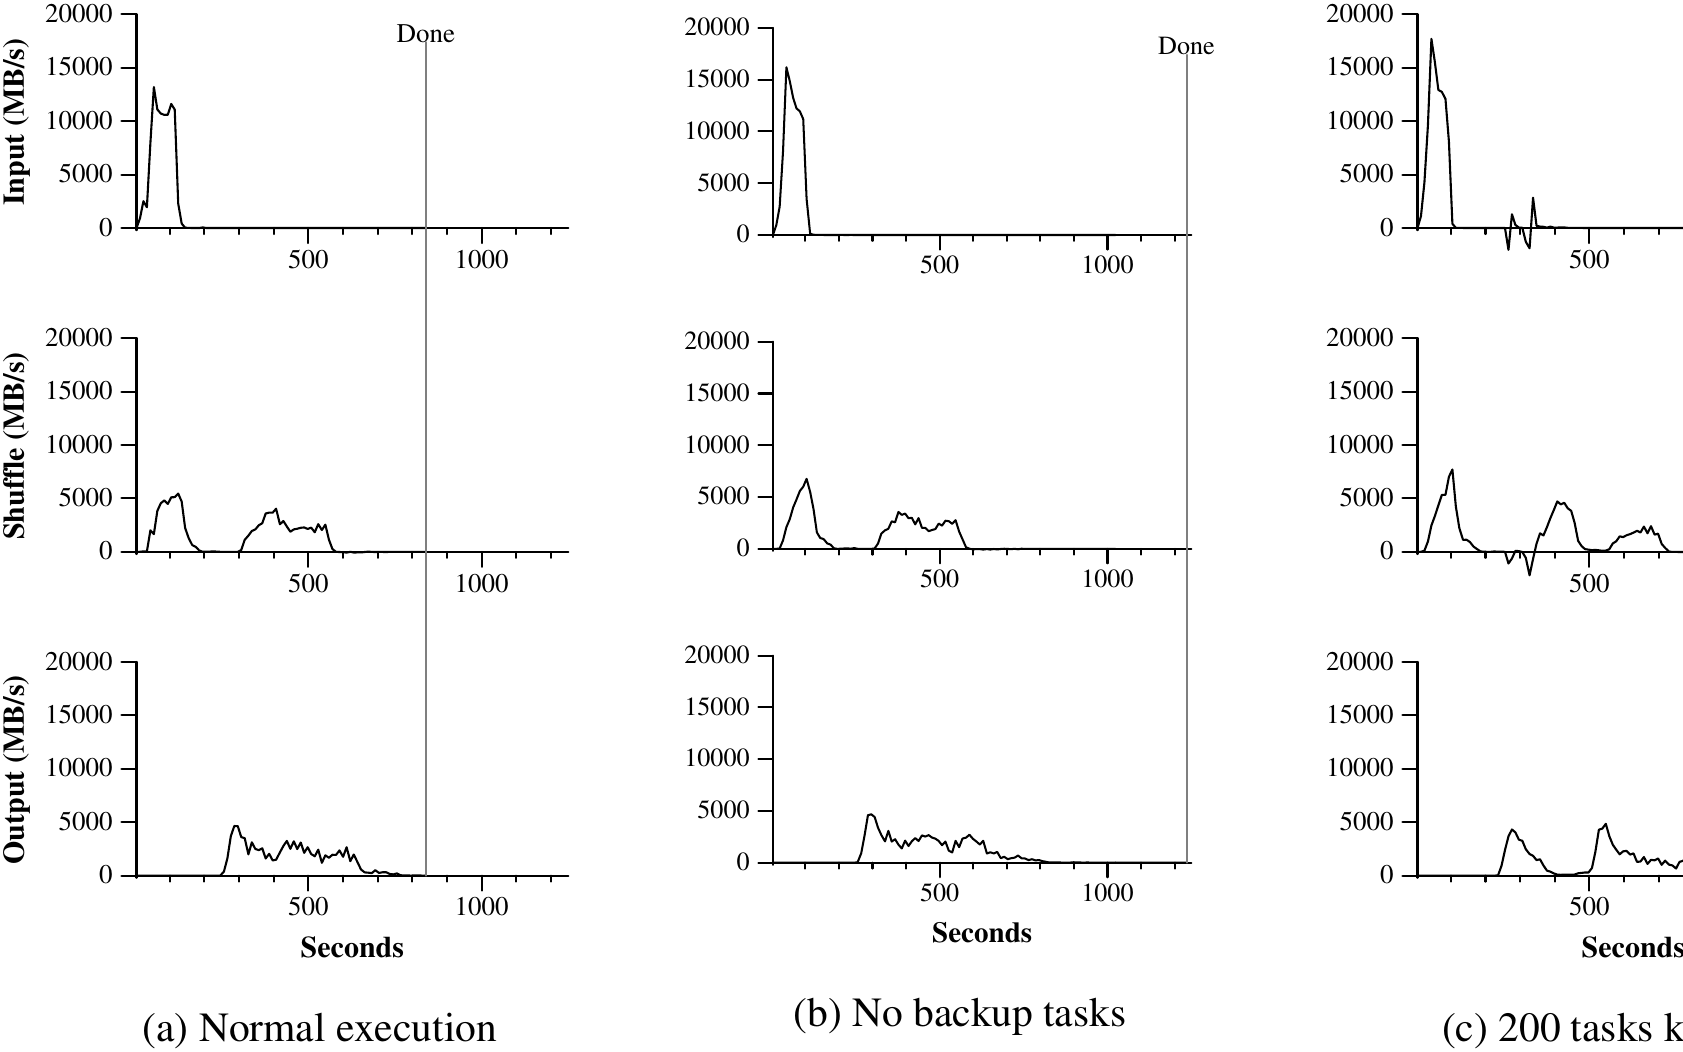
Figure 3 (a) shows the progress of a normal execution of the sort program. The top-left graph shows the rate at which input is read. The rate peaks at about 13 GB/s and dies off fairly quickly since all map tasks finish before 200 seconds have elapsed. Note that the input rate is less than that for grep. This is because the sort map tasks spend about half their time and I/O bandwidth writing intermediate output to their local disks. The corresponding intermediate output for grep had negligible size.
Hình 3 (a) cho thấy tiến trình của một lần thực thi bình thường của chương trình sort. Đồ thị phía trên bên trái cho thấy tốc độ đọc đầu vào. Tốc độ đạt đỉnh khoảng 13 GB/s và giảm khá nhanh vì tất cả các tác vụ map hoàn tất trước khi 200 giây trôi qua. Lưu ý rằng tốc độ đầu vào thấp hơn so với grep. Điều này là do các tác vụ map của sort dành khoảng một nửa thời gian và băng thông I/O để ghi đầu ra trung gian vào các ổ đĩa cục bộ của chúng. Đầu ra trung gian tương ứng của grep có kích thước không đáng kể.
The middle-left graph shows the rate at which data is sent over the network from the map tasks to the reduce tasks. This shuffling starts as soon as the first map task completes. The first hump in the graph is for the first batch of approximately 1700 reduce tasks (the entire MapReduce was assigned about 1700 machines, and each machine executes at most one reduce task at a time). Roughly 300 seconds into the computation, some of these first batch of reduce tasks finish and we start shuffling data for the remaining reduce tasks. All of the shuffling is done about 600 seconds into the computation.
Đồ thị phía giữa bên trái cho thấy tốc độ dữ liệu được gửi qua mạng từ các tác vụ map đến các tác vụ reduce. Việc xáo trộn này bắt đầu ngay khi tác vụ map đầu tiên hoàn tất. Đỉnh đầu tiên trong đồ thị tương ứng với lô đầu tiên gồm khoảng 1700 tác vụ reduce (toàn bộ MapReduce được phân công cho khoảng 1700 máy, và mỗi máy thực thi nhiều nhất một tác vụ reduce tại một thời điểm). Khoảng 300 giây sau khi phép tính bắt đầu, một số tác vụ reduce thuộc lô đầu tiên này hoàn tất và chúng tôi bắt đầu xáo trộn dữ liệu cho các tác vụ reduce còn lại. Toàn bộ việc xáo trộn hoàn tất khoảng 600 giây sau khi phép tính bắt đầu.
The bottom-left graph shows the rate at which sorted data is written to the final output files by the reduce tasks. There is a delay between the end of the first shuffling period and the start of the writing period because the machines are busy sorting the intermediate data. The writes continue at a rate of about 2-4 GB/s for a while. All of the writes finish about 850 seconds into the computation. Including startup overhead, the entire computation takes 891 seconds. This is similar to the current best reported result of 1057 seconds for the TeraSort benchmark [18].
Đồ thị phía dưới bên trái cho thấy tốc độ dữ liệu đã sắp xếp được các tác vụ reduce ghi vào các file đầu ra cuối cùng. Có một độ trễ giữa thời điểm kết thúc giai đoạn xáo trộn đầu tiên và thời điểm bắt đầu giai đoạn ghi vì các máy đang bận sắp xếp dữ liệu trung gian. Việc ghi tiếp tục với tốc độ khoảng 2-4 GB/s trong một thời gian. Toàn bộ việc ghi hoàn tất khoảng 850 giây sau khi phép tính bắt đầu. Bao gồm chi phí phụ trội khởi động, toàn bộ phép tính mất 891 giây. Kết quả này tương tự kết quả tốt nhất hiện được báo cáo là 1057 giây đối với phép đo chuẩn TeraSort [18].
A few things to note: the input rate is higher than the shuffle rate and the output rate because of our locality optimization – most data is read from a local disk and bypasses our relatively bandwidth constrained network. The shuffle rate is higher than the output rate because the output phase writes two copies of the sorted data (we make two replicas of the output for reliability and availability reasons). We write two replicas because that is the mechanism for reliability and availability provided by our underlying file system. Network bandwidth requirements for writing data would be reduced if the underlying file system used erasure coding [14] rather than replication.
Một vài điều cần lưu ý: tốc độ đầu vào cao hơn tốc độ shuffle và tốc độ đầu ra do tối ưu hóa tính cục bộ của chúng tôi – phần lớn dữ liệu được đọc từ đĩa cục bộ và bỏ qua mạng của chúng tôi vốn bị hạn chế tương đối về băng thông. Tốc độ shuffle cao hơn tốc độ đầu ra vì giai đoạn đầu ra ghi hai bản sao của dữ liệu đã sắp xếp (chúng tôi tạo hai bản sao của đầu ra vì lý do độ tin cậy và tính sẵn sàng). Chúng tôi ghi hai bản sao vì đó là cơ chế đảm bảo độ tin cậy và tính sẵn sàng do hệ thống file nền tảng cung cấp. Yêu cầu về băng thông mạng khi ghi dữ liệu sẽ giảm nếu hệ thống file nền tảng sử dụng mã hóa xóa [14] thay vì sao chép.
5.4 Effect of Backup Tasks
5.4 Ảnh hưởng của các tác vụ dự phòng
In Figure 3 (b), we show an execution of the sort program with backup tasks disabled. The execution flow is similar to that shown in Figure 3 (a), except that there is a very long tail where hardly any write activity occurs. After 960 seconds, all except 5 of the reduce tasks are completed. The last few stragglers don’t finish until 300 seconds later. The entire computation takes 1283 seconds, an increase of 44% in elapsed time.
Trong Hình 3 (b), chúng tôi trình bày một lần thực thi chương trình sort khi các tác vụ dự phòng bị vô hiệu hóa. Luồng thực thi tương tự như trong Hình 3 (a), ngoại trừ việc có một phần đuôi rất dài, trong đó hầu như không có hoạt động ghi nào xảy ra. Sau 960 giây, tất cả trừ 5 tác vụ reduce đã hoàn thành. Một vài tác vụ chậm cuối cùng chỉ hoàn thành sau 300 giây nữa. Toàn bộ tính toán mất 1283 giây, tăng 44% về thời gian thực.
5.5 Machine Failures
5.5 Sự cố máy
In Figure 3 (c), we show an execution of the sort program where we intentionally killed 200 out of 1746 worker processes several minutes into the computation. The underlying cluster scheduler immediately restarted new worker processes on these machines (since only the processes were killed, the machines were still functioning properly).
Trong Hình 3 (c), chúng tôi trình bày một lần thực thi chương trình sort trong đó chúng tôi cố ý kết thúc 200 trong số 1746 tiến trình worker vài phút sau khi bắt đầu tính toán. Bộ lập lịch cụm nền tảng ngay lập tức khởi động lại các tiến trình worker mới trên những máy này (vì chỉ các tiến trình bị kết thúc, các máy vẫn hoạt động bình thường).
The worker deaths show up as a negative input rate since some previously completed map work disappears (since the corresponding map workers were killed and needs to be redone). The re-execution of this map work happens relatively quickly. The entire computation finishes in 933 seconds including startup overhead (just an increase of 5% over the normal execution time).
Sự cố của các worker xuất hiện dưới dạng tốc độ đầu vào âm vì một phần công việc map đã hoàn thành trước đó biến mất (do các worker map tương ứng bị kết thúc và cần được thực hiện lại). Việc thực thi lại công việc map này diễn ra tương đối nhanh. Toàn bộ tính toán hoàn thành trong 933 giây, bao gồm chi phí phụ trội khởi động (chỉ tăng 5% so với thời gian thực thi bình thường).
6 Experience
6 Kinh nghiệm
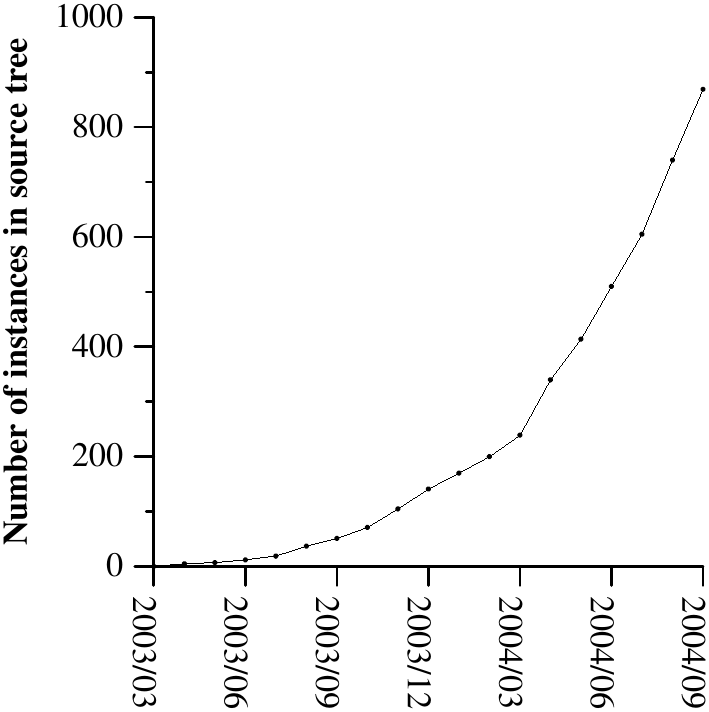
We wrote the first version of the MapReduce library in February of 2003, and made significant enhancements to it in August, of 2003, including the locality optimization, dynamic load balancing of task execution across worker machines, etc. Since that time, we have been pleasantly surprised at how broadly applicable the MapReduce library has been for the kinds of problems we work on. It has been used across a wide range of domains within Google, including:
Chúng tôi đã viết phiên bản đầu tiên của thư viện MapReduce vào tháng 2 năm 2003, và thực hiện những cải tiến đáng kể đối với nó vào tháng 8 năm 2003, bao gồm tối ưu hóa tính cục bộ, cân bằng tải động của việc thực thi tác vụ trên các máy worker, v.v. Kể từ thời điểm đó, chúng tôi đã rất ngạc nhiên một cách tích cực về mức độ áp dụng rộng rãi của thư viện MapReduce đối với các loại bài toán mà chúng tôi xử lý. Nó đã được sử dụng trong nhiều lĩnh vực khác nhau bên trong Google, bao gồm:
- large-scale machine learning problems,
- clustering problems for the Google News and Froogle products,
- extraction of data used to produce reports of popular queries (e.g. Google Zeitgeist),
- extraction of properties of web pages for new experiments and products (e.g. extraction of geographical locations from a large corpus of web pages for localized search), and
- large-scale graph computations.
- các bài toán học máy quy mô lớn,
- các bài toán phân cụm cho các sản phẩm Google News và Froogle,
- trích xuất dữ liệu được sử dụng để tạo báo cáo về các truy vấn phổ biến (ví dụ: Google Zeitgeist),
- trích xuất các thuộc tính của các trang web cho các thử nghiệm và sản phẩm mới (ví dụ: trích xuất vị trí địa lý từ một tập dữ liệu lớn các trang web cho tìm kiếm cục bộ), và
- các phép tính trên đồ thị quy mô lớn.
              Number of jobs                                      29,423
Average job completion time                         634 secs
Machine used                                       79,186 days
Input data read                                    3,288 TB
Intermediate data produced                           758 TB
Output data written                                  193 TB
Average worker machines per job                       157
Average worker deaths per job                         1.2
Average map tasks per job                           3,351
Average reduce tasks per job                           55
Unique map implementations                            395
Unique reduce implementations                         269
Unique map/reduce combinations                        426
              Number of jobs                                      29,423
Average job completion time                         634 secs
Machine used                                       79,186 days
Input data read                                    3,288 TB
Intermediate data produced                           758 TB
Output data written                                  193 TB
Average worker machines per job                       157
Average worker deaths per job                         1.2
Average map tasks per job                           3,351
Average reduce tasks per job                           55
Unique map implementations                            395
Unique reduce implementations                         269
Unique map/reduce combinations                        426
Table 1: MapReduce jobs run in August 2004
Bảng 1: Các công việc MapReduce được chạy vào tháng 8 năm 2004
Figure 4 shows the significant growth in the number of separate MapReduce programs checked into our primary source code management system over time, from 0 in early 2003 to almost 900 separate instances as of late September 2004. MapReduce has been so successful because it makes it possible to write a simple program and run it efficiently on a thousand machines in the course of half an hour, greatly speeding up the development and prototyping cycle. Furthermore, it allows programmers who have no experience with distributed and/or parallel systems to exploit large amounts of resources easily.
Hình 4 cho thấy sự tăng trưởng đáng kể về số lượng các chương trình MapReduce riêng biệt được đưa vào hệ thống quản lý mã nguồn chính của chúng tôi theo thời gian, từ 0 vào đầu năm 2003 đến gần 900 thể hiện riêng biệt vào cuối tháng 9 năm 2004. MapReduce đã thành công đến vậy vì nó cho phép viết một chương trình đơn giản và chạy nó một cách hiệu quả trên một nghìn máy trong khoảng thời gian nửa giờ, giúp tăng tốc đáng kể chu kỳ phát triển và tạo mẫu. Hơn nữa, nó cho phép các lập trình viên không có kinh nghiệm với các hệ thống phân tán và/hoặc song song dễ dàng khai thác lượng lớn tài nguyên.
At the end of each job, the MapReduce library logs statistics about the computational resources used by the job. In Table 1, we show some statistics for a subset of MapReduce jobs run at Google in August 2004.
Vào cuối mỗi công việc, thư viện MapReduce ghi nhật ký các thống kê về các tài nguyên tính toán được công việc sử dụng. Trong Bảng 1, chúng tôi trình bày một số thống kê cho một tập con các công việc MapReduce được chạy tại Google vào tháng 8 năm 2004.
6.1 Large-Scale Indexing
6.1 Lập chỉ mục quy mô lớn
One of our most significant uses of MapReduce to date has been a complete rewrite of the production indexing system that produces the data structures used for the Google web search service. The indexing system takes as input a large set of documents that have been retrieved by our crawling system, stored as a set of GFS files. The raw contents for these documents are more than 20 terabytes of data. The indexing process runs as a sequence of five to ten MapReduce operations. Using MapReduce (instead of the ad-hoc distributed passes in the prior version of the indexing system) has provided several benefits:
Một trong những cách sử dụng MapReduce quan trọng nhất của chúng tôi cho đến nay là viết lại hoàn toàn hệ thống lập chỉ mục sản xuất tạo ra các cấu trúc dữ liệu được sử dụng cho dịch vụ tìm kiếm web của Google. Hệ thống lập chỉ mục nhận đầu vào là một tập lớn các tài liệu đã được hệ thống thu thập dữ liệu của chúng tôi lấy về, được lưu trữ dưới dạng một tập các file GFS. Nội dung thô của các tài liệu này có kích thước hơn 20 terabyte dữ liệu. Quá trình lập chỉ mục chạy dưới dạng một chuỗi từ năm đến mười phép toán MapReduce. Việc sử dụng MapReduce (thay vì các lượt truyền phân tán đặc biệt trong phiên bản trước của hệ thống lập chỉ mục) đã mang lại một số lợi ích:
- The indexing code is simpler, smaller, and easier to understand, because the code that deals with fault tolerance, distribution and parallelization is hidden within the MapReduce library. For example, the size of one phase of the computation dropped from approximately 3800 lines of C++ code to approximately 700 lines when expressed using MapReduce.
- The performance of the MapReduce library is good enough that we can keep conceptually unrelated computations separate, instead of mixing them together to avoid extra passes over the data. This makes it easy to change the indexing process. For example, one change that took a few months to make in our old indexing system took only a few days to implement in the new system.
- The indexing process has become much easier to operate, because most of the problems caused by machine failures, slow machines, and networking hiccups are dealt with automatically by the MapReduce library without operator intervention. Furthermore, it is easy to improve the performance of the indexing process by adding new machines to the indexing cluster.
- Mã lập chỉ mục đơn giản hơn, nhỏ hơn và dễ hiểu hơn, bởi vì mã xử lý khả năng chịu lỗi, phân phối và song song hóa được ẩn bên trong thư viện MapReduce. Ví dụ, kích thước của một giai đoạn của phép tính đã giảm từ khoảng 3800 dòng mã C++ xuống còn khoảng 700 dòng khi được biểu diễn bằng MapReduce.
- Hiệu năng của thư viện MapReduce đủ tốt để chúng tôi có thể giữ các phép tính không liên quan về mặt khái niệm tách biệt, thay vì trộn chúng với nhau để tránh các lượt truyền bổ sung qua dữ liệu. Điều này giúp dễ dàng thay đổi quá trình lập chỉ mục. Ví dụ, một thay đổi mất vài tháng để thực hiện trong hệ thống lập chỉ mục cũ của chúng tôi chỉ mất vài ngày để triển khai trong hệ thống mới.
- Quá trình lập chỉ mục trở nên dễ vận hành hơn nhiều, bởi vì phần lớn các vấn đề do sự cố máy, máy chậm và các trục trặc mạng gây ra được thư viện MapReduce tự động xử lý mà không cần sự can thiệp của toán tử. Hơn nữa, có thể dễ dàng cải thiện hiệu năng của quá trình lập chỉ mục bằng cách thêm các máy mới vào cụm lập chỉ mục.
7 Related Work
7 Công trình liên quan
Many systems have provided restricted programming models and used the restrictions to parallelize the computation automatically. For example, an associative function can be computed over all prefixes of an element array in time on processors using parallel prefix computations [6, 9, 13]. MapReduce can be considered a simplification and distillation of some of these models based on our experience with large real-world computations. More significantly, we provide a fault-tolerant implementation that scales to thousands of processors. In contrast, most of the parallel processing systems have only been implemented on smaller scales and leave the details of handling machine failures to the programmer.
Nhiều hệ thống đã cung cấp các mô hình lập trình bị hạn chế và sử dụng các hạn chế này để tự động song song hóa việc tính toán. Ví dụ, một hàm kết hợp có thể được tính trên tất cả các tiền tố của một mảng gồm phần tử trong thời gian trên bộ xử lý bằng cách sử dụng các phép tính tiền tố song song [6, 9, 13]. MapReduce có thể được xem là sự đơn giản hóa và chắt lọc của một số mô hình này dựa trên kinh nghiệm của chúng tôi với các phép tính thực tế quy mô lớn. Quan trọng hơn, chúng tôi cung cấp một triển khai chịu lỗi có khả năng mở rộng đến hàng nghìn bộ xử lý. Ngược lại, hầu hết các hệ thống xử lý song song chỉ được triển khai ở quy mô nhỏ hơn và để lại các chi tiết xử lý sự cố máy cho người lập trình.
Bulk Synchronous Programming [17] and some MPI primitives [11] provide higher-level abstractions that make it easier for programmers to write parallel programs. A key difference between these systems and MapReduce is that MapReduce exploits a restricted programming model to parallelize the user program automatically and to provide transparent fault-tolerance.
Bulk Synchronous Programming [17] và một số nguyên thủy MPI [11] cung cấp các trừu tượng hóa cấp cao hơn giúp người lập trình dễ dàng viết các chương trình song song hơn. Một điểm khác biệt quan trọng giữa các hệ thống này và MapReduce là MapReduce khai thác một mô hình lập trình bị hạn chế để tự động song song hóa chương trình của người dùng và cung cấp khả năng chịu lỗi trong suốt.
Our locality optimization draws its inspiration from techniques such as active disks [12, 15], where computation is pushed into processing elements that are close to local disks, to reduce the amount of data sent through the I/O subsystems or the network. We run on commodity processors to which a small number of disks are directly connected instead of running directly on disk controller processors, but the general approach is similar.
Tối ưu hóa cục bộ của chúng tôi lấy cảm hứng từ các kỹ thuật như active disks [12, 15], trong đó việc tính toán được đẩy vào các phần tử xử lý gần với các đĩa cục bộ, nhằm giảm lượng dữ liệu được gửi qua các hệ thống con I/O hoặc mạng. Chúng tôi chạy trên các bộ xử lý phổ thông mà một số lượng nhỏ đĩa được kết nối trực tiếp với chúng thay vì chạy trực tiếp trên các bộ xử lý điều khiển đĩa, nhưng cách tiếp cận tổng quát là tương tự.
Our backup task mechanism is similar to the eager scheduling mechanism employed in the Charlotte System [3]. One of the shortcomings of simple eager scheduling is that if a given task causes repeated failures, the entire computation fails to complete. We fix some instances of this problem with our mechanism for skipping bad records.
Cơ chế tác vụ dự phòng của chúng tôi tương tự với cơ chế lập lịch háo hức được sử dụng trong Charlotte System [3]. Một trong những thiếu sót của lập lịch háo hức đơn giản là nếu một tác vụ nhất định gây ra các sự cố lặp lại, toàn bộ tính toán sẽ không hoàn thành. Chúng tôi khắc phục một số trường hợp của vấn đề này bằng cơ chế bỏ qua các bản ghi xấu.
The MapReduce implementation relies on an in-house cluster management system that is responsible for distributing and running user tasks on a large collection of shared machines. Though not the focus of this paper, the cluster management system is similar in spirit to other systems such as Condor [16].
Triển khai MapReduce dựa vào một hệ thống quản lý cụm nội bộ chịu trách nhiệm phân phối và chạy các tác vụ của người dùng trên một tập hợp lớn các máy dùng chung. Mặc dù không phải là trọng tâm của bài báo này, hệ thống quản lý cụm có tinh thần tương tự như các hệ thống khác như Condor [16].
The sorting facility that is a part of the MapReduce library is similar in operation to NOW-Sort [1]. Source machines (map workers) partition the data to be sorted and send it to one of reduce workers. Each reduce worker sorts its data locally (in memory if possible). Of course NOW-Sort does not have the user-definable Map and Reduce functions that make our library widely applicable.
Cơ sở sắp xếp là một phần của thư viện MapReduce có hoạt động tương tự như NOW-Sort [1]. Các máy nguồn (các worker map) phân vùng dữ liệu cần sắp xếp và gửi nó đến một trong worker reduce. Mỗi worker reduce sắp xếp dữ liệu của mình cục bộ (trong bộ nhớ nếu có thể). Tất nhiên NOW-Sort không có các hàm Map và Reduce do người dùng định nghĩa, những hàm làm cho thư viện của chúng tôi có phạm vi áp dụng rộng rãi.
River [2] provides a programming model where processes communicate with each other by sending data over distributed queues. Like MapReduce, the River system tries to provide good average case performance even in the presence of non-uniformities introduced by heterogeneous hardware or system perturbations. River achieves this by careful scheduling of disk and network transfers to achieve balanced completion times. MapReduce has a different approach. By restricting the programming model, the MapReduce framework is able to partition the problem into a large number of fine-grained tasks. These tasks are dynamically scheduled on available workers so that faster workers process more tasks. The restricted programming model also allows us to schedule redundant executions of tasks near the end of the job which greatly reduces completion time in the presence of non-uniformities (such as slow or stuck workers).
River [2] cung cấp một mô hình lập trình trong đó các tiến trình giao tiếp với nhau bằng cách gửi dữ liệu qua các hàng đợi phân tán. Giống như MapReduce, hệ thống River cố gắng cung cấp hiệu năng trường hợp trung bình tốt ngay cả khi có các sai khác không đồng nhất do phần cứng không đồng nhất hoặc các nhiễu loạn hệ thống gây ra. River đạt được điều này bằng cách lập lịch cẩn thận các truyền tải đĩa và mạng để đạt được thời gian hoàn thành cân bằng. MapReduce có một cách tiếp cận khác. Bằng cách hạn chế mô hình lập trình, khung MapReduce có thể phân vùng vấn đề thành một số lượng lớn các tác vụ có độ chi tiết nhỏ. Các tác vụ này được lập lịch động trên các worker khả dụng sao cho các worker nhanh hơn xử lý nhiều tác vụ hơn. Mô hình lập trình bị hạn chế cũng cho phép chúng tôi lập lịch các thực thi dư thừa của các tác vụ gần cuối công việc, điều này làm giảm đáng kể thời gian hoàn thành khi có các sai khác không đồng nhất (chẳng hạn như các worker chậm hoặc bị kẹt).
BAD-FS [5] has a very different programming model from MapReduce, and unlike MapReduce, is targeted to the execution of jobs across a wide-area network. However, there are two fundamental similarities. (1) Both systems use redundant execution to recover from data loss caused by failures. (2) Both use locality-aware scheduling to reduce the amount of data sent across congested network links.
BAD-FS [5] có một mô hình lập trình rất khác so với MapReduce, và không giống MapReduce, được hướng tới việc thực thi các công việc trên một mạng diện rộng. Tuy nhiên, có hai điểm tương đồng cơ bản. (1) Cả hai hệ thống đều sử dụng thực thi dư thừa để khôi phục từ mất dữ liệu do các sự cố gây ra. (2) Cả hai đều sử dụng lập lịch nhận biết tính cục bộ để giảm lượng dữ liệu được gửi qua các liên kết mạng bị tắc nghẽn.
TACC [7] is a system designed to simplify construction of highly-available networked services. Like MapReduce, it relies on re-execution as a mechanism for implementing fault-tolerance.
TACC [7] là một hệ thống được thiết kế để đơn giản hóa việc xây dựng các dịch vụ mạng có tính khả dụng cao. Giống như MapReduce, nó dựa vào việc thực thi lại như một cơ chế để triển khai khả năng chịu lỗi.
8 Conclusions
8 Kết luận
The MapReduce programming model has been successfully used at Google for many different purposes. We attribute this success to several reasons. First, the model is easy to use, even for programmers without experience with parallel and distributed systems, since it hides the details of parallelization, fault-tolerance, locality optimization, and load balancing. Second, a large variety of problems are easily expressible as MapReduce computations. For example, MapReduce is used for the generation of data for Google’s production web search service, for sorting, for data mining, for machine learning, and many other systems. Third, we have developed an implementation of MapReduce that scales to large clusters of machines comprising thousands of machines. The implementation makes efficient use of these machine resources and therefore is suitable for use on many of the large computational problems encountered at Google.
Mô hình lập trình MapReduce đã được sử dụng thành công tại Google cho nhiều mục đích khác nhau. Chúng tôi cho rằng thành công này đến từ một số lý do. Thứ nhất, mô hình này dễ sử dụng, ngay cả đối với các lập trình viên không có kinh nghiệm về các hệ thống song song và phân tán, vì nó che giấu các chi tiết của việc song song hóa, khả năng chịu lỗi, tối ưu hóa cục bộ và cân bằng tải. Thứ hai, một lượng lớn các bài toán có thể dễ dàng được biểu diễn dưới dạng các tính toán MapReduce. Ví dụ, MapReduce được sử dụng để tạo dữ liệu cho dịch vụ tìm kiếm web sản xuất của Google, để sắp xếp, khai phá dữ liệu, học máy và nhiều hệ thống khác. Thứ ba, chúng tôi đã phát triển một triển khai MapReduce có khả năng mở rộng tới các cụm máy lớn bao gồm hàng nghìn máy. Triển khai này sử dụng hiệu quả các tài nguyên máy này và do đó phù hợp để sử dụng cho nhiều bài toán tính toán lớn gặp phải tại Google.
We have learned several things from this work. First, restricting the programming model makes it easy to parallelize and distribute computations and to make such computations fault-tolerant. Second, network bandwidth is a scarce resource. A number of optimizations in our system are therefore targeted at reducing the amount of data sent across the network: the locality optimization allows us to read data from local disks, and writing a single copy of the intermediate data to local disk saves network bandwidth. Third, redundant execution can be used to reduce the impact of slow machines, and to handle machine failures and data loss.
Chúng tôi đã học được một số điều từ công trình này. Thứ nhất, việc hạn chế mô hình lập trình giúp dễ dàng song song hóa và phân phối các tính toán, đồng thời làm cho các tính toán đó có khả năng chịu lỗi. Thứ hai, băng thông mạng là một tài nguyên khan hiếm. Do đó, một số tối ưu hóa trong hệ thống của chúng tôi hướng tới việc giảm lượng dữ liệu được gửi qua mạng: tối ưu hóa cục bộ cho phép chúng tôi đọc dữ liệu từ các đĩa cục bộ, và việc ghi một bản sao duy nhất của dữ liệu trung gian vào đĩa cục bộ giúp tiết kiệm băng thông mạng. Thứ ba, thực thi dư thừa có thể được sử dụng để giảm tác động của các máy chậm, đồng thời xử lý các sự cố máy và mất dữ liệu.
Acknowledgments
Lời cảm ơn
Josh Levenberg has been instrumental in revising and extending the user-level MapReduce API with a number of new features based on his experience with using MapReduce and other people’s suggestions for enhancements. MapReduce reads its input from and writes its output to the Google File System [8]. We would like to thank Mohit Aron, Howard Gobioff, Markus Gutschke, David Kramer, Shun-Tak Leung, and Josh Redstone for their work in developing GFS. We would also like to thank Percy Liang and Olcan Sercinoglu for their work in developing the cluster management system used by MapReduce. Mike Burrows, Wilson Hsieh, Josh Levenberg, Sharon Perl, Rob Pike, and Debby Wallach provided helpful comments on earlier drafts of this paper. The anonymous OSDI reviewers, and our shepherd, Eric Brewer, provided many useful suggestions of areas where the paper could be improved. Finally, we thank all the users of MapReduce within Google’s engineering organization for providing helpful feedback, suggestions, and bug reports.
Josh Levenberg đã đóng vai trò quan trọng trong việc sửa đổi và mở rộng API MapReduce ở mức người dùng với một số tính năng mới dựa trên kinh nghiệm của ông trong việc sử dụng MapReduce và các đề xuất cải tiến từ những người khác. MapReduce đọc đầu vào của nó từ và ghi đầu ra của nó vào Google File System [8]. Chúng tôi xin cảm ơn Mohit Aron, Howard Gobioff, Markus Gutschke, David Kramer, Shun-Tak Leung và Josh Redstone vì công việc của họ trong việc phát triển GFS. Chúng tôi cũng xin cảm ơn Percy Liang và Olcan Sercinoglu vì công việc của họ trong việc phát triển hệ thống quản lý cụm được MapReduce sử dụng. Mike Burrows, Wilson Hsieh, Josh Levenberg, Sharon Perl, Rob Pike và Debby Wallach đã đưa ra những nhận xét hữu ích về các bản thảo trước đó của bài báo này. Các phản biện ẩn danh của OSDI và người hướng dẫn của chúng tôi, Eric Brewer, đã đưa ra nhiều đề xuất hữu ích về những lĩnh vực mà bài báo có thể được cải thiện. Cuối cùng, chúng tôi cảm ơn tất cả người dùng MapReduce trong tổ chức kỹ thuật của Google vì đã cung cấp những phản hồi, đề xuất và báo cáo lỗi hữu ích.
A Word Frequency
A Tần suất từ
This section contains a program that counts the number of occurrences of each unique word in a set of input files specified on the command line.
Phần này chứa một chương trình đếm số lần xuất hiện của mỗi từ duy nhất trong một tập hợp các file đầu vào được chỉ định trên dòng lệnh.
C
C
              #include "mapreduce/mapreduce.h"

// User’s map function
class WordCounter : public Mapper {
 public:
  virtual void Map(const MapInput& input) {
    const string& text = input.value();
    const int n = text.size();
    for (int i = 0; i < n; ) {
      // Skip past leading whitespace
      while ((i < n) && isspace(text[i]))
        i++;

      // Find word end
      int start = i;
      while ((i < n) && !isspace(text[i]))
        i++;
              #include "mapreduce/mapreduce.h"

// User’s map function
class WordCounter : public Mapper {
 public:
  virtual void Map(const MapInput& input) {
    const string& text = input.value();
    const int n = text.size();
    for (int i = 0; i < n; ) {
      // Skip past leading whitespace
      while ((i < n) && isspace(text[i]))
        i++;

      // Find word end
      int start = i;
      while ((i < n) && !isspace(text[i]))
        i++;
C
C
                    if (start < i)
        Emit(text.substr(start,i-start),"1");
    }
  }
};
REGISTER_MAPPER(WordCounter);

// User’s reduce function
class Adder : public Reducer {
  virtual void Reduce(ReduceInput* input) {
    // Iterate over all entries with the
    // same key and add the values
    int64 value = 0;
    while (!input->done()) {
      value += StringToInt(input->value());
      input->NextValue();
    }

    // Emit sum for input->key()
    Emit(IntToString(value));
  }
};
REGISTER_REDUCER(Adder);

int main(int argc, char** argv) {
  ParseCommandLineFlags(argc, argv);

  MapReduceSpecification spec;

  // Store list of input files into "spec"
  for (int i = 1; i < argc; i++) {
    MapReduceInput* input = spec.add_input();
    input->set_format("text");
    input->set_filepath(argv[i]);
    input->set_mapper_class("WordCounter");
  }

  // Specify the output files:
  //    /gfs/test/freq-00000-of-00100
  //    /gfs/test/freq-00001-of-00100
  //    ...
  MapReduceOutput* out = spec.output();
  out->set_filebase("/gfs/test/freq");
  out->set_num_tasks(100);
  out->set_format("text");
  out->set_reducer_class("Adder");

  // Optional: do partial sums within map
  // tasks to save network bandwidth
  out->set_combiner_class("Adder");

  // Tuning parameters: use at most 2000
  // machines and 100 MB of memory per task
  spec.set_machines(2000);
  spec.set_map_megabytes(100);
  spec.set_reduce_megabytes(100);

  // Now run it
  MapReduceResult result;
  if (!MapReduce(spec, &result)) abort();

  // Done: ’result’ structure contains info
  // about counters, time taken, number of
  // machines used, etc.

  return 0;
}
                    if (start < i)
        Emit(text.substr(start,i-start),"1");
    }
  }
};
REGISTER_MAPPER(WordCounter);

// User’s reduce function
class Adder : public Reducer {
  virtual void Reduce(ReduceInput* input) {
    // Iterate over all entries with the
    // same key and add the values
    int64 value = 0;
    while (!input->done()) {
      value += StringToInt(input->value());
      input->NextValue();
    }

    // Emit sum for input->key()
    Emit(IntToString(value));
  }
};
REGISTER_REDUCER(Adder);

int main(int argc, char** argv) {
  ParseCommandLineFlags(argc, argv);

  MapReduceSpecification spec;

  // Store list of input files into "spec"
  for (int i = 1; i < argc; i++) {
    MapReduceInput* input = spec.add_input();
    input->set_format("text");
    input->set_filepath(argv[i]);
    input->set_mapper_class("WordCounter");
  }

  // Specify the output files:
  //    /gfs/test/freq-00000-of-00100
  //    /gfs/test/freq-00001-of-00100
  //    ...
  MapReduceOutput* out = spec.output();
  out->set_filebase("/gfs/test/freq");
  out->set_num_tasks(100);
  out->set_format("text");
  out->set_reducer_class("Adder");

  // Optional: do partial sums within map
  // tasks to save network bandwidth
  out->set_combiner_class("Adder");

  // Tuning parameters: use at most 2000
  // machines and 100 MB of memory per task
  spec.set_machines(2000);
  spec.set_map_megabytes(100);
  spec.set_reduce_megabytes(100);

  // Now run it
  MapReduceResult result;
  if (!MapReduce(spec, &result)) abort();

  // Done: ’result’ structure contains info
  // about counters, time taken, number of
  // machines used, etc.

  return 0;
}
References
- Andrea C. Arpaci-Dusseau, Remzi H. Arpaci-Dusseau, David E. Culler, Joseph M. Hellerstein, and David A. Patterson. High-performance sorting on networks of workstations. In Proceedings of the 1997 ACM SIGMOD International Conference on Management of Data, Tucson, Arizona, May 1997.
- Remzi H. Arpaci-Dusseau, Eric Anderson, Noah Treuhaft, David E. Culler, Joseph M. Hellerstein, David Patterson, and Kathy Yelick. Cluster I/O with River: Making the fast case common. In Proceedings of the Sixth Workshop on Input/Output in Parallel and Distributed Systems (IOPADS ’99), pages 10–22, Atlanta, Georgia, May 1999.
- Arash Baratloo, Mehmet Karaul, Zvi Kedem, and Peter Wyckoff. Charlotte: Metacomputing on the web. In Proceedings of the 9th International Conference on Parallel and Distributed Computing Systems, 1996.
- Luiz A. Barroso, Jeffrey Dean, and Urs Hölzle. Web search for a planet: The Google cluster architecture. IEEE Micro, 23(2):22–28, April 2003.
- John Bent, Douglas Thain, Andrea C. Arpaci-Dusseau, Remzi H. Arpaci-Dusseau, and Miron Livny. Explicit control in a batch-aware distributed file system. In Proceedings of the 1st USENIX Symposium on Networked Systems Design and Implementation NSDI, March 2004.
- Guy E. Blelloch. Scans as primitive parallel operations. IEEE Transactions on Computers, C-38(11), November 1989.
- Armando Fox, Steven D. Gribble, Yatin Chawathe, Eric A. Brewer, and Paul Gauthier. Cluster-based scalable network services. In Proceedings of the 16th ACM Symposium on Operating System Principles, pages 78–91, Saint-Malo, France, 1997.
- Sanjay Ghemawat, Howard Gobioff, and Shun-Tak Leung. The Google file system. In 19th Symposium on Operating Systems Principles, pages 29–43, Lake George, New York, 2003. Read it here
- S. Gorlatch. Systematic efficient parallelization of scan and other list homomorphisms. In L. Bouge, P. Fragniaud, A. Mignotte, and Y. Robert, editors, Euro-Par’96. Parallel Processing, Lecture Notes in Computer Science 1124, pages 401–408. Springer-Verlag, 1996.
- Jim Gray. Sort benchmark home page. http://research.microsoft.com/barc/SortBenchmark/.
- William Gropp, Ewing Lusk, and Anthony Skjellum. Using MPI: Portable Parallel Programming with the Message-Passing Interface. MIT Press, Cambridge, MA, 1999.
- L. Huston, R. Sukthankar, R. Wickremesinghe, M. Satyanarayanan, G. R. Ganger, E. Riedel, and A. Ailamaki. Diamond: A storage architecture for early discard in interactive search. In Proceedings of the 2004 USENIX File and Storage Technologies FAST Conference, April 2004.
- Richard E. Ladner and Michael J. Fischer. Parallel prefix computation. Journal of the ACM, 27(4):831–838, 1980.
- Michael O. Rabin. Efficient dispersal of information for security, load balancing and fault tolerance. Journal of the ACM, 36(2):335–348, 1989.
- Erik Riedel, Christos Faloutsos, Garth A. Gibson, and David Nagle. Active disks for large-scale data processing. IEEE Computer, pages 68–74, June 2001.
- Douglas Thain, Todd Tannenbaum, and Miron Livny. Distributed computing in practice: The Condor experience. Concurrency and Computation: Practice and Experience, 2004.
- L. G. Valiant. A bridging model for parallel computation. Communications of the ACM, 33(8):103–111, 1997.
- Jim Wyllie. Spsort: How to sort a terabyte quickly. http://alme1.almaden.ibm.com/cs/spsort.pdf.
Read off the page by a vision model reading the page images using gpt-5.
Read off the page by a vision model reading the page images using gpt-5. Translated into Tiếng Việt by gpt-5, against glossary version 6. Translated from the English.