In-Datacenter Performance Analysis of a Tensor Processing Unit
Phân tích hiệu năng trong trung tâm dữ liệu của một Tensor Processing Unit™
Norman P. Jouppi, Cliff Young, Nishant Patil, David Patterson, Gaurav Agrawal, Raminder Bajwa, Sarah Bates, Suresh Bhatia, Nan Boden, Al Borchers, Rick Boyle, Pierre-luc Cantin, Clifford Chao, Chris Clark, Jeremy Coriell, Mike Daley, Matt Dau, Jeffrey Dean, Ben Gelb, Tara Vazir Ghaemmaghami, Rajendra Gottipati, William Gulland, Robert Hagmann, C. Richard Ho, Doug Hogberg, John Hu, Robert Hundt, Dan Hurt, Julian Ibarz, Aaron Jaffey, Alek Jaworski, Alexander Kaplan, Harshit Khaitan, Daniel Killebrew, Andy Koch, Naveen Kumar, Steve Lacy, James Laudon, James Law, Diemthu Le, Chris Leary, Zhuyuan Liu, Kyle Lucke, Alan Lundin, Gordon MacKean, Adriana Maggiore, Maire Mahony, Kieran Miller, Rahul Nagarajan, Ravi Narayanaswami, Ray Ni, Kathy Nix, Thomas Norrie, Mark Omernick, Narayana Penukonda, Andy Phelps, Jonathan Ross, Matt Ross, Amir Salek, Emad Samadiani, Chris Severn, Gregory Sizikov, Matthew Snelham, Jed Souter, Dan Steinberg, Andy Swing, Mercedes Tan, Gregory Thorson, Bo Tian, Horia Toma, Erick Tuttle, Vijay Vasudevan, Richard Walter, Walter Wang, Eric Wilcox, and Doe Hyun Yoon Google, Inc., Mountain View, CA USA Email: {jouppi, cliffy, nishantpatil, davidpatterson} @google.com
Sẽ được trình bày tại Hội nghị chuyên đề quốc tế lần thứ 44 về Kiến trúc Máy tính (ISCA), Toronto, Canada, ngày 26 tháng 6 năm 2017.
Tóm tắt Nhiều kiến trúc sư cho rằng những cải thiện lớn về chi phí-năng lượng-hiệu năng hiện nay phải đến từ phần cứng chuyên biệt theo miền. Bài báo này đánh giá một ASIC tùy biến, được gọi là Tensor Processing Unit (TPU), được triển khai trong các trung tâm dữ liệu từ năm 2015 để tăng tốc giai đoạn suy luận của các mạng nơ-ron (NN). Thành phần cốt lõi của TPU là một đơn vị nhân ma trận MAC 65,536 8-bit, cung cấp thông lượng cực đại 92 TeraOps/giây (TOPS) và một bộ nhớ lớn (28 MiB) trên chip do phần mềm quản lý. Mô hình thực thi xác định của TPU phù hợp với yêu cầu thời gian đáp ứng ở phân vị thứ 99 của các ứng dụng NN của chúng tôi hơn so với các tối ưu hóa biến thiên theo thời gian của CPU và GPU (cache, thực thi ngoài thứ tự, đa luồng, đa tiến trình, nạp trước, ...) vốn giúp tăng thông lượng trung bình nhiều hơn là bảo đảm độ trễ. Việc thiếu các tính năng như vậy giúp giải thích tại sao, mặc dù có vô số MAC và một bộ nhớ lớn, TPU tương đối nhỏ và tiêu thụ ít điện năng. Chúng tôi so sánh TPU với CPU Intel Haswell cấp server và GPU Nvidia K80, là những bộ xử lý cùng thời được triển khai trong cùng các trung tâm dữ liệu. Tải công việc của chúng tôi, được viết bằng khung TensorFlow cấp cao, sử dụng các ứng dụng NN trong môi trường sản xuất (MLP, CNN và LSTM), đại diện cho 95% nhu cầu suy luận NN của các trung tâm dữ liệu của chúng tôi. Mặc dù mức sử dụng thấp đối với một số ứng dụng, trung bình TPU nhanh hơn khoảng 15X - 30X so với GPU hoặc CPU cùng thời, với TOPS/Watt cao hơn khoảng 30X - 80X. Hơn nữa, việc sử dụng bộ nhớ GDDR5 của GPU trong TPU sẽ tăng gấp ba TOPS đạt được và nâng TOPS/Watt lên gần 70X so với GPU và 200X so với CPU. Từ khóa–DNN, MLP, CNN, RNN, LSTM, mạng nơ-ron, kiến trúc chuyên biệt theo miền, bộ tăng tốc
To appear at the 44th International Symposium on Computer Architecture (ISCA), Toronto, Canada, June 26, 2017.
Abstract
Many architects believe that major improvements in cost-energy-performance must now come from domain-specific hardware. This paper evaluates a custom ASIC—called a Tensor Processing Unit (TPU)— deployed in datacenters since 2015 that accelerates the inference phase of neural networks (NN). The heart of the TPU is a 65,536 8-bit MAC matrix multiply unit that offers a peak throughput of 92 TeraOps/second (TOPS) and a large (28 MiB) software-managed on-chip memory. The TPU’s deterministic execution model is a better match to the 99th-percentile response-time requirement of our NN applications than are the time-varying optimizations of CPUs and GPUs (caches, out-of-order execution, multithreading, multiprocessing, prefetching, ...) that help average throughput more than guaranteed latency. The lack of such features helps explain why, despite having myriad MACs and a big memory, the TPU is relatively small and low power. We compare the TPU to a server-class Intel Haswell CPU and an Nvidia K80 GPU, which are contemporaries deployed in the same datacenters. Our workload, written in the high-level TensorFlow framework, uses production NN applications (MLPs, CNNs, and LSTMs) that represent 95% of our datacenters’ NN inference demand. Despite low utilization for some applications, the TPU is on average about 15X - 30X faster than its contemporary GPU or CPU, with TOPS/Watt about 30X - 80X higher. Moreover, using the GPU’s GDDR5 memory in the TPU would triple achieved TOPS and raise TOPS/Watt to nearly 70X the GPU and 200X the CPU. Index terms–DNN, MLP, CNN, RNN, LSTM, neural network, domain-specific architecture, accelerator
1 Giới thiệu về mạng nơ-ron
1 Introduction to Neural Networks
Sự kết hợp giữa các tập dữ liệu lớn trên đám mây và số lượng lớn máy tính vận hành đám mây đã tạo nên sự hồi sinh của học máy. Đặc biệt, các mạng nơ-ron sâu (deep neural networks, DNN) đã mang lại những đột phá như giảm tỷ lệ lỗi từ trong nhận dạng tiếng nói xuống 30% so với các phương pháp truyền thống, mức cải thiện lớn nhất trong 20 năm [Dea16]; giảm tỷ lệ lỗi trong một cuộc thi nhận dạng ảnh từ 26% xuống 3.5% kể từ năm 2011 [Kri12] [Sze15] [He16]; và đánh bại một nhà vô địch cờ vây là con người [Sil16]. Khác với một số đối tượng ứng dụng của phần cứng, DNN có thể áp dụng cho nhiều bài toán, nên chúng tôi có thể tái sử dụng một ASIC chuyên dụng cho DNN để xây dựng các giải pháp về tiếng nói, thị giác, ngôn ngữ, dịch thuật, xếp hạng tìm kiếm và nhiều lĩnh vực khác.
The synergy between the large data sets in the cloud and the numerous computers that power it has enabled a renaissance in machine learning. In particular, deep neural networks (DNNs) have led to breakthroughs such as reducing word error rates in speech recognition by 30% over traditional approaches, which was the biggest gain in 20 years [Dea16]; cutting the error rate in an image recognition competition since 2011 from 26% to 3.5% [Kri12] [Sze15] [He16]; and beating a human champion at Go [Sil16]. Unlike some hardware targets, DNNs are applicable to a wide range of problems, so we can reuse a DNN-specific ASIC for solutions in speech, vision, language, translation, search ranking, and many more.
Mạng nơ-ron (NN) hướng tới chức năng tương tự bộ não và dựa trên một nơ-ron nhân tạo đơn giản: một hàm phi tuyến (chẳng hạn như ) của tổng có trọng số của các đầu vào. Các nơ-ron nhân tạo này được tập hợp thành các lớp, với đầu ra của một lớp trở thành đầu vào của lớp tiếp theo trong chuỗi. Phần “sâu” trong DNN xuất phát từ việc sử dụng nhiều hơn một vài lớp, vì các tập dữ liệu lớn trên đám mây cho phép xây dựng các mô hình chính xác hơn bằng cách dùng thêm các lớp và tăng kích thước lớp để nắm bắt các mẫu hoặc khái niệm ở cấp độ cao hơn, còn GPU cung cấp đủ năng lực tính toán để phát triển chúng.
Neural networks (NN) target brain-like functionality and are based on a simple artificial neuron: a nonlinear function (such as ) of a weighted sum of the inputs. These artificial neurons are collected into layers, with the outputs of one layer becoming the inputs of the next one in the sequence. The “deep” part of DNN comes from going beyond a few layers, as the large data sets in the cloud allowed more accurate models to be built by using extra and larger layers to capture higher levels of patterns or concepts, and GPUs provided enough computing to develop them.
Hai giai đoạn của NN được gọi là huấn luyện (hay học) và suy luận (hay dự đoán), tương ứng với phát triển và vận hành thực tế. Nhà phát triển chọn số lớp và kiểu NN, còn quá trình huấn luyện xác định các trọng số. Hiện nay, hầu như toàn bộ quá trình huấn luyện đều sử dụng số dấu phẩy động, đây là một lý do khiến GPU trở nên phổ biến. Một bước gọi là lượng tử hóa (quantization) chuyển số dấu phẩy động thành số nguyên có độ rộng nhỏ—thường chỉ 8 bit—vốn thường đủ tốt cho suy luận. Phép nhân số nguyên tám bit có thể tiêu thụ năng lượng ít hơn 6X và chiếm diện tích nhỏ hơn 6X so với phép nhân số dấu phẩy động 16 bit theo IEEE 754, còn lợi thế của phép cộng số nguyên là 13X về năng lượng và 38X về diện tích [Dal16].
The two phases of NN are called training (or learning) and inference (or prediction), and they refer to development versus production. The developer chooses the number of layers and the type of NN, and training determines the weights. Virtually all training today is in floating point, which is one reason GPUs have been so popular. A step called quantization transforms floating-point numbers into narrow integers—often just 8 bits—which are usually good enough for inference. Eight-bit integer multiplies can be 6X less energy and 6X less area than IEEE 754 16-bit floating-point multiplies, and the advantage for integer addition is 13X in energy and 38X in area [Dal16].
Hiện nay có ba loại NN phổ biến: 1. Perceptron đa lớp (MLP): Mỗi lớp mới là một tập hợp các hàm phi tuyến của tổng có trọng số của tất cả đầu ra (kết nối đầy đủ) từ một lớp trước đó, trong đó các trọng số được tái sử dụng. 2. Mạng nơ-ron tích chập (CNN): Mỗi lớp kế tiếp là một tập hợp các hàm phi tuyến của các tổng có trọng số của những tập con đầu ra gần nhau trong không gian từ lớp trước đó, trong đó các trọng số cũng được tái sử dụng. 3. Mạng nơ-ron hồi quy (RNN): Mỗi lớp tiếp theo là một tập hợp các hàm phi tuyến của các tổng có trọng số của đầu ra và trạng thái trước đó. RNN phổ biến nhất là bộ nhớ dài ngắn hạn (Long Short-Term Memory, LSTM). Điểm tinh tế của LSTM nằm ở việc quyết định thông tin nào cần quên và thông tin nào cần truyền sang lớp tiếp theo dưới dạng trạng thái. Các trọng số được tái sử dụng qua các bước thời gian.
Three kinds of NNs are popular today: 1. Multi-Layer Perceptrons (MLP): Each new layer is a set of nonlinear functions of weighted sum of all outputs (fully connected) from a prior one, which reuses the weights. 2. Convolutional Neural Networks (CNN): Each ensuing layer is a set of of nonlinear functions of weighted sums of spatially nearby subsets of outputs from the prior layer, which also reuses the weights. 3. Recurrent Neural Networks (RNN): Each subsequent layer is a collection of nonlinear functions of weighted sums of outputs and the previous state. The most popular RNN is Long Short-Term Memory (LSTM). The art of the LSTM is in deciding what to forget and what to pass on as state to the next layer. The weights are reused across time steps.
Bảng 1 trình bày hai ví dụ cho mỗi kiểu trong ba kiểu NN—đại diện cho 95% tải công việc suy luận NN trong các trung tâm dữ liệu của chúng tôi—mà chúng tôi dùng làm các phép đo chuẩn. Thường được viết bằng TensorFlow [Aba16], chúng ngắn đến ngạc nhiên: chỉ từ 100 đến 1500 dòng mã. Các phép đo chuẩn của chúng tôi là những phần nhỏ của các ứng dụng lớn hơn chạy trên server chủ, có thể gồm hàng nghìn đến hàng triệu dòng mã C++. Các ứng dụng thường phục vụ trực tiếp người dùng, dẫn đến những giới hạn nghiêm ngặt về thời gian phản hồi.
Table 1 shows two examples of each of the three types of NNs—which represent 95% of NN inference workload in our datacenters—that we use as benchmarks. Typically written in TensorFlow [Aba16], they are surprisingly short: just 100 to 1500 lines of code. Our benchmarks are small pieces of larger applications that run on the host server, which can be thousands to millions of lines of C++ code. The applications are typically user-facing, which leads to rigid response-time limits.
Mỗi mô hình cần từ 5M đến 100M trọng số (cột thứ 9 của Bảng 1), và việc truy cập chúng có thể tốn nhiều thời gian và năng lượng. Để phân bổ chi phí truy cập, cùng một bộ trọng số được tái sử dụng cho cả một lô ví dụ độc lập trong quá trình suy luận hoặc huấn luyện, qua đó cải thiện hiệu năng.
Each model needs between 5M and 100M weights (9th column of Table 1), which can take a lot of time and energy to access. To amortize the access costs, the same weights are reused across a batch of independent examples during inference or training, which improves performance.
Bài báo này mô tả và đo lường Bộ xử lý Tensor (TPU), đồng thời so sánh hiệu năng và công suất tiêu thụ của nó trong suy luận với các CPU và GPU cùng thời. Dưới đây là các điểm nổi bật: • Các ứng dụng suy luận thường chú trọng thời gian phản hồi hơn thông lượng vì chúng thường phục vụ trực tiếp người dùng. • Do các giới hạn về độ trễ, GPU K80 chưa được khai thác hết khi thực hiện suy luận và chỉ nhanh hơn CPU Haswell một chút. • Mặc dù có chip nhỏ hơn nhiều và công suất tiêu thụ thấp hơn, TPU có số lượng MAC gấp 25 lần và dung lượng bộ nhớ trên chip gấp 3.5 lần GPU K80. • TPU thực hiện suy luận nhanh hơn GPU K80 và CPU Haswell khoảng 15X - 30X. • Bốn trong sáu ứng dụng NN bị giới hạn bởi băng thông bộ nhớ trên TPU; nếu TPU được sửa đổi để có cùng hệ thống bộ nhớ như GPU K80, nó sẽ nhanh hơn GPU và CPU khoảng 30X - 50X. • Hiệu năng/Watt của TPU gấp 30X - 80X các sản phẩm cùng thời; TPU được sửa đổi với bộ nhớ K80 sẽ tốt hơn 70X - 200X. • Trong khi phần lớn các nhà thiết kế kiến trúc tập trung tăng tốc CNN, chúng chỉ chiếm 5% tải công việc trong trung tâm dữ liệu của chúng tôi.
This paper describes and measures the Tensor Processing Unit (TPU) and compares its performance and power for inference to its contemporary CPUs and GPUs. Here is a preview of the highlights: • Inference apps usually emphasize response-time over throughput since they are often user-facing. • Due to latency limits, the K80 GPU is underutilized for inference, and is just a little faster than a Haswell CPU. • Despite having a much smaller and lower power chip, the TPU has 25 times as many MACs and 3.5 times as much on-chip memory as the K80 GPU. • The TPU is about 15X - 30X faster at inference than the K80 GPU and the Haswell CPU. • Four of the six NN apps are memory-bandwidth limited on the TPU; if the TPU were revised to have the same memory system as the K80 GPU, it would be about 30X - 50X faster than the GPU and CPU. • The performance/Watt of the TPU is 30X - 80X that of contemporary products; the revised TPU with K80 memory would be 70X - 200X better. • While most architects have been accelerating CNNs, they represent just 5% of our datacenter workload.
              Name  LOC  Layers  Nonlinear function  Weights  TPU Ops / Weight Byte  TPU Batch Size  % of Deployed TPUs in July 2016
FC  Conv  Vector  Pool  Total
MLP0  100  5        5  ReLU  20M  200  200  61%
MLP1  1000  4        4  ReLU  5M  168  168
LSTMO  1000  24    34    58  sigmoid, tanh  52M  64  64  29%
LSTM1  1500  37    19    56  sigmoid, tanh  34M  96  96
CNN0  1000    16      16  ReLU  8M  2888  8  5%
CNN1  1000  4  72    13  89  ReLU  100M  1750  32
              Name  LOC  Layers  Nonlinear function  Weights  TPU Ops / Weight Byte  TPU Batch Size  % of Deployed TPUs in July 2016
FC  Conv  Vector  Pool  Total
MLP0  100  5        5  ReLU  20M  200  200  61%
MLP1  1000  4        4  ReLU  5M  168  168
LSTMO  1000  24    34    58  sigmoid, tanh  52M  64  64  29%
LSTM1  1500  37    19    56  sigmoid, tanh  34M  96  96
CNN0  1000    16      16  ReLU  8M  2888  8  5%
CNN1  1000  4  72    13  89  ReLU  100M  1750  32
Bảng 1. Sáu ứng dụng NN (hai ứng dụng cho mỗi kiểu NN) đại diện cho 95% tải công việc của TPU. Các cột là tên NN; số dòng mã; các kiểu và số lượng lớp trong NN (FC là kết nối đầy đủ, Conv là tích chập, Vector là vectơ như tên gọi, Pool là phép gộp, thực hiện giảm kích thước phi tuyến trên TPU; và mức độ phổ biến của ứng dụng TPU vào tháng 7 năm 2016. Một DNN là RankBrain [Cla15]; một LSTM là một phần của GNM Translate [Wu16]; một CNN là Inception; và CNN còn lại là DeepMind AlphaGo [Sil16][Jou15].
Table 1. Six NN applications (two per NN type) that represent 95% of the TPU’s workload. The columns are the NN name; the number of lines of code; the types and number of layers in the NN (FC is fully connected, Conv is convolution, Vector is self-explanatory, Pool is pooling, which does nonlinear downsizing on the TPU; and TPU application popularity in July 2016. One DNN is RankBrain [Cla15]; one LSTM is a subset of GNM Translate [Wu16]; one CNN is Inception; and the other CNN is DeepMind AlphaGo [Sil16][Jou15].
2 Nguồn gốc, Kiến trúc và Triển khai TPU
2 TPU Origin, Architecture, and Implementation
Bắt đầu từ năm 2006, chúng tôi đã thảo luận về việc triển khai GPU, FPGA hoặc ASIC tùy biến trong các datacenter của mình. Chúng tôi kết luận rằng một số ít ứng dụng có thể chạy trên phần cứng chuyên dụng có thể được thực hiện gần như miễn phí bằng công suất dư thừa của các datacenter lớn, và rất khó cải thiện một thứ miễn phí. Cuộc thảo luận thay đổi vào năm 2013 khi một dự báo cho rằng nếu mọi người sử dụng tìm kiếm bằng giọng nói 3 phút mỗi ngày với các DNN nhận dạng tiếng nói, chúng tôi sẽ phải tăng gấp đôi số datacenter để đáp ứng nhu cầu tính toán, điều này sẽ rất tốn kém nếu đáp ứng bằng các CPU thông thường. Do đó, chúng tôi bắt đầu một dự án ưu tiên cao nhằm nhanh chóng sản xuất một ASIC tùy biến cho suy luận (và mua GPU có sẵn trên thị trường cho huấn luyện). Mục tiêu là cải thiện hiệu năng-chi phí lên 10X so với GPU. Theo yêu cầu này, TPU được thiết kế, kiểm chứng [Ste15], chế tạo và triển khai trong các datacenter chỉ trong 15 tháng. (Giới hạn về dung lượng khiến lượng thông tin và mức độ chi tiết về TPU trong bài báo này bị hạn chế; xem [Ros15a], [Ros15b], [Ros15c], [Ros15d], [Tho15] và [You15] để biết thêm.)
Starting as early as 2006, we discussed deploying GPUs, FPGAs, or custom ASICs in our datacenters. We concluded that the few applications that could run on special hardware could be done virtually for free using the excess capacity of our large datacenters, and it’s hard to improve on free. The conversation changed in 2013 when a projection where people use voice search for 3 minutes a day using speech recognition DNNs would require our datacenters to double to meet computation demands, which would be very expensive to satisfy with conventional CPUs. Thus, we started a high-priority project to quickly produce a custom ASIC for inference (and bought off-the-shelf GPUs for training). The goal was to improve cost-performance by 10X over GPUs. Given this mandate, the TPU was designed, verified [Ste15], built, and deployed in datacenters in just 15 months. (Space limits the amount and the level of detail on the TPU in this paper; see [Ros15a], [Ros15b], [Ros15c], [Ros15d], [Tho15], and [You15] for more.)
Thay vì tích hợp chặt chẽ với CPU, nhằm giảm khả năng làm chậm quá trình triển khai, TPU được thiết kế như một bộ đồng xử lý trên bus I/O PCIe, cho phép cắm nó vào các server hiện có giống như GPU. Ngoài ra, để đơn giản hóa thiết kế phần cứng và gỡ lỗi, server máy chủ gửi các lệnh TPU để TPU thực thi thay vì tự lấy chúng.
Rather than be tightly integrated with a CPU, to reduce the chances of delaying deployment, the TPU was designed to be a coprocessor on the PCIe I/O bus, allowing it to plug into existing servers just as a GPU does. Moreover, to simplify hardware design and debugging, the host server sends TPU instructions for it to execute rather than fetching them itself.
Do đó, về bản chất, TPU gần với một bộ đồng xử lý FPU (floating-point unit) hơn là GPU.
Hence, the TPU is closer in spirit to an FPU (floating-point unit) coprocessor than it is to a GPU.
Hình.
Figure.
Hình.
Figure.
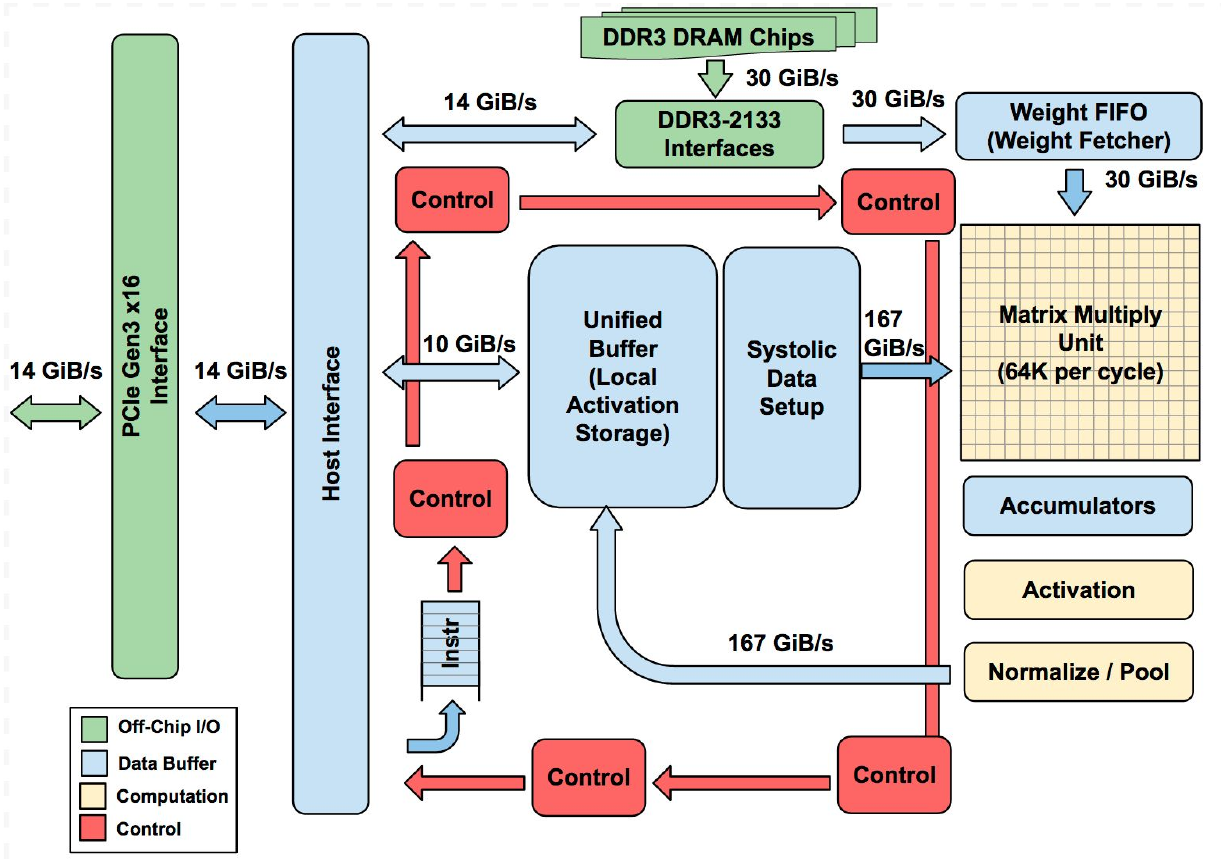
Mục tiêu là chạy toàn bộ các mô hình suy luận trên TPU để giảm tương tác với CPU máy chủ và đủ linh hoạt để đáp ứng nhu cầu NN của năm 2015 và những năm sau đó, thay vì chỉ đáp ứng những gì cần thiết cho các NN năm 2013. Hình 1 cho thấy sơ đồ khối của TPU.
The goal was to run whole inference models in the TPU to reduce interactions with the host CPU and to be flexible enough to match the NN needs of 2015 and beyond, instead of just what was required for 2013 NNs. Figure 1 shows the block diagram of the TPU.
Các lệnh TPU được gửi từ máy chủ qua bus PCIe Gen3 x16 vào một bộ đệm lệnh. Các khối bên trong thường được kết nối với nhau bằng các đường truyền rộng 256 byte. Bắt đầu từ góc trên bên phải, Matrix Multiply Unit là trung tâm của TPU. Nó chứa 256x256 MAC có thể thực hiện phép nhân-cộng 8-bit trên các số nguyên có dấu hoặc không dấu. Các tích 16-bit được tập hợp trong 4 MiB Accumulators 32-bit bên dưới đơn vị ma trận. 4MiB biểu diễn 4096 accumulator 32-bit, mỗi accumulator gồm 256 phần tử. Đơn vị ma trận tạo ra một tổng từng phần gồm 256 phần tử trong mỗi chu kỳ xung nhịp. Chúng tôi chọn 4096 bằng cách trước hết nhận thấy rằng số phép toán trên mỗi byte cần thiết để đạt hiệu năng cực đại (điểm gối roofline trong Section 4) là ~1350, nên chúng tôi làm tròn lên 2048 rồi nhân đôi nó để trình biên dịch có thể sử dụng double buffering khi chạy ở hiệu năng cực đại.
The TPU instructions are sent from the host over the PCIe Gen3 x16 bus into an instruction buffer. The internal blocks are typically connected together by 256-byte-wide paths. Starting in the upper-right corner, the Matrix Multiply Unit is the heart of the TPU. It contains 256x256 MACs that can perform 8-bit multiply-and-adds on signed or unsigned integers. The 16-bit products are collected in the 4 MiB of 32-bit Accumulators below the matrix unit. The 4MiB represents 4096, 256-element, 32-bit accumulators. The matrix unit produces one 256-element partial sum per clock cycle. We picked 4096 by first noting that the operations per byte need to reach peak performance (roofline knee in Section 4) is ~1350, so we rounded that up to 2048 and then duplicated it so that the compiler could use double buffering while running at peak performance.
Khi sử dụng kết hợp các trọng số 8-bit và các activation 16-bit (hoặc ngược lại), Matrix Unit tính toán ở tốc độ bằng một nửa, và tính toán ở tốc độ bằng một phần tư khi cả hai đều là 16 bit. Nó đọc và ghi 256 giá trị trong mỗi chu kỳ xung nhịp và có thể thực hiện phép nhân ma trận hoặc tích chập. Đơn vị ma trận chứa một tile trọng số 64 KiB cộng thêm một tile để double-buffering (để che giấu 256 chu kỳ cần thiết để dịch một tile vào). Đơn vị này được thiết kế cho các ma trận dày. Hỗ trợ kiến trúc thưa bị loại bỏ vì lý do thời gian triển khai. Tính thưa sẽ được ưu tiên cao trong các thiết kế tương lai.
When using a mix of 8-bit weights and 16-bit activations (or vice versa), the Matrix Unit computes at half-speed, and it computes at a quarter-speed when both are 16 bits. It reads and writes 256 values per clock cycle and can perform either a matrix multiply or a convolution. The matrix unit holds one 64 KiB tile of weights plus one for double-buffering (to hide the 256 cycles it takes to shift a tile in). This unit is designed for dense matrices. Sparse architectural support was omitted for time-to-deploy reasons. Sparsity will have high priority in future designs.
Các trọng số cho đơn vị ma trận được đưa qua một Weight FIFO on-chip, đọc từ một DRAM 8 GiB off-chip gọi là Weight Memory (đối với suy luận, các trọng số chỉ được đọc; 8 GiB hỗ trợ nhiều mô hình đang hoạt động đồng thời). Weight FIFO có độ sâu bốn tile. Các kết quả trung gian được lưu trong Unified Buffer on-chip 24 MiB, có thể cung cấp đầu vào cho Matrix Unit. Một bộ điều khiển DMA có thể lập trình truyền dữ liệu đến hoặc từ bộ nhớ Host CPU và Unified Buffer.
The weights for the matrix unit are staged through an on-chip Weight FIFO that reads from an off-chip 8 GiB DRAM called Weight Memory (for inference, weights are read-only; 8 GiB supports many simultaneously active models). The weight FIFO is four tiles deep. The intermediate results are held in the 24 MiB on-chip Unified Buffer, which can serve as inputs to the Matrix Unit. A programmable DMA controller transfers data to or from CPU Host memory and the Unified Buffer.
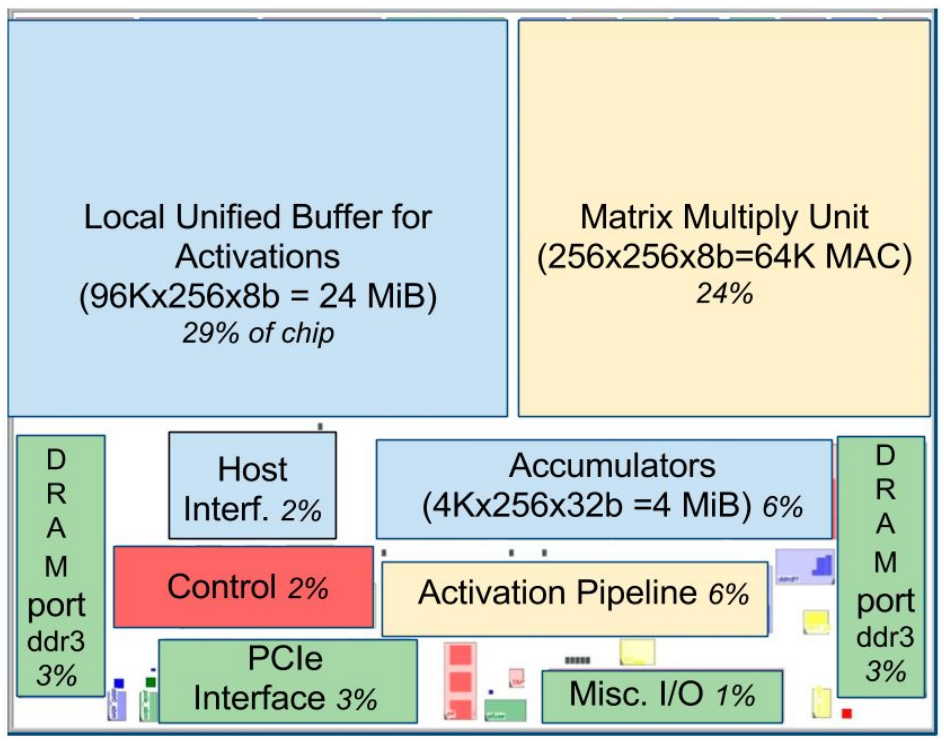
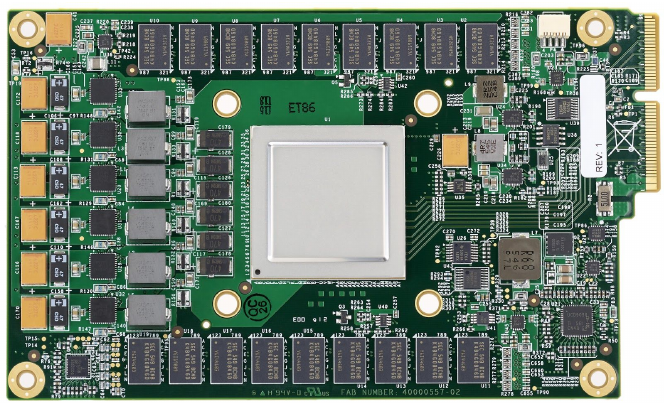
Hình 2 cho thấy sơ đồ bố trí khuôn của TPU. Unified Buffer 24 MiB chiếm gần một phần ba khuôn và Matrix Multiply Unit chiếm một phần tư, do đó datapath chiếm gần hai phần ba khuôn. Kích thước 24 MiB được chọn một phần để phù hợp với pitch của Matrix Unit trên khuôn và, do lịch trình phát triển ngắn, một phần để đơn giản hóa trình biên dịch (xem Section 7). Phần điều khiển chỉ chiếm 2%. Hình 3 cho thấy TPU trên card mạch in của nó, được cắm vào các server hiện có giống như một đĩa SATA.
Figure 2 shows the floor plan of the TPU die. The 24 MiB Unified Buffer is almost a third of the die and the Matrix Multiply Unit is a quarter, so the datapath is nearly two-thirds of the die. The 24 MiB size was picked in part to match the pitch of the Matrix Unit on the die and, given the short development schedule, in part to simplify the compiler (see Section 7). Control is just 2%. Figure 3 shows the TPU on its printed circuit card, which inserts into existing servers like an SATA disk.
Vì các lệnh được gửi qua bus PCIe tương đối chậm, các lệnh TPU tuân theo truyền thống CISC, bao gồm một trường lặp. Số chu kỳ xung nhịp trung bình trên mỗi lệnh (CPI) của các lệnh CISC này thường là 10 đến 20. Tổng cộng nó có khoảng một tá lệnh, nhưng năm lệnh sau đây là những lệnh then chốt:
As instructions are sent over the relatively slow PCIe bus, TPU instructions follow the CISC tradition, including a repeat field. The average clock cycles per instruction (CPI) of these CISC instructions is typically 10 to 20. It has about a dozen instructions overall, but these five are the key ones:
- Read_Host_Memory đọc dữ liệu từ bộ nhớ máy chủ CPU vào Unified Buffer (UB).
- Read_Weights đọc các trọng số từ Weight Memory vào Weight FIFO làm đầu vào cho Matrix Unit.
- MatrixMultiply/Convolve khiến Matrix Unit thực hiện phép nhân ma trận hoặc tích chập từ Unified Buffer vào các Accumulators. Một phép toán ma trận nhận đầu vào B256 có kích thước biến thiên, nhân nó với đầu vào trọng số hằng 256x256, và tạo ra đầu ra B256, cần B chu kỳ được đường ống hóa để hoàn thành.
- Read_Host_Memory reads data from the CPU host memory into the Unified Buffer (UB).
- Read_Weights reads weights from Weight Memory into the Weight FIFO as input to the Matrix Unit.
- MatrixMultiply/Convolve causes the Matrix Unit to perform a matrix multiply or a convolution from the Unified Buffer into the Accumulators. A matrix operation takes a variable-sized B256 input, multiplies it by a 256x256 constant weight input, and produces a B256 output, taking B pipelined cycles to complete.
- Activate thực hiện hàm phi tuyến của nơ-ron nhân tạo, với các tùy chọn cho ReLU, Sigmoid, v.v. Các đầu vào của nó là các Accumulator, và đầu ra của nó là Unified Buffer. Nó cũng có thể thực hiện các phép pooling cần thiết cho các phép tích chập bằng cách sử dụng phần cứng chuyên dụng trên die, vì nó được kết nối với logic hàm phi tuyến.
- Activate performs the nonlinear function of the artificial neuron, with options for ReLU, Sigmoid, and so on. Its inputs are the Accumulators, and its output is the Unified Buffer. It can also perform the pooling operations needed for convolutions using the dedicated hardware on the die, as it is connected to nonlinear function logic.
- Write_Host_Memory ghi dữ liệu từ Unified Buffer vào bộ nhớ host của CPU.
- Write_Host_Memory writes data from the Unified Buffer into the CPU host memory.
Các lệnh khác là đọc/ghi bộ nhớ host thay thế, thiết lập cấu hình, hai phiên bản đồng bộ hóa, ngắt host, debug-tag, nop, và halt. Lệnh CISC MatrixMultiply có 12 byte, trong đó 3 byte là địa chỉ Unified Buffer; 2 byte là địa chỉ accumulator; 4 byte là độ dài (đôi khi là 2 chiều đối với các phép tích chập); phần còn lại là opcode và cờ.
The other instructions are alternate host memory read/write, set configuration, two versions of synchronization, interrupt host, debug-tag, nop, and halt. The CISC MatrixMultiply instruction is 12 bytes, of which 3 are Unified Buffer address; 2 are accumulator address; 4 are length (sometimes 2 dimensions for convolutions); and the rest are opcode and flags.
Triết lý của vi kiến trúc TPU là giữ cho đơn vị ma trận luôn bận. Nó sử dụng pipeline 4 giai đoạn cho các lệnh CISC này, trong đó mỗi lệnh thực thi trong một giai đoạn riêng biệt. Kế hoạch là che giấu việc thực thi các lệnh khác bằng cách chồng lấp việc thực thi của chúng với lệnh MatrixMultiply. Nhằm đạt được mục đích đó, lệnh Read_Weights tuân theo triết lý decoupled-access/execute [Smi82], theo đó nó có thể hoàn thành sau khi gửi địa chỉ của nó nhưng trước khi trọng số được lấy từ Weight Memory. Đơn vị ma trận sẽ bị stall nếu activation đầu vào hoặc dữ liệu trọng số chưa sẵn sàng.
The philosophy of the TPU microarchitecture is to keep the matrix unit busy. It uses a 4-stage pipeline for these CISC instructions, where each instruction executes in a separate stage. The plan was to hide the execution of the other instructions by overlapping their execution with the MatrixMultiply instruction. Toward that end, the Read_Weights instruction follows the decoupled-access/execute philosophy [Smi82], in that it can complete after sending its address but before the weight is fetched from Weight Memory. The matrix unit will stall if the input activation or weight data is not ready.
Chúng tôi không có các sơ đồ chồng lấp pipeline rõ ràng, vì các lệnh CISC của chúng tôi có thể chiếm giữ một station trong hàng nghìn chu kỳ clock, không giống pipeline RISC truyền thống với một chu kỳ clock cho mỗi giai đoạn. Các trường hợp thú vị xảy ra khi các activation cho một lớp mạng phải hoàn thành trước khi các phép nhân ma trận của lớp tiếp theo có thể bắt đầu; chúng tôi thấy một “delay slot,” trong đó đơn vị ma trận chờ đồng bộ hóa tường minh trước khi đọc an toàn từ Unified Buffer.
We don’t have clean pipeline overlap diagrams, because our CISC instructions can occupy a station for thousands of clock cycles, unlike the traditional RISC pipeline with one clock cycle per stage. Interesting cases occur when the activations for one network layer must complete before the matrix multiplications of the next layer can begin; we see a “delay slot,” where the matrix unit waits for explicit synchronization before safely reading from the Unified Buffer.
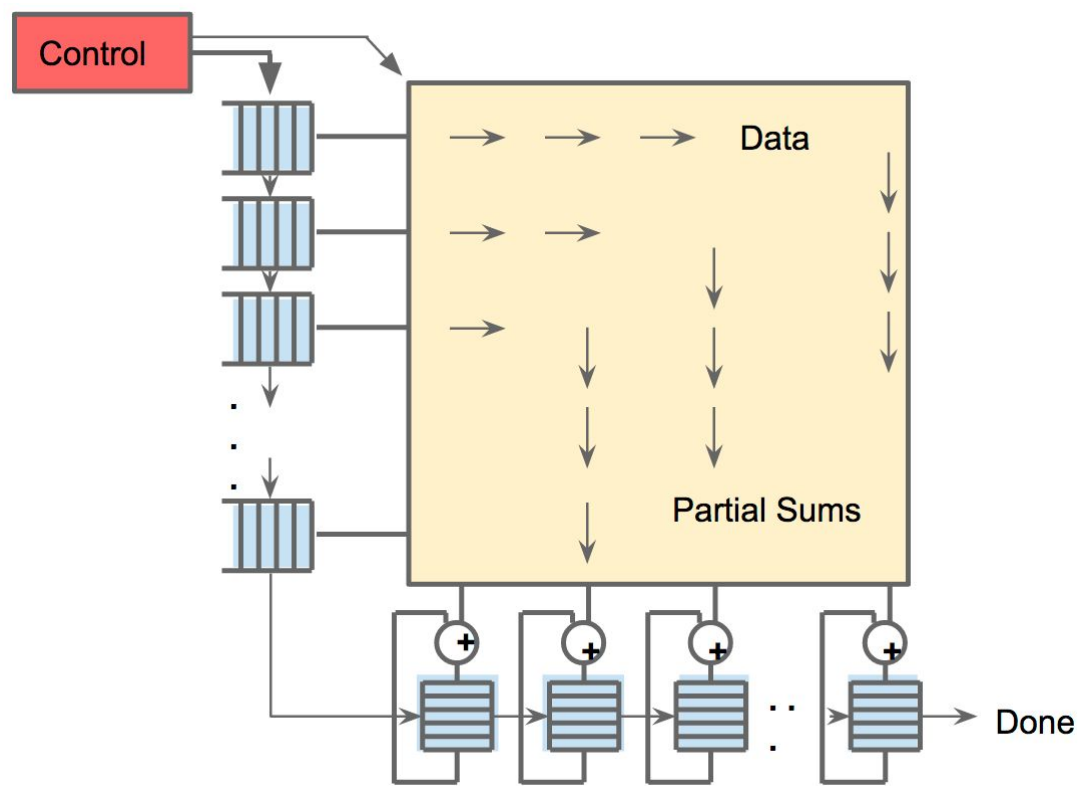
Vì việc đọc một SRAM lớn sử dụng nhiều năng lượng hơn nhiều so với phép toán số học, đơn vị ma trận sử dụng thực thi systolic để tiết kiệm năng lượng bằng cách giảm số lần đọc và ghi của Unified Buffer [Kun80][Ram91][Ovt15b]. Nó dựa vào dữ liệu từ các hướng khác nhau đến các ô trong một mảng tại các khoảng thời gian đều đặn, nơi chúng được kết hợp. Figure 4 cho thấy dữ liệu chảy vào từ bên trái, và các trọng số được nạp từ phía trên. Một phép nhân-tích lũy 256 phần tử nhất định di chuyển qua ma trận như một mặt sóng chéo. Các trọng số được nạp trước, và có hiệu lực cùng với mặt sóng đang tiến lên song song với dữ liệu đầu tiên của một block mới. Điều khiển và dữ liệu được pipeline để tạo ra ảo giác rằng 256 đầu vào được đọc cùng lúc, và rằng chúng cập nhật tức thời một vị trí của mỗi trong 256 accumulator. Xét về tính đúng đắn, phần mềm không nhận biết bản chất systolic của đơn vị ma trận, nhưng về hiệu năng, nó quan tâm đến độ trễ của đơn vị.
As reading a large SRAM uses much more power than arithmetic, the matrix unit uses systolic execution to save energy by reducing reads and writes of the Unified Buffer [Kun80][Ram91][Ovt15b]. It relies on data from different directions arriving at cells in an array at regular intervals where they are combined. Figure 4 shows that data flows in from the left, and the weights are loaded from the top. A given 256-element multiply-accumulate operation moves through the matrix as a diagonal wavefront. The weights are preloaded, and take effect with the advancing wave alongside the first data of a new block. Control and data are pipelined to give the illusion that the 256 inputs are read at once, and that they instantly update one location of each of 256 accumulators. From a correctness perspective, software is unaware of the systolic nature of the matrix unit, but for performance, it does worry about the latency of the unit.
Ngăn xếp phần mềm TPU phải tương thích với các ngăn xếp được phát triển cho CPU và GPU để các ứng dụng có thể được chuyển nhanh sang TPU. Phần của ứng dụng chạy trên TPU thường được viết bằng TensorFlow và được biên dịch thành một API có thể chạy trên GPU hoặc TPU [Lar16]. Giống như GPU, ngăn xếp TPU được chia thành User Space Driver và Kernel Driver. Kernel Driver nhẹ và chỉ xử lý quản lý bộ nhớ và các ngắt. Nó được thiết kế để ổn định trong dài hạn. User Space driver thay đổi thường xuyên. Nó thiết lập và điều khiển thực thi TPU, định dạng lại dữ liệu theo thứ tự TPU, dịch các lời gọi API thành các lệnh TPU, và biến chúng thành một binary ứng dụng. User Space driver biên dịch một mô hình lần đầu tiên nó được đánh giá, lưu cache ảnh chương trình và ghi ảnh trọng số vào bộ nhớ trọng số của TPU; lần đánh giá thứ hai và các lần tiếp theo chạy ở tốc độ tối đa. TPU chạy hầu hết các mô hình hoàn toàn từ đầu vào đến đầu ra, tối đa hóa tỷ lệ giữa thời gian tính toán TPU và thời gian I/O. Tính toán thường được thực hiện từng lớp một, với thực thi chồng lấp cho phép đơn vị nhân ma trận che giấu hầu hết các thao tác không nằm trên đường quan trọng.
The TPU software stack had to be compatible with those developed for CPUs and GPUs so that applications could be ported quickly to the TPU. The portion of the application run on the TPU is typically written in TensorFlow and is compiled into an API that can run on GPUs or TPUs [Lar16]. Like GPUs, the TPU stack is split into a User Space Driver and a Kernel Driver. The Kernel Driver is lightweight and handles only memory management and interrupts. It is designed for long-term stability. The User Space driver changes frequently. It sets up and controls TPU execution, reformats data into TPU order, translates API calls into TPU instructions, and turns them into an application binary. The User Space driver compiles a model the first time it is evaluated, caching the program image and writing the weight image into the TPU’s weight memory; the second and following evaluations run at full speed. The TPU runs most models completely from inputs to outputs, maximizing the ratio of TPU compute time to I/O time. Computation is often done one layer at a time, with overlapped execution allowing the matrix multiply unit to hide most non-critical-path operations.
              Model  Die  Benchmarked Servers  Measured
mm^2  nm  MHz  TDP  Measured  TOPS/s  GB/s  On-Chip Memory  Dies  DRAM Size  TDP  Idle  Busy
Haswell E5-2699 v3  662  22  2300  145W  41W  145W  2.6  1.3  51  51 MiB  2  256 GiB  504W  159W  455W
NVIDIA K80 (2 dies/card)  561  28  560  150W  25W  98W  --  2.8  160  8 MiB  8  256 GiB (host) + 12 GiB x 8  1838W  357W  991W
TPU  NA*  28  700  75W  28W  40W  92  --  34  28 MiB  4  256 GiB (host) + 8 GiB x 4  861W  290W  384W
              Model  Die  Benchmarked Servers  Measured
mm^2  nm  MHz  TDP  Measured  TOPS/s  GB/s  On-Chip Memory  Dies  DRAM Size  TDP  Idle  Busy
Haswell E5-2699 v3  662  22  2300  145W  41W  145W  2.6  1.3  51  51 MiB  2  256 GiB  504W  159W  455W
NVIDIA K80 (2 dies/card)  561  28  560  150W  25W  98W  --  2.8  160  8 MiB  8  256 GiB (host) + 12 GiB x 8  1838W  357W  991W
TPU  NA*  28  700  75W  28W  40W  92  --  34  28 MiB  4  256 GiB (host) + 8 GiB x 4  861W  290W  384W
Table 2. Các server được đo chuẩn sử dụng CPU Haswell, GPU K80, và TPU. Haswell có 18 lõi, và K80 có 13 bộ xử lý SMX. Figure 10 có công suất đã đo. TPU công suất thấp cho phép mật độ cấp rack tốt hơn so với GPU công suất cao. 8 GiB DRAM trên mỗi TPU là Weight Memory. Chế độ GPU Boost không được sử dụng (Sec. 8). SECDEC và không sử dụng chế độ Boost làm giảm băng thông K80 từ 240 xuống 160. Không sử dụng chế độ Boost và hiệu năng của single die so với dual die làm giảm TOPS cực đại của K80 từ 8.7 xuống 2.8. (*Die TPU có kích thước ≤ một nửa kích thước die Haswell.)
Table 2. Benchmarked servers use Haswell CPUs, K80 GPUs, and TPUs. Haswell has 18 cores, and the K80 has 13 SMX processors. Figure 10 has measured power. The low-power TPU allows for better rack-level density than the high-power GPU. The 8 GiB DRAM per TPU is Weight Memory. GPU Boost mode is not used (Sec. 8). SECDEC and no Boost mode reduce K80 bandwidth from 240 to 160. No Boost mode and single die vs. dual die performance reduces K80 peak TOPS from 8.7 to 2.8. (*The TPU die is ≤ half the Haswell die size.)
3 Các nền tảng CPU, GPU và TPU
3 CPU, GPU, and TPU Platforms
Sáu ứng dụng đang vận hành thực tế trong Bảng 1 là tải công việc của chúng tôi trong bài báo này. Như đã đề cập ở trên, sáu ứng dụng này đại diện cho 95% mức sử dụng TPU trong các trung tâm dữ liệu của chúng tôi. Trớ trêu thay, việc triển khai và đo lường các mạng nơ-ron sâu (DNN) nhỏ phổ biến như AlexNet hoặc VGG trên các máy đang vận hành thực tế lại khó khăn. Tuy nhiên, một trong các mạng nơ-ron tích chập (CNN) của chúng tôi bắt nguồn từ Inception V2, vốn được sử dụng rộng rãi.
The six production applications in Table 1 are our workload for this paper. As mentioned above, these six are representative of 95% of TPU use in our datacenters. Ironically, deploying and measuring popular small DNNs like AlexNet or VGG is difficult on production machines. However, one of our CNNs derives from Inception V2, which is widely used.
Các nền tảng đo chuẩn là những máy tính cấp server có sẵn vào năm 2015, khi TPU được triển khai. Ràng buộc này có nghĩa là chúng phải có ít nhất cơ chế bảo vệ sửa lỗi một bit và phát hiện lỗi hai bit (SECDED) cho SRAM bên trong cũng như bộ nhớ DRAM bên ngoài giống như TPU, qua đó loại trừ một số lựa chọn như GPU Nvidia Maxwell. Để công ty chúng tôi mua và triển khai, chúng cũng phải là những máy có cấu hình hợp lý, chứ không phải những hệ thống chắp vá được lắp ráp chỉ để thắng các phép đo chuẩn.
The benchmark platforms are server-class computers that were available in 2015 when the TPUs were deployed. This restriction meant that they must include at least SECDED protection of internal SRAM as well as external DRAM memory like the TPU, which excludes some choices such as the Nvidia Maxwell GPU. For our company to purchase and deploy them, they also had to be sensibly configured machines, and not awkward artifacts assembled solely to win benchmarks.
Bảng 2 liệt kê các lựa chọn của chúng tôi. Đại diện cho server CPU truyền thống là bộ xử lý Haswell 18 lõi của Intel trong hệ thống hai socket. Nền tảng này cũng là server chủ cho GPU hoặc TPU. Haswell được chế tạo bằng quy trình 22nm của Intel. Cả CPU lẫn GPU đều có đế bán dẫn rất lớn: khoảng 600 mm²!
Table 2 lists our choices. The traditional CPU server is represented by an 18-core, dual-socket Haswell processor from Intel. This platform is also the host server for GPUs or TPUs. Haswell was fabbed in an Intel 22nm process. Both the CPU and GPU are very large dies: about 600 mm²!
Tần số xung nhịp CPU 2.3 GHz không bao gồm chế độ Turbo vì chế độ này hiếm khi hoạt động với các ứng dụng mạng nơ-ron trong các trung tâm dữ liệu của chúng tôi. Haswell có các tần số xung nhịp khác nhau tùy thuộc vào việc chương trình có sử dụng các lệnh AVX hay không; các ứng dụng mạng nơ-ron của chúng tôi thường sử dụng những lệnh này. Tần số xung nhịp cao hơn của chế độ Turbo (dành cho các chương trình không dùng AVX) xuất hiện khi chúng không sử dụng hết các lõi. Do đó, một lý do khác khiến chế độ Turbo hiếm khi hoạt động trong các trung tâm dữ liệu của chúng tôi là các ứng dụng thường sử dụng hết các lõi; hơn nữa, các máy có thể chạy những công việc khác của trung tâm dữ liệu để tận dụng mọi lõi đang nhàn rỗi.
The 2.3 GHz CPU clock rate doesn’t include Turbo mode because it seldom occurs in our datacenters for NN apps. Haswell has different clock rates depending on whether programs use AVX instructions, which our NN apps often use. The higher clock rate of Turbo mode (for programs that avoid AVX) occurs when they don’t use all their cores. Thus, another reason Turbo mode is rare in our datacenters is that our apps typically do use all the cores, plus they can run other datacenter jobs to fill any idle cores.
Bộ tăng tốc GPU là Nvidia K80. Mỗi card K80 chứa hai đế bán dẫn và cung cấp SECDED cho bộ nhớ bên trong và DRAM. Nvidia tuyên bố rằng “Bộ tăng tốc K80 giảm mạnh chi phí trung tâm dữ liệu bằng cách cung cấp hiệu năng ứng dụng với ít server hơn nhưng mạnh hơn”[Nvi16]. Các nhà nghiên cứu mạng nơ-ron thường xuyên sử dụng K80 vào năm 2015, và đến tận tháng 9 năm 2016, K80 vẫn được chọn cho các dịch vụ GPU mới trên nền tảng đám mây [Bar16].
The GPU accelerator is the Nvidia K80. Each K80 card contains two dies and offers SECDED on internal memory and DRAM. Nvidia states that the “K80 Accelerator dramatically lowers datacenter cost by delivering application performance with fewer, more powerful servers”[Nvi16]. NN researchers frequently used K80s in 2015, and they were chosen for new cloud-based GPU offerings as recently as September 2016 [Bar16].
Có thể lắp tối đa tám đế bán dẫn K80 trên bốn card vào server này, và đây là cấu hình chúng tôi dùng để đo chuẩn. K80 cung cấp chế độ Boost để tăng tần số xung nhịp lên tới 875 MHz. Chế độ Turbo trong Haswell được phần cứng điều khiển nên có thể hoạt động trong những đợt ngắn trước khi nhiệt độ chip tăng đáng kể. Tuy nhiên, chế độ Boost do trình điều khiển phần mềm kiểm soát [Nvi15], nên kéo dài ít nhất hàng trăm mili giây. Vì vậy, hệ thống cấp điện và làm mát phải được trang bị cho K80 như thể nó gần như luôn chạy ở chế độ Boost; nếu không, các chip có thể quá nóng. Với nền tảng này, bật chế độ Boost sẽ buộc chúng tôi phải giảm số lượng card K80, gây bất lợi về tổng chi phí sở hữu. Do đó, chế độ Boost bị tắt. Ràng buộc này làm giảm băng thông đỉnh và TOPS (xem chú thích Bảng 2); Mục 8 xem xét trường hợp chế độ này được bật.
Up to eight K80 dies can be installed in four cards on this server, which is the configuration we benchmark. It offers a Boost mode to increase clock rate as high as 875 MHz. Turbo mode in Haswell is controlled by hardware and so can operate in short bursts before the chip temperature rises significantly. However, Boost mode is under the control of a software driver [Nvi15], and thus lasts at least hundreds of milliseconds. Hence, power and cooling would have to be provisioned for the K80 as if it were essentially always running in Boost mode, for otherwise the chips could get too hot. For this platform, enabling Boost mode would force us to reduce the number of K80 cards, which would hurt total cost of ownership. Thus, Boost mode is disabled. This restriction reduces peak bandwidth and TOPS (see Table 2 caption); Sec. 8 examines if it were enabled.
Vì số đế bán dẫn trên mỗi server được đo chuẩn dao động từ 2 đến 8, các kết quả dưới đây thường được chúng tôi chuẩn hóa theo từng đế bán dẫn (các Hình 5-8, các Hình 10-11 và các Bảng 3, 4 và 6), nhưng đôi khi chúng tôi trình bày kết quả cho toàn bộ hệ thống (Hình 9). Chúng tôi hy vọng sự phân biệt này là rõ ràng.
As the number of dies per benchmarked server varies between 2 to 8, we usually show results below normalized per die (Figures 5-8, Figures 10-11, and Tables 3, 4, and 6), but we occasionally show whole systems (Figure 9). We hope this distinction is clear.
4 Hiệu năng: Roofline, thời gian đáp ứng, và thông lượng
4 Performance: Rooflines, Response-Time, and Throughput
Để minh họa hiệu năng của sáu ứng dụng trên ba bộ xử lý, chúng tôi điều chỉnh mô hình Hiệu năng Roofline từ lĩnh vực tính toán hiệu năng cao (HPC) [Wil09]. Mô hình trực quan đơn giản này không hoàn hảo, tuy nhiên nó cung cấp những hiểu biết về nguyên nhân của các nút thắt hiệu năng. Giả định đằng sau mô hình là các ứng dụng không vừa trong các cache on-chip, vì vậy chúng bị giới hạn bởi tính toán hoặc bị giới hạn bởi băng thông bộ nhớ. Đối với HPC, trục Y là hiệu năng theo số phép toán dấu phẩy động trên giây, do đó tốc độ tính toán cực đại tạo thành phần “phẳng” của đường mái. Trục X là cường độ vận hành, được đo bằng số phép toán dấu phẩy động trên mỗi byte DRAM được truy cập. Băng thông bộ nhớ là số byte trên giây, biến thành phần “xiên” của đường mái vì (FLOPS/sec)/(FLOPS/Byte) = Bytes/sec. Nếu không có đủ cường độ vận hành, một chương trình bị giới hạn bởi băng thông bộ nhớ và nằm dưới phần xiên của đường mái.
To illustrate the performance of the six apps on the three processors, we adapt the Roofline Performance model from high-performance computing (HPC) [Wil09]. This simple visual model is not perfect, yet it offers insights on the causes of performance bottlenecks. The assumption behind the model is that applications don’t fit in on-chip caches, so they are either computation-limited or memory bandwidth-limited. For HPC, the Y-axis is performance in floating-point operations per second, thus the peak computation rate forms the “flat” part of the roofline. The X-axis is operational intensity, measured as floating-point operations per DRAM byte accessed. Memory bandwidth is bytes per second, which turns into the “slanted” part of the roofline since (FLOPS/sec)/(FLOPS/Byte) = Bytes/sec. Without sufficient operational intensity, a program is memory bandwidth-bound and lives under the slanted part of the roofline.
Khoảng cách giữa số phép toán thực tế trên giây của một ứng dụng và mức trần ngay phía trên nó cho thấy lợi ích tiềm năng của việc tinh chỉnh hiệu năng thêm trong khi giữ nguyên cường độ vận hành; tất nhiên, các tối ưu hóa làm tăng cường độ vận hành (chẳng hạn như cache blocking) có thể mang lại lợi ích còn lớn hơn.
The gap between the actual operations per second of an application and the ceiling directly above it shows the potential benefit of further performance tuning while leaving operational intensity untouched; of course, optimizations that increase operational intensity (such as cache blocking) may yield even greater benefit.
Để sử dụng mô hình Roofline cho TPU, khi các ứng dụng NN được lượng tử hóa, trước tiên chúng tôi thay thế các phép toán dấu phẩy động bằng các phép toán số nguyên. Vì các trọng số thường không vừa trong bộ nhớ on-chip đối với các ứng dụng NN, thay đổi thứ hai là định nghĩa lại cường độ vận hành thành số phép toán số nguyên trên mỗi byte của weights được đọc (xem cột thứ mười của Table 1).
To use the Roofline model for the TPU, when NN applications are quantized, we first replace floating-point operations with integer operations. As weights do not normally fit in on-chip memory for NN applications, the second change is to redefine operational intensity to be integer operations per byte of weights read (see the tenth column of Table 1).
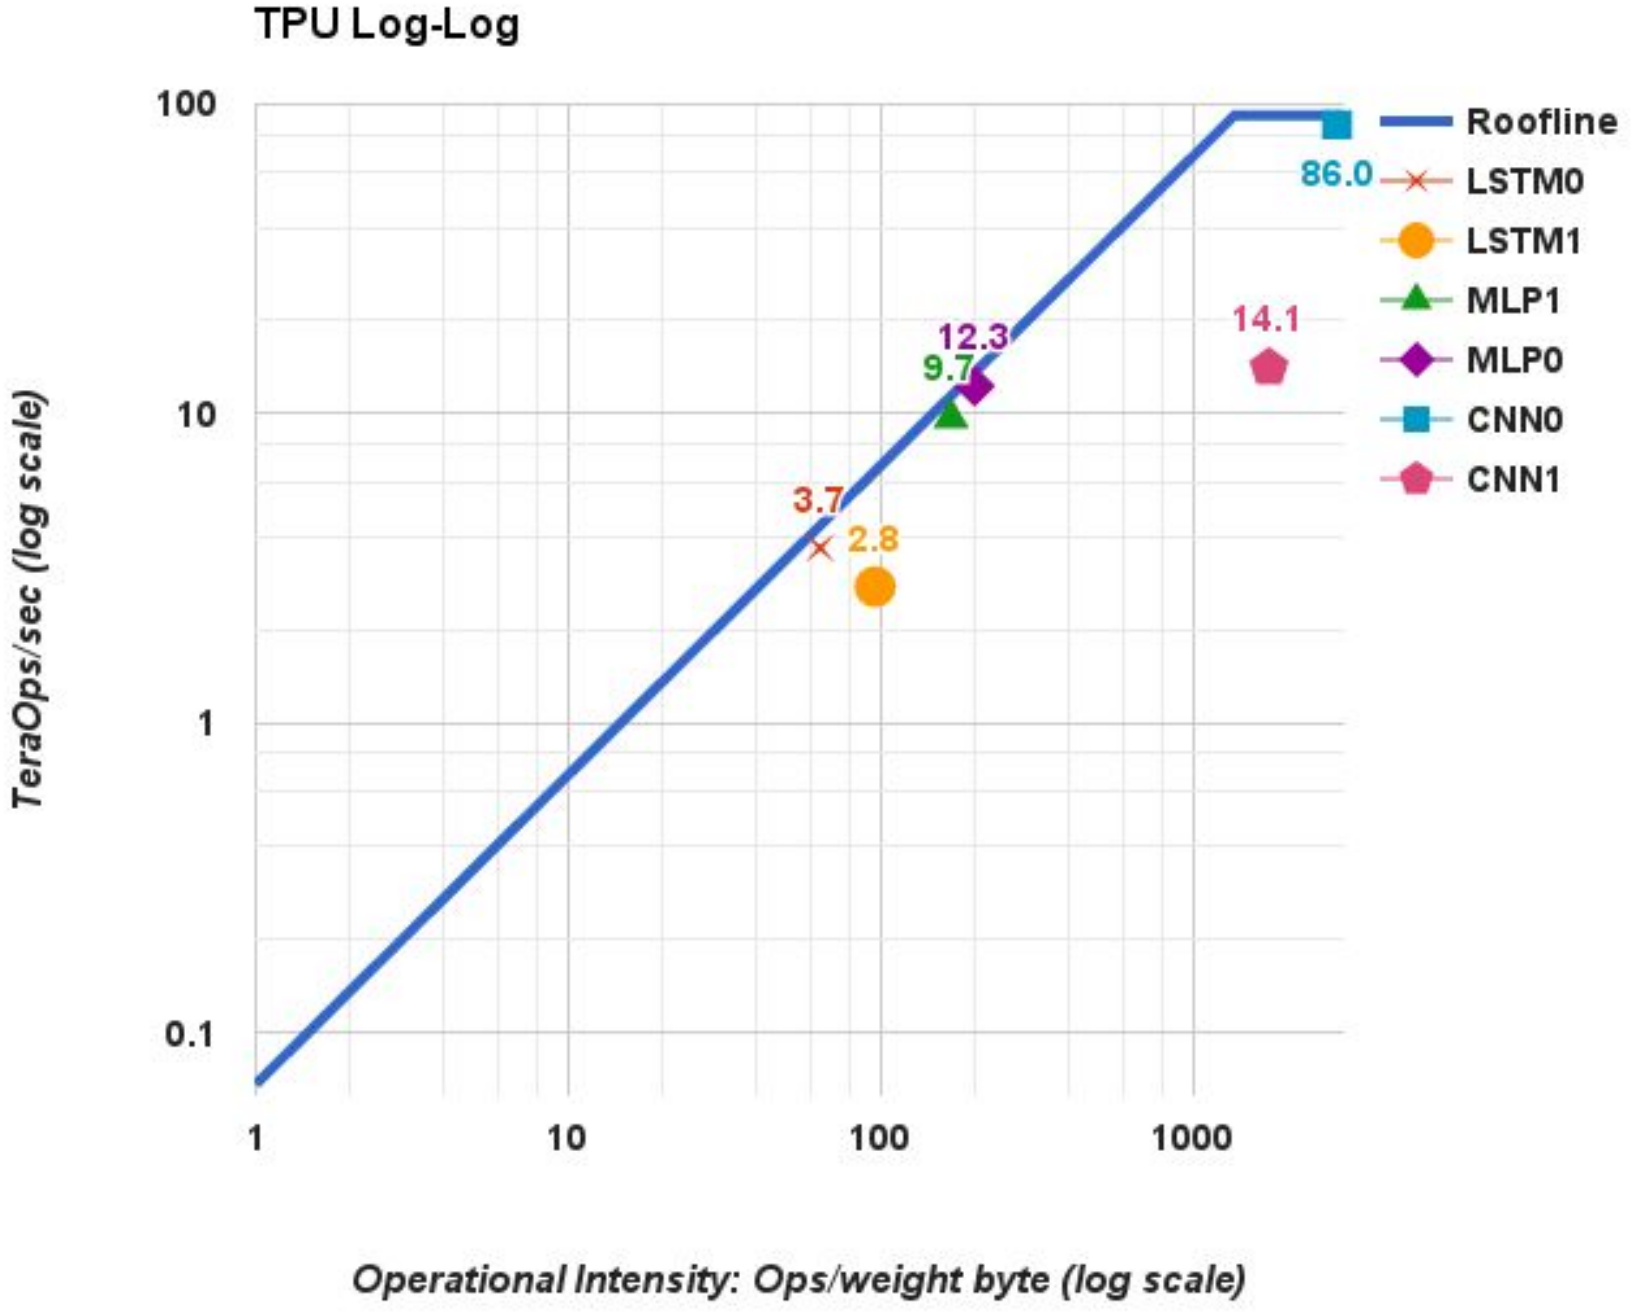
Figure 5 cho thấy mô hình Roofline cho một die TPU đơn lẻ trên các thang đo log-log. TPU có một phần “xiên” dài của đường mái, trong đó cường độ vận hành có nghĩa là hiệu năng bị giới hạn bởi băng thông bộ nhớ thay vì bởi tính toán cực đại. Năm trong sáu ứng dụng đang chạm vào mức trần: các MLP và LSTM bị giới hạn bởi bộ nhớ, còn CNN bị giới hạn bởi tính toán. CNN1, mặc dù có cường độ vận hành rất cao, chỉ chạy ở 14.1 TOPS trong khi CNN0 chạy ở 86 TOPS.
Figure 5 shows the Roofline model for a single TPU die on log-log scales. The TPU has a long “slanted” part of its roofline, where operational intensity means that performance is limited by memory bandwidth rather than by peak compute. Five of the six applications are happily bumping their heads against the ceiling: the MLPs and LSTMs are memory bound, and CNNs are computation bound. CNN1, despite a very high operational intensity, is running at only 14.1 TOPS while CNN0 runs at 86 TOPS.
Table 3 giải thích điều gì đã xảy ra với CNN1, dựa trên các bộ đếm hiệu năng cung cấp cho chúng tôi khả năng quan sát một phần hoạt động của TPU. TPU dành ít hơn một nửa số chu kỳ của nó để thực hiện các phép toán ma trận cho CNN1 (cột 7, hàng 1). Trong mỗi chu kỳ hoạt động đó, chỉ khoảng một nửa trong số 65,536 MAC chứa các trọng số hữu ích vì một số lớp trong CNN1 có độ sâu đặc trưng nhỏ. Khoảng 35% số chu kỳ được dành để chờ các trọng số được nạp từ bộ nhớ vào đơn vị ma trận, điều này xảy ra trong 4 lớp kết nối đầy đủ chạy ở cường độ vận hành chỉ 32 (xem Fallacy cuối cùng trong Section 8). Điều này để lại khoảng 19% số chu kỳ chưa được giải thích bởi các bộ đếm liên quan đến ma trận. Do thực thi chồng lấp trên TPU, chúng tôi không có hạch toán chính xác cho các chu kỳ đó, nhưng chúng tôi có thể thấy rằng 23% số chu kỳ có các lần dừng do các phụ thuộc RAW trong đường ống, và 1% được dành để dừng do đầu vào qua bus PCIe.
Table 3 explains what happened with CNN1, based on the performance counters that give us partial visibility into TPU operation. The TPU spends less than half of its cycles performing matrix operations for CNN1 (column 7, row 1). On each of those active cycles, only about half of the 65,536 MACs hold useful weights because some layers in CNN1 have shallow feature depths. About 35% of cycles are spent waiting for weights to load from memory into the matrix unit, which occurs during the 4 fully connected layers that run at an operational intensity of just 32 (see the last Fallacy in Section 8). This leaves roughly 19% of cycles not explained by the matrix-related counters. Because of overlapped execution on the TPU, we do not have exact accounting for those cycles, but we can see that 23% of cycles have stalls for RAW dependences in the pipeline, and 1% are spent stalled for input over the PCIe bus.
| Ứng dụng | MLP0 | MLP1 | LSTM0 | LSTM1 | CNN0 | CNN1 | Trung bình | Hàng |
|---|---|---|---|---|---|---|---|---|
| Các chu kỳ hoạt động của mảng | 12.7% | 10.6% | 8.2% | 10.5% | 78.2% | 46.2% | 28% | 1 |
| MAC hữu ích trong ma trận 64K (% cực đại) | 12.5% | 9.4% | 8.2% | 6.3% | 78.2% | 22.5% | 23% | 2 |
| MAC không được sử dụng | 0.3% | 1.2% | 0.0% | 4.2% | 0.0% | 23.7% | 5% | 3 |
| Các chu kỳ dừng do trọng số | 53.9% | 44.2% | 58.1% | 62.1% | 0.0% | 28.1% | 43% | 4 |
| Các chu kỳ dịch chuyển trọng số | 15.9% | 13.4% | 15.8% | 17.1% | 0.0% | 7.0% | 12% | 5 |
| Các chu kỳ không thuộc ma trận | 17.5% | 31.9% | 17.9% | 10.3% | 21.8% | 18.7% | 20% | 6 |
| Các lần dừng RAW | 3.3% | 8.4% | 14.6% | 10.6% | 3.5% | 22.8% | 11% | 7 |
| Các lần dừng dữ liệu đầu vào | 6.1% | 8.8% | 5.1% | 2.4% | 3.4% | 0.6% | 4% | 8 |
| TeraOps/sec (92 Peak) | 12.3 | 9.7 | 3.7 | 2.8 | 86.0 | 14.1 | 21.4 | 9 |
| Application | MLP0 | MLP1 | LSTM0 | LSTM1 | CNN0 | CNN1 | Mean | Row |
|---|---|---|---|---|---|---|---|---|
| Array active cycles | 12.7% | 10.6% | 8.2% | 10.5% | 78.2% | 46.2% | 28% | 1 |
| Useful MACs in 64K matrix (% peak) | 12.5% | 9.4% | 8.2% | 6.3% | 78.2% | 22.5% | 23% | 2 |
| Unused MACs | 0.3% | 1.2% | 0.0% | 4.2% | 0.0% | 23.7% | 5% | 3 |
| Weight stall cycles | 53.9% | 44.2% | 58.1% | 62.1% | 0.0% | 28.1% | 43% | 4 |
| Weight shift cycles | 15.9% | 13.4% | 15.8% | 17.1% | 0.0% | 7.0% | 12% | 5 |
| Non-matrix cycles | 17.5% | 31.9% | 17.9% | 10.3% | 21.8% | 18.7% | 20% | 6 |
| RAW stalls | 3.3% | 8.4% | 14.6% | 10.6% | 3.5% | 22.8% | 11% | 7 |
| Input data stalls | 6.1% | 8.8% | 5.1% | 2.4% | 3.4% | 0.6% | 4% | 8 |
| TeraOps/sec (92 Peak) | 12.3 | 9.7 | 3.7 | 2.8 | 86.0 | 14.1 | 21.4 | 9 |
Table 3. Các yếu tố giới hạn hiệu năng TPU của tải công việc NN dựa trên các bộ đếm hiệu năng phần cứng. Các hàng 1, 4, 5, và 6 tổng cộng bằng 100% và dựa trên các phép đo hoạt động của đơn vị ma trận. Các hàng 2 và 3 tiếp tục phân rã phần nhỏ của 64K trọng số trong đơn vị ma trận chứa các trọng số hữu ích trong các chu kỳ hoạt động. Các bộ đếm của chúng tôi không thể giải thích chính xác thời gian khi đơn vị ma trận không hoạt động trong hàng 6; các hàng 7 và 8 hiển thị các bộ đếm cho hai nguyên nhân có thể, bao gồm các nguy cơ của đường ống RAW và các lần dừng đầu vào PCIe. Hàng 9 (TOPS) dựa trên các phép đo của mã sản xuất trong khi các hàng khác dựa trên các phép đo bộ đếm hiệu năng, vì vậy chúng không hoàn toàn nhất quán. Chi phí phụ trội của server máy chủ được loại trừ ở đây. Các MLP và LSTM bị giới hạn bởi băng thông bộ nhớ nhưng CNN thì không. Kết quả CNN1 được giải thích trong văn bản.
Table 3. Factors limiting TPU performance of the NN workload based on hardware performance counters. Rows 1, 4, 5, and 6 total 100% and are based on measurements of activity of the matrix unit. Rows 2 and 3 further break down the fraction of 64K weights in the matrix unit that hold useful weights on active cycles. Our counters cannot exactly explain the time when the matrix unit is idle in row 6; rows 7 and 8 show counters for two possible reasons, including RAW pipeline hazards and PCIe input stalls. Row 9 (TOPS) is based on measurements of production code while the other rows are based on performance-counter measurements, so they are not perfectly consistent. Host server overhead is excluded here. The MLPs and LSTMs are memory-bandwidth limited but CNNs are not. CNN1 results are explained in the text.
Figure.
Figure.
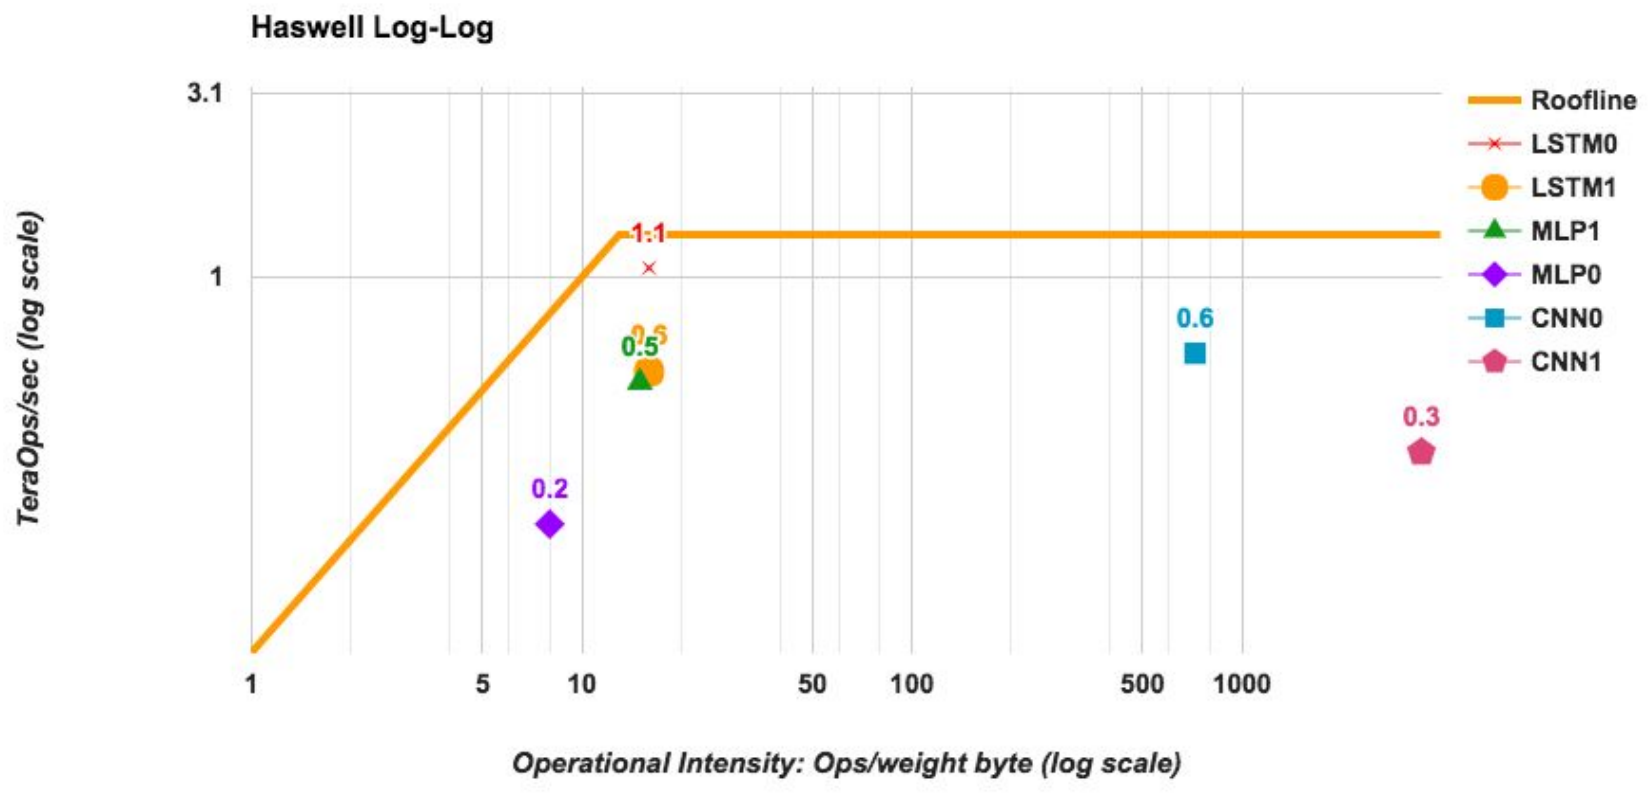
Figure.
Figure.
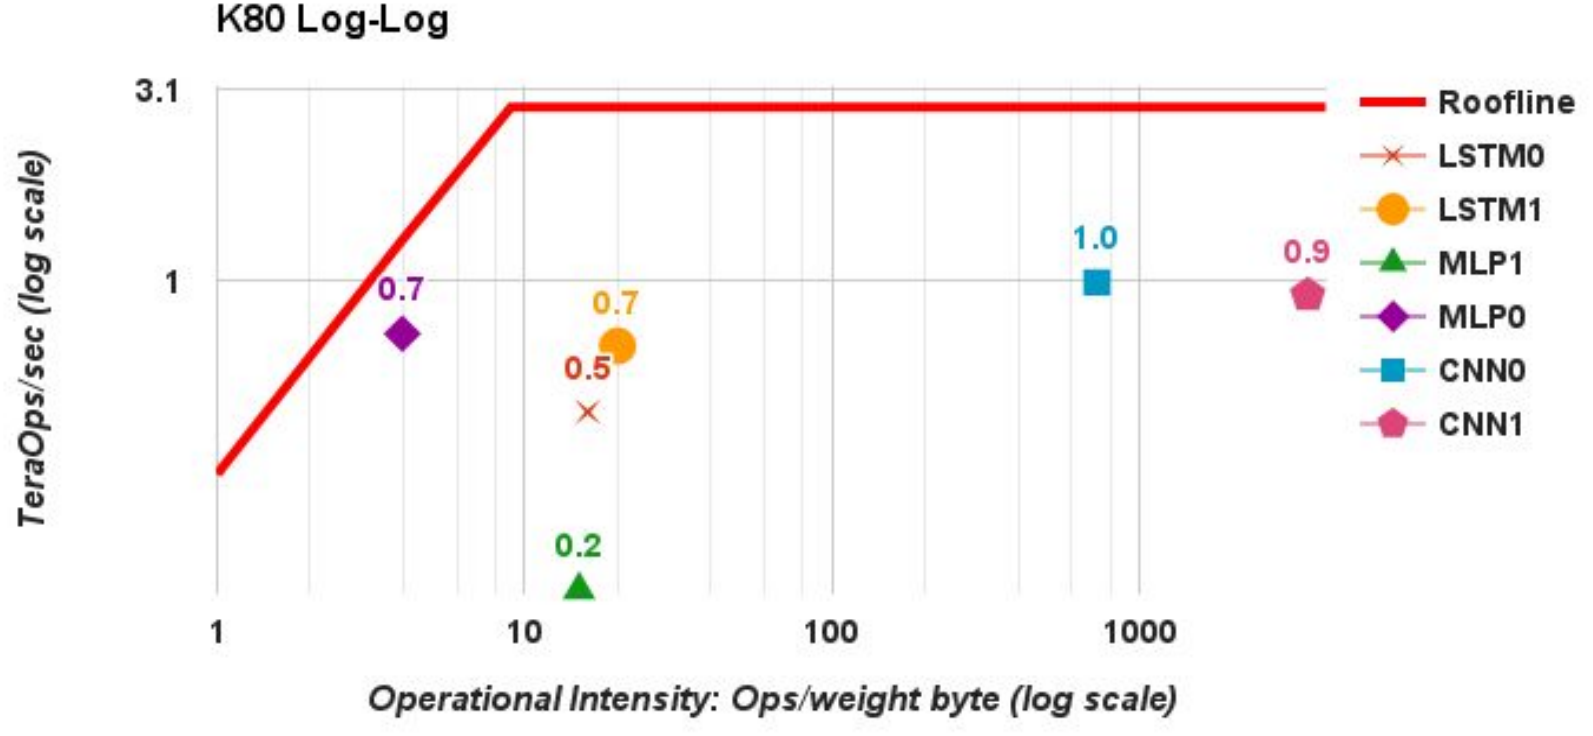
Hình 6 và 7 cho thấy các đường mái (roofline) cho một die Haswell đơn và một die K80 đơn. Sáu ứng dụng NN nhìn chung nằm xa hơn bên dưới các giới hạn của chúng so với TPU trong Hình 5. Thời gian đáp ứng là lý do. Nhiều ứng dụng NN này là các phần của các dịch vụ hướng đến người dùng cuối. Các nhà nghiên cứu đã chứng minh rằng những gia tăng nhỏ trong thời gian đáp ứng khiến khách hàng sử dụng một dịch vụ ít hơn [Sch09]. Vì vậy, trong khi huấn luyện có thể không có các thời hạn cứng về thời gian đáp ứng, suy luận thường có. Nghĩa là, suy luận ưu tiên độ trễ hơn thông lượng [Pat04].
Figures 6 and 7 show rooflines for a single Haswell die and for a single K80 die. The six NN applications are generally further below their ceilings than was the TPU in Figure 5. Response time is the reason. Many of these NN applications are parts of end-user-facing services. Researchers have demonstrated that small increases in response time cause customers to use a service less [Sch09]. Hence, while training may not have hard response time deadlines, inference usually does. That is, inference prefers latency over throughput [Pat04].
Bảng 4 minh họa tác động của giới hạn thời gian đáp ứng phân vị thứ 99 là 7 ms đối với MLP0 trên Haswell và K80 [Dea13], giới hạn này được yêu cầu bởi nhà phát triển ứng dụng. (Số lần suy luận mỗi giây và độ trễ 7 ms bao gồm thời gian của server host cũng như thời gian của bộ tăng tốc.) Chúng hoạt động lần lượt ở mức 42% và 37% thông lượng cao nhất có thể đạt được cho MLP0 nếu giới hạn thời gian đáp ứng được nới lỏng. Vì vậy, mặc dù CPU và GPU có thông lượng tiềm năng cao hơn nhiều, nó bị lãng phí nếu chúng không đáp ứng giới hạn thời gian đáp ứng. Các cận này cũng ảnh hưởng đến TPU, nhưng ở mức 80% trong Bảng 4, nó đang hoạt động gần hơn nhiều với thông lượng MLP0 cao nhất của mình. So với CPU và GPU, TPU đơn luồng không có bất kỳ tính năng vi kiến trúc phức tạp nào tiêu tốn transistor và năng lượng để cải thiện trường hợp trung bình nhưng không cải thiện trường hợp phân vị thứ 99: không có cache, dự đoán nhánh, thực thi ngoài thứ tự, xử lý đa tiến trình, nạp trước đầu cơ, hợp nhất địa chỉ, đa luồng, chuyển đổi ngữ cảnh, v.v. Chủ nghĩa tối giản là một ưu điểm của các bộ xử lý chuyên biệt theo miền.
Table 4 illustrates the impact of the 99th-percentile response time limit of 7 ms for MLP0 on Haswell and the K80 [Dea13], which was required by the application developer. (The inferences per second and 7 ms latency include the server host time as well as the accelerator time.) They operate at 42% and 37%, respectively, of the highest throughput achievable for MLP0 if the response time limit was relaxed. Thus, while CPUs and GPUs have potentially much higher throughput, it’s wasted if they don’t meet the response time limit. These bounds affect the TPU as well, but at 80% in Table 4 it is operating much closer to its highest MLP0 throughput. As compared to CPUs and GPUs, the single-threaded TPU has none of the sophisticated microarchitectural features that consume transistors and energy to improve the average case but not the 99th-percentile case: no caches, branch prediction, out-of-order execution, multiprocessing, speculative prefetching, address coalescing, multithreading, context switching, and so forth. Minimalism is a virtue of domain-specific processors.
Bảng 3 cho thấy hiệu năng TPU, nhưng nó không tính đến thời gian của server host, thời gian này có thể được chia thành việc chạy phần ứng dụng trên host và việc giao tiếp với TPU. Bảng 5 liệt kê phần thứ hai, nhưng phần thứ nhất thì khó. Lý thuyết hàng đợi cho thấy các hàng đợi đầu vào dài làm tăng thông lượng, bằng cách đảm bảo rằng máy tính không bao giờ ở trạng thái nhàn rỗi, nhưng làm kéo dài thời gian đáp ứng. Vì vậy, hầu hết ứng dụng giữ cho các hàng đợi đầu vào của chúng trống. Tuy nhiên, chúng tôi không thể đo được khi nào TPU nhàn rỗi vì nó đang chờ CPU thực hiện phần ứng dụng của nó hoặc vì CPU cũng nhàn rỗi do hàng đợi đầu vào trống.
Table 3 shows TPU performance, but it doesn’t account for host server time, which can be divided into running the host share of the application and talking to the TPU. Table 5 lists the second part, but the first part is hard. Queueing theory shows that long input queues raise throughput—by ensuring that the computer is never idle—but stretch response time. Thus, most applications keep their input queues empty. Alas, we can’t measure when the TPU is idle since it is waiting for the CPU to do its portion of the application or because the CPU is also idle due to an empty input queue.
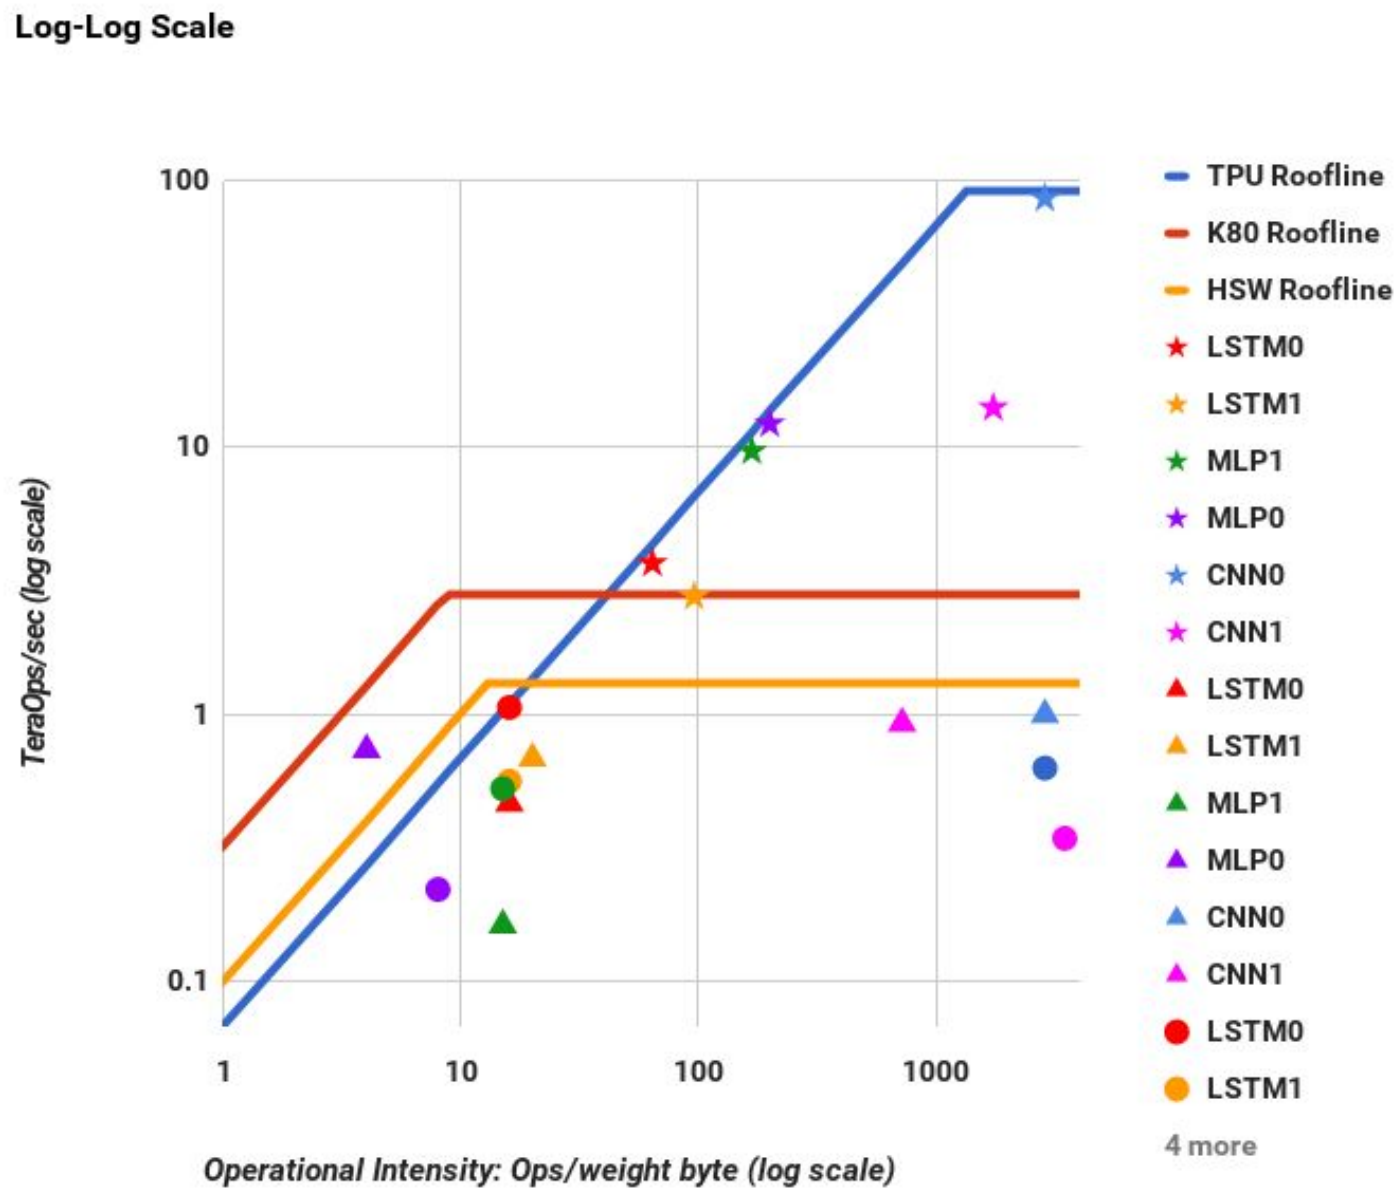
Bảng 6 đưa ra kết quả cuối cùng của hiệu năng suy luận tương đối trên mỗi die, bao gồm chi phí phụ trội của server host đối với hai bộ tăng tốc so với CPU. Cột áp chót cho thấy trung bình hình học của hiệu năng tương đối đối với sáu ứng dụng NN, cho thấy die K80 nhanh gấp 1.1X so với die Haswell, die TPU nhanh gấp 14.5 lần, và do đó die TPU nhanh gấp 13.2 lần so với die GPU. Hình 8 biểu diễn trực quan tốc độ tương đối của chúng.
Table 6 gives the bottom line of relative inference performance per die including the host server overhead for the two accelerators versus the CPU. The next-to-last column shows the geometric mean of the relative performance for the six NN applications, which suggests the K80 die is 1.1X the speed of a Haswell die, that the TPU die is 14.5 times as fast, and thus the TPU die is 13.2 times as fast as the GPU die. Figure 8 shows their relative speeds visually.
Hãy nhớ rằng các kiến trúc sư sử dụng trung bình hình học khi họ không biết tổ hợp chương trình thực tế sẽ được chạy [Hen18]. Tuy nhiên, đối với nghiên cứu này, chúng tôi biết tổ hợp đó (Bảng 1). Trung bình có trọng số trong cột cuối cùng của Bảng 6 sử dụng tổ hợp thực tế làm tăng GPU lên 1.9X và TPU lên 29.2X, vì vậy die TPU hiện nhanh gấp 15.3 lần so với die GPU.
Recall that architects use the geometric mean when they don’t know the actual mix of programs that will be run [Hen18]. For this study, however, we do know the mix (Table 1). The weighted mean in the last column of Table 6 using the actual mix increases the GPU to 1.9X and the TPU to 29.2X, so the TPU die is now 15.3 times as fast as the GPU die.
| Kiểu | Lô | Đáp ứng phân vị thứ 99 | Inf/s (IPS) | % Max IPS |
|---|---|---|---|---|
| CPU | 16 | 7.2 ms | 5,482 | 42% |
| CPU | 64 | 21.3 ms | 13,194 | 100% |
| GPU | 16 | 6.7 ms | 13,461 | 37% |
| GPU | 64 | 8.3 ms | 36,465 | 100% |
| TPU | 200 | 7.0 ms | 225,000 | 80% |
| TPU | 250 | 10.0 ms | 280,000 | 100% |
| Type | Batch | 99th% Response | Inf/s (IPS) | % Max IPS |
|---|---|---|---|---|
| CPU | 16 | 7.2 ms | 5,482 | 42% |
| CPU | 64 | 21.3 ms | 13,194 | 100% |
| GPU | 16 | 6.7 ms | 13,461 | 37% |
| GPU | 64 | 8.3 ms | 36,465 | 100% |
| TPU | 200 | 7.0 ms | 225,000 | 80% |
| TPU | 250 | 10.0 ms | 280,000 | 100% |
Bảng 4. Thời gian đáp ứng phân vị thứ 99 và thông lượng trên mỗi die (IPS) cho MLP0 khi kích thước lô thay đổi đối với MLP0. Độ trễ cho phép dài nhất là 7 ms. Đối với GPU và TPU, thông lượng MLP0 tối đa bị giới hạn bởi chi phí phụ trội của server host. Kích thước lô lớn hơn làm tăng thông lượng, nhưng như văn bản giải thích, thời gian đáp ứng dài hơn của chúng vượt quá giới hạn, vì vậy CPU và GPU phải sử dụng kích thước lô nhỏ hơn, kém hiệu quả hơn (16 so với 200).
Table 4. 99-th% response time and per die throughput (IPS) for MLP0 as batch size varies for MLP0. The longest allowable latency is 7 ms. For the GPU and TPU, the maximum MLP0 throughput is limited by the host server overhead. Larger batch sizes increase throughput, but as the text explains, their longer response times exceed the limit, so CPUs and GPUs must use less-efficient, smaller batch sizes (16 vs. 200).
| MLP0 | MLP1 | LSTM0 | LSTM1 | CNN0 | CNN1 |
|---|---|---|---|---|---|
| 21% | 76% | 11% | 20% | 51% | 14% |
| MLP0 | MLP1 | LSTM0 | LSTM1 | CNN0 | CNN1 |
|---|---|---|---|---|---|
| 21% | 76% | 11% | 20% | 51% | 14% |
Bảng 5. Thời gian để CPU host tương tác với TPU được biểu diễn dưới dạng phần trăm thời gian thực thi TPU (từ các bộ đếm hiệu năng TPU). Phần này là thời gian CPU và TPU giao tiếp qua bus PCIe, không bao gồm thời gian CPU thực hiện một phần của ứng dụng nhưng không tương tác với TPU. Như văn bản giải thích, TPU khó đo được liệu CPU đang nhàn rỗi hay đang làm việc trên ứng dụng.
Table 5. Time for host CPU to interact with the TPU expressed as percent of TPU execution time (from TPU performance counters). This fraction is the time the CPU and TPU are communicating over the PCIe bus, not including the time the CPU is doing a portion of the application but not interacting with the TPU. As the text explains, it’s hard for the TPU to measure if the CPU is idle or working on the app.
| Kiểu | MLP0 | MLP1 | LSTM0 | LSTM1 | CNN0 | CNN1 | GM | WM |
|---|---|---|---|---|---|---|---|---|
| GPU | 2.5 | 0.3 | 0.4 | 1.2 | 1.6 | 2.7 | 1.1 | 1.9 |
| TPU | 41.0 | 18.5 | 3.5 | 1.2 | 40.3 | 71.0 | 14.5 | 29.2 |
| Ratio | 16.7 | 60.0 | 8.0 | 1.0 | 25.4 | 26.3 | 13.2 | 15.3 |
| Type | MLP0 | MLP1 | LSTM0 | LSTM1 | CNN0 | CNN1 | GM | WM |
|---|---|---|---|---|---|---|---|---|
| GPU | 2.5 | 0.3 | 0.4 | 1.2 | 1.6 | 2.7 | 1.1 | 1.9 |
| TPU | 41.0 | 18.5 | 3.5 | 1.2 | 40.3 | 71.0 | 14.5 | 29.2 |
| Ratio | 16.7 | 60.0 | 8.0 | 1.0 | 25.4 | 26.3 | 13.2 | 15.3 |
Bảng 6. Hiệu năng die GPU K80 và die TPU tương đối so với CPU đối với tải công việc NN. GM và WM là trung bình hình học và trung bình có trọng số (sử dụng tổ hợp thực tế của sáu ứng dụng trong Bảng 1). Hiệu năng tương đối của GPU và TPU bao gồm chi phí phụ trội của server host. MLP và CNN hoạt động tốt trên TPU. Bảng 4 giải thích rằng TPU có thể có kích thước lô lớn hơn và vẫn đáp ứng các giới hạn thời gian, làm tăng số phép toán trên mỗi byte (Bảng 1) hoặc tương đương, giảm số lần truy cập bộ nhớ trên mỗi phép toán. Ngoài ra, CNN theo bản chất có khả năng tái sử dụng trọng số lớn hơn và do đó có số phép toán trên mỗi byte cao hơn. Vì vậy, băng thông bộ nhớ thấp hơn của TPU không làm giảm đáng kể hiệu năng CNN.
Table 6. K80 GPU die and TPU die performance relative to CPU for the NN workload. GM and WM are geometric and weighted mean (using the actual mix of the six apps in Table 1). Relative performance for the GPU and TPU includes host server overhead. MLPs and CNNs perform well on the TPU. Table 4 explains that the TPU can have larger batch sizes and still meet the time limits, increasing operations per byte (Table 1) or, equivalently, reducing memory accesses per operation. Also, CNNs by their nature have greater weight reuse and thus higher operations per byte. Thus, the lower memory bandwidth of the TPU doesn’t significantly hurt CNN performance.
5 Chi phí-Hiệu năng, TCO, và Hiệu năng/Watt
5 Cost-Performance, TCO, and Performance/Watt
Khi mua máy tính với số lượng hàng nghìn, chi phí-hiệu năng vượt trội hơn hiệu năng. Chỉ số chi phí tốt nhất trong một datacenter là tổng chi phí sở hữu (TCO). Giá thực tế mà chúng tôi trả cho hàng nghìn chip phụ thuộc vào các cuộc đàm phán giữa các công ty liên quan. Vì lý do kinh doanh, chúng tôi không thể công bố thông tin giá như vậy hoặc dữ liệu có thể cho phép suy ra chúng. Tuy nhiên, công suất có tương quan với TCO, và chúng tôi có thể công bố Watts trên mỗi server, vì vậy trong bài báo này chúng tôi sử dụng hiệu năng/Watt làm đại diện cho hiệu năng/TCO. Trong phần này, chúng tôi so sánh toàn bộ server thay vì các die đơn lẻ, như được liệt kê trong các cột “Benchmarked Server” của Table 2.
When buying computers by the thousands, cost-performance trumps performance. The best cost metric in a datacenter is total cost of ownership (TCO). The actual price we pay for thousands of chips depends on negotiations between the companies involved. For business reasons, we can’t publish such price information or data that might let them be deduced. However, power is correlated with TCO, and we can publish Watts per server, so we use performance/Watt as our proxy for performance/TCO in this paper. In this section, we compare whole servers rather than single dies, which Table 2 lists in the “Benchmarked Server” columns.
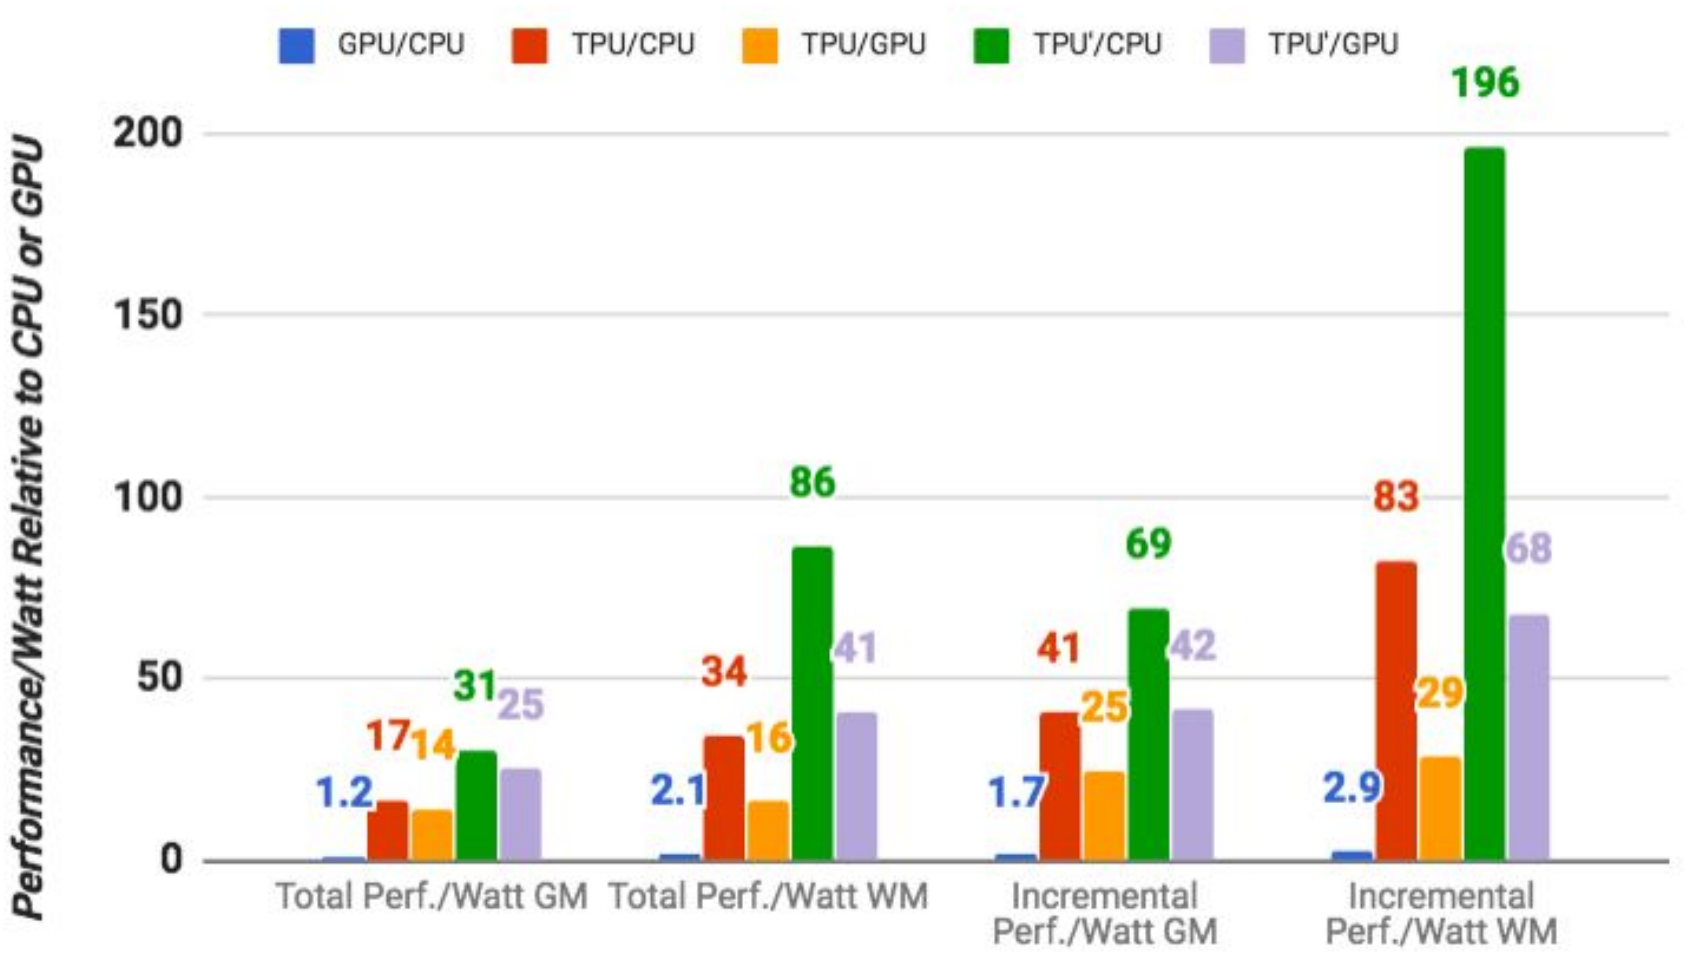
Figure 9 trình bày trung bình hình học và trung bình có trọng số của hiệu năng/Watt đối với GPU K80 và TPU so với CPU Haswell. Chúng tôi trình bày hai cách tính khác nhau của hiệu năng/Watt. Cách thứ nhất (“total”) bao gồm công suất được tiêu thụ bởi server CPU máy chủ khi tính hiệu năng/Watt cho GPU và TPU. Cách thứ hai (“incremental”) trừ công suất của server CPU máy chủ khỏi GPU và TPU trước đó.
Figure 9 shows the geometric and weighted mean performance/Watt for the K80 GPU and TPU relative to the Haswell CPU. We present two different calculations of performance/Watt. The first (“total”) includes the power consumed by the host CPU server when calculating performance/Watt for the GPU and TPU. The second (“incremental”) subtracts the host CPU server power from the GPU and TPU beforehand.
Đối với total-performance/Watt, server K80 đạt 1.2 - 2.1X Haswell. Đối với incremental-performance/Watt, khi bỏ qua công suất của server Haswell, server K80 đạt 1.7- 2.9X.
For total-performance/Watt, the K80 server is 1.2 - 2.1X Haswell. For incremental-performance/Watt, when Haswell server power is omitted, the K80 server is 1.7- 2.9X.
Server TPU có total-performance/Watt tốt hơn Haswell từ 17 đến 34 lần, điều này khiến server TPU đạt hiệu năng/Watt bằng 14 đến 16 lần server K80. incremental-performance/Watt tương đối — là lý do biện minh của công ty chúng tôi cho một ASIC tùy chỉnh — là 41 đến 83 đối với TPU, giúp TPU đạt hiệu năng/Watt bằng 25 đến 29 lần GPU.
The TPU server has 17 to 34 times better total-performance/Watt than Haswell, which makes the TPU server 14 to 16 times the performance/Watt of the K80 server. The relative incremental-performance/Watt—which was our company’s justification for a custom ASIC—is 41 to 83 for the TPU, which lifts the TPU to 25 to 29 times the performance/Watt of the GPU.
6 Tính tỷ lệ thuận với năng lượng
6 Energy Proportionality
Thermal Design Power (TDP) ảnh hưởng đến chi phí cung cấp nguồn điện, vì cần cung cấp đủ điện năng và làm mát khi phần cứng hoạt động ở công suất tối đa. Tuy nhiên, chi phí điện năng dựa trên mức tiêu thụ trung bình khi tải công việc thay đổi trong ngày. [Bar07] nhận thấy rằng các server bận 100% trong chưa đến 10% thời gian và đề xuất tính tỷ lệ thuận với năng lượng: các server nên tiêu thụ công suất tỷ lệ thuận với lượng công việc được thực hiện. Ước tính công suất tiêu thụ trong phần trước dựa trên tỷ lệ của TDP đã được quan sát trong các datacenter của chúng tôi.
Thermal Design Power (TDP) affects the cost of provisioning power, as you must supply sufficient power and cooling when hardware is at full power. However, the cost of electricity is based on the average consumed as the workload varies during the day. [Bar07] found that servers are 100% busy less than 10% of the time and advocated energy proportionality: servers should consume power proportional to the amount of work performed. The estimate of power consumed in the prior section is based on the fraction of the TDP that has been seen in our datacenters.
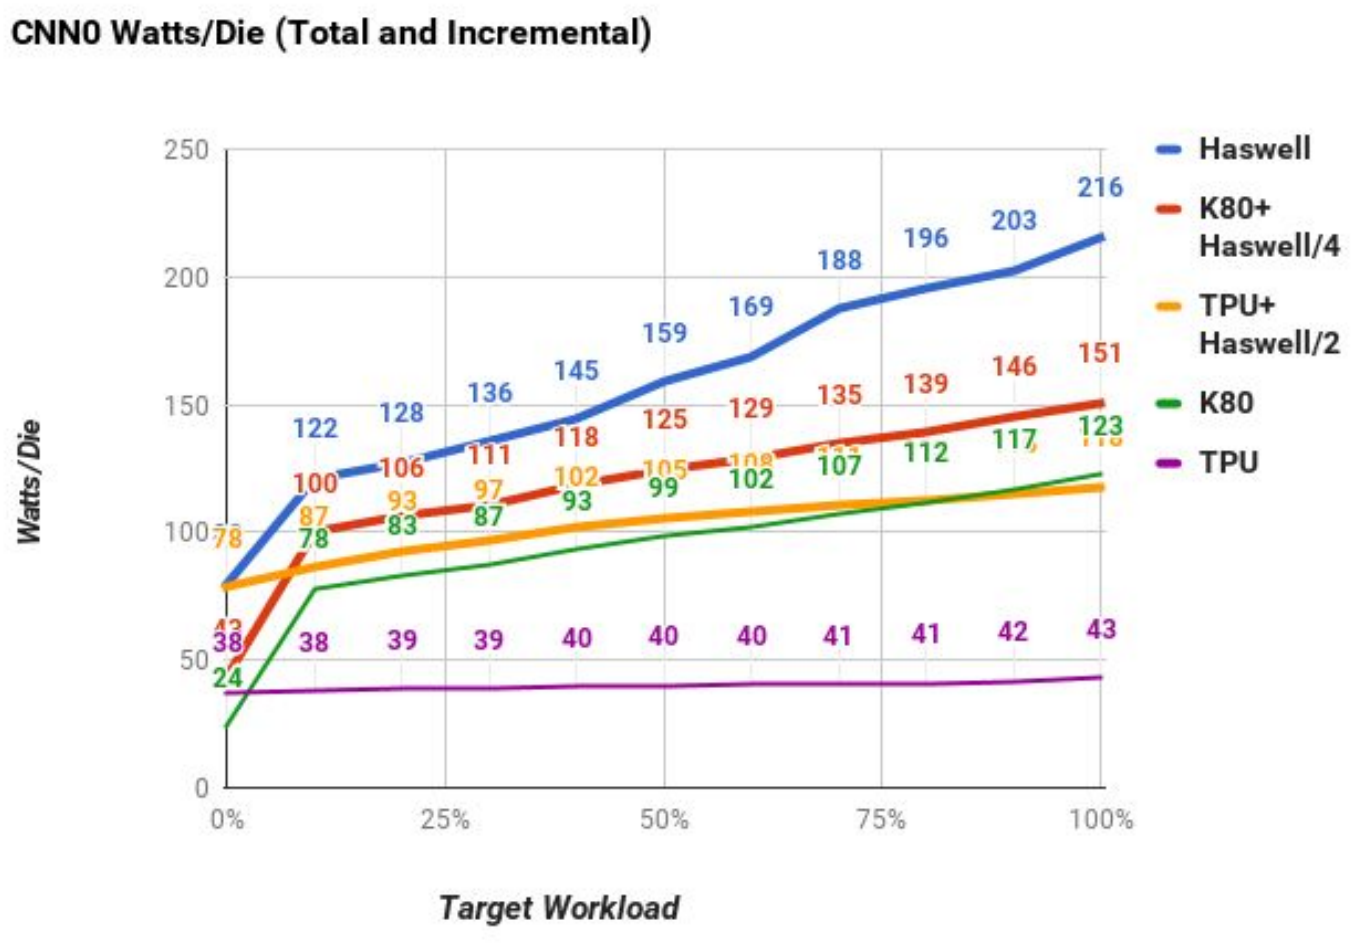
Chúng tôi đo hiệu năng và công suất khi mức sử dụng tải công việc được cung cấp thay đổi từ 0% đến 100%, được thu thập trong các nhóm với độ lệch tải công việc 10% [Lan09]. Hình 10 cho thấy công suất của server chia cho số die trên mỗi server đối với ba chip bằng cách thay đổi tải công việc của CNN0. Chúng tôi biểu diễn công suất tăng thêm (K80 và TPU) cũng như công suất tổng (K80+Haswell/4 và TPU+Haswell/2) cho GPU và TPU. Lưu ý rằng tất cả đều được cung cấp cùng kích thước lô.
We measured performance and power as the offered workload utilization varies from 0% to 100%, collected in buckets of 10% delta of workload [Lan09]. Figure 10 shows server power divided by the number of dies per server for the three chips by varying CNN0’s workload. We plot incremental (K80 and TPU) as well as total power (K80+Haswell/4 and TPU+Haswell/2) for the GPU and TPU. Note that all were given the same batch sizes.
Chúng tôi thấy rằng TPU có công suất thấp nhất—118W trên mỗi die cho tổng công suất (TPU+Haswell/2) và 40W trên mỗi die cho công suất tăng thêm (TPU trong Hình 10)—nhưng nó có tính tỷ lệ thuận với năng lượng kém: ở mức tải 10%, TPU sử dụng 88% công suất mà nó sử dụng ở mức 100%. (Lịch trình thiết kế ngắn đã ngăn việc đưa vào nhiều tính năng tiết kiệm năng lượng.) Không có gì đáng ngạc nhiên, Haswell có tính tỷ lệ thuận với năng lượng tốt nhất trong nhóm: nó sử dụng 56% công suất ở mức tải 10% so với khi ở mức 100%. K80 gần với CPU hơn TPU, sử dụng 66% công suất khi đầy tải ở mức tải công việc 10%. LSTM1, vốn không bị giới hạn bởi tính toán, hoạt động tương tự: ở mức tải 10%, CPU sử dụng 47% công suất đầy tải, GPU sử dụng 78%, và TPU sử dụng 94%.
We see that the TPU has the lowest power—118W per die total (TPU+Haswell/2) and 40W per die incremental (TPU in Fig. 10)—but it has poor energy proportionality: at 10% load, the TPU uses 88% of the power it uses at 100%. (The short design schedule prevented inclusion of many energy-saving features.) Not surprisingly, Haswell is the best at energy proportionality of the group: it uses 56% of the power at 10% load as it does at 100%. The K80 is closer to the CPU than the TPU, using 66% of the full load power at 10% workload. LSTM1, which is not computation bound, performs similarly: at 10% load the CPU uses 47% of full power, the GPU uses 78%, and the TPU uses 94%.
Điều gì xảy ra với mức sử dụng công suất của server khi chạy CNN0 nếu nó trở thành máy chủ cho các bộ tăng tốc? Khi GPU và TPU ở mức tải 100%, server CPU sử dụng 52% công suất đầy tải cho GPU và 69% cho TPU. (CPU thực hiện nhiều công việc hơn cho TPU vì nó đang chạy nhanh hơn GPU rất nhiều.) Do đó, server Haswell cùng với bốn TPU sử dụng <20% công suất bổ sung nhưng chạy CNN0 nhanh hơn 80 lần so với riêng server Haswell (4 TPU so với 2 CPU).
What happens to the server power usage when running CNN0 if it becomes a host to accelerators? When the GPU and TPU are at 100% load, the CPU server uses 52% of full power for the GPU and 69% for the TPU. (The CPU does more work for the TPU because it is running so much faster than the GPU.) Consequently, the Haswell server plus four TPUs use <20% additional power but run CNN0 80 times faster than the Haswell server alone (4 TPUs vs 2 CPUs).
7 Đánh giá các thiết kế TPU thay thế
7 Evaluation of Alternative TPU Designs
Giống như một FPU, bộ đồng xử lý TPU có kiến trúc vi mô (microarchitecture) tương đối dễ đánh giá, vì vậy chúng tôi đã tạo một mô hình hiệu năng (performance model) cho sáu ứng dụng của mình. Bảng 7 cho thấy sự khác biệt giữa các kết quả của mô hình và các bộ đếm hiệu năng phần cứng, với giá trị trung bình dưới 10%. Sau đó chúng tôi mô hình hóa hiệu năng khi thay đổi băng thông bộ nhớ, tần số xung nhịp và số lượng bộ tích lũy, cùng với kích thước của đơn vị nhân ma trận.
Like an FPU, the TPU coprocessor has a relatively easy microarchitecture to evaluate, so we created a performance model for our six applications. Table 7 shows the differences between the model results and the hardware performance counters, which average below 10%. We then modeled performance as we varied the memory bandwidth, the clock rate and number of accumulators, and the matrix multiply unit size.
Hình 11 cho thấy độ nhạy hiệu năng trung bình của khuôn TPU khi chúng tôi mở rộng các tham số này trong phạm vi từ 0.25x đến 4x. Hình này biểu diễn các giá trị trung bình có trọng số, nhưng các giá trị trung bình hình học trông tương tự. Ngoài việc đánh giá tác động của chỉ tăng tần số xung nhịp (clock trong Hình 11), chúng tôi cũng biểu diễn một thiết kế (clock+) trong đó tần số xung nhịp được tăng lên và số lượng bộ tích lũy được mở rộng tương ứng để trình biên dịch có thể giữ nhiều tham chiếu bộ nhớ hơn đang được xử lý. Tương tự, chúng tôi biểu diễn việc mở rộng đơn vị ma trận nếu tăng số lượng bộ tích lũy theo bình phương của mức tăng ở một chiều (matrix+), vì số lượng bộ nhân trong ma trận tăng theo cả hai chiều, cũng như chỉ tăng riêng đơn vị ma trận (matrix).
Figure 11 shows the mean performance sensitivity of TPU die as we scale these parameters over the range for 0.25x to 4x. It plots weighted means, but the geometric means look similar. In addition to evaluating the impact of only raising clock rates (clock in Figure 11), we also plot a design (clock+) where the clock rate is increased and the number of accumulators is correspondingly scaled so the compiler can keep more memory references in flight. Likewise, we plot matrix unit expansion if we increase the number of accumulators with the square of the rise in one dimension (matrix+), since the number of multipliers in the matrix grows in both dimensions, as well as just increasing the matrix unit alone (matrix).
| MLP0 | MLP1 | LSTM0 | LSTM1 | CNN0 | CNN1 |
|---|---|---|---|---|---|
| 6.8% | 10.9% | 7.7% | 5.4% | 8.2% | 11.2% |
| MLP0 | MLP1 | LSTM0 | LSTM1 | CNN0 | CNN1 |
|---|---|---|---|---|---|
| 6.8% | 10.9% | 7.7% | 5.4% | 8.2% | 11.2% |
Bảng 7. Sự khác biệt về số chu kỳ xung nhịp giữa các bộ đếm hiệu năng phần cứng TPU và mô hình hiệu năng TPU. Giá trị trung bình là 8%.
Table 7. Difference in clock cycles between the TPU hardware performance counters and the TPU performance model. The average is 8%.
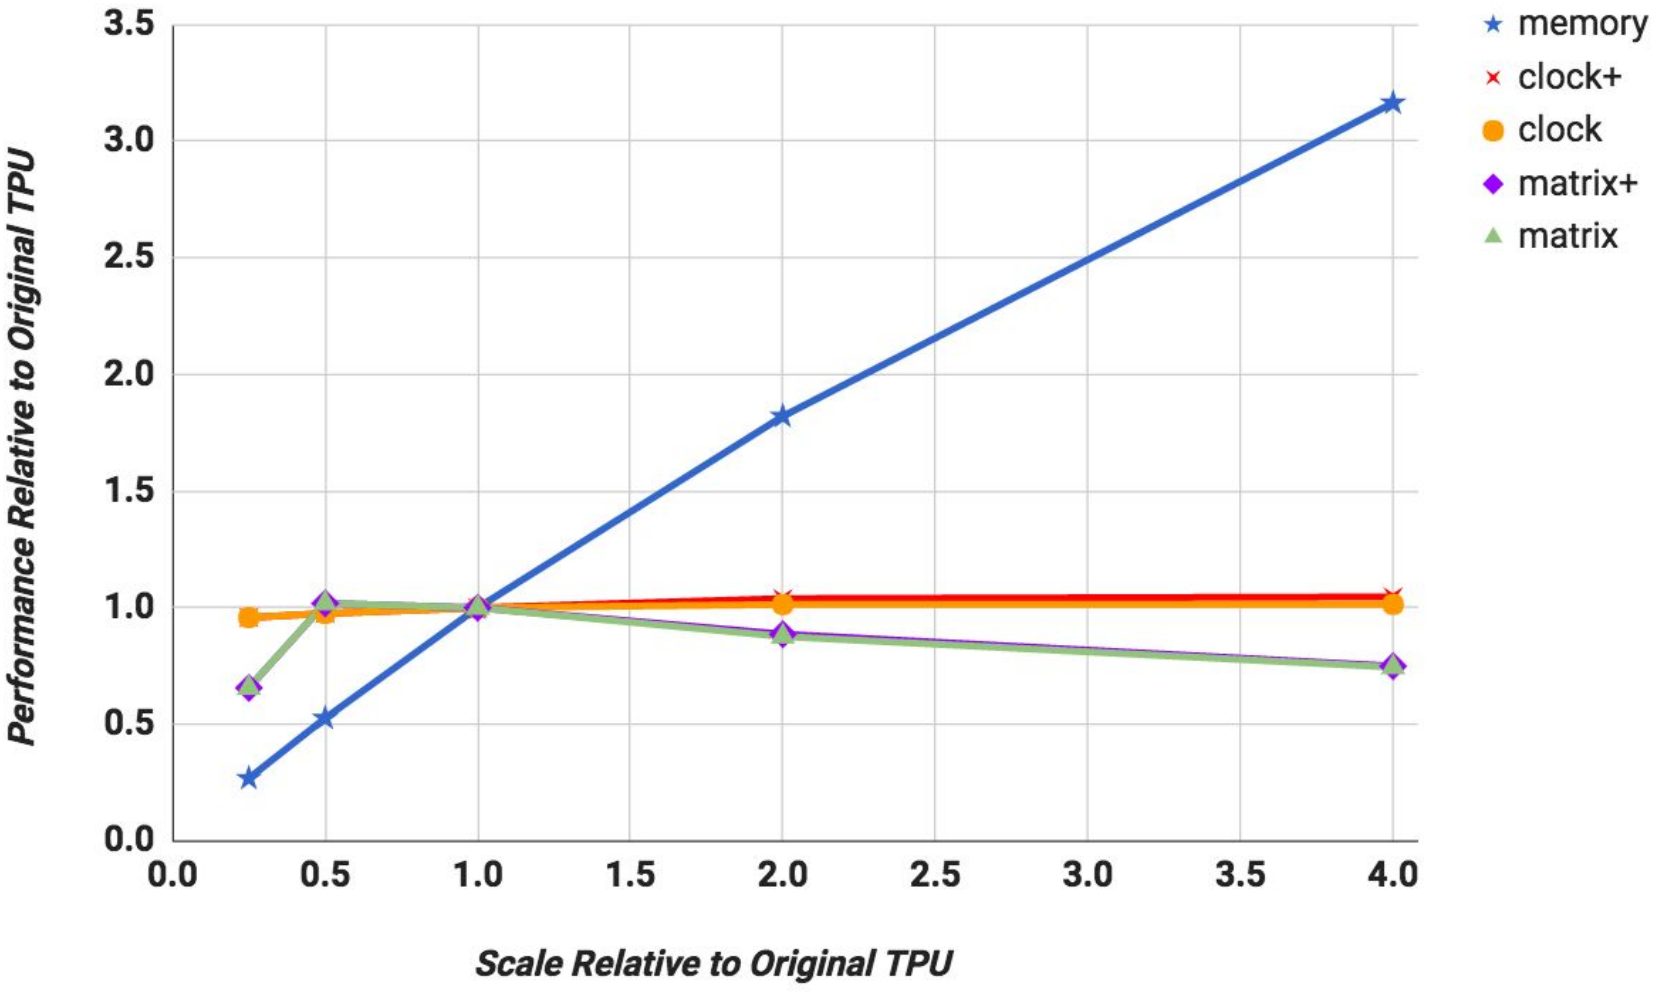
Thứ nhất, việc tăng băng thông bộ nhớ (memory) có tác động lớn nhất: hiệu năng cải thiện trung bình 3X khi bộ nhớ tăng 4X. Thứ hai, tần số xung nhịp có ít lợi ích trung bình dù có hay không có thêm bộ tích lũy. Lý do là MLP và LSTM bị giới hạn bởi bộ nhớ nhưng chỉ CNN bị giới hạn bởi tính toán. Mặc dù khó thấy trong Hình 11, vì hình này chỉ hiển thị giá trị trung bình có trọng số của cả sáu DNN, việc tăng tần số xung nhịp lên 4X hầu như không có tác động đến MLP và LSTM nhưng cải thiện hiệu năng của CNN khoảng 2X. Thứ ba, hiệu năng trung bình trong Hình 11 hơi giảm khi đơn vị ma trận mở rộng từ 256x256 lên 512x512 cho tất cả ứng dụng, bất kể chúng có nhận thêm bộ tích lũy hay không. Vấn đề này tương tự như phân mảnh nội bộ của các trang lớn, chỉ tệ hơn vì nó xảy ra trong hai chiều. Xét ma trận 600x600 được sử dụng trong LSTM1. Với một đơn vị ma trận 256x256, cần 9 bước để lát ma trận 600x600, tổng cộng mất 18 us thời gian. Đơn vị 512x512 lớn hơn chỉ cần bốn bước, nhưng mỗi bước mất thời gian dài gấp bốn lần, tổng cộng 32 us. Các lệnh CISC của chúng tôi dài, vì vậy giải mã không đáng kể và không che giấu được chi phí phụ trội của việc tải từ DRAM.
First, increasing memory bandwidth (memory) has the biggest impact: performance improves 3X on average when memory increases 4X. Second, clock rate has little benefit on average with or without more accumulators. The reason is the MLPs and LSTMs are memory bound but only the CNNs are compute bound. While hard to see in Figure 11, since it shows only the weighted mean of all six DNNs, increasing the clock rate by 4X has almost no impact on MLPs and LSTMs but improves performance of CNNs by about 2X. Third, the average performance in Figure 11 slightly degrades when the matrix unit expands from 256x256 to 512x512 for all apps, whether or not they get more accumulators. The issue is analogous to internal fragmentation of large pages, only worse since it’s in two dimensions. Consider the 600x600 matrix used in LSTM1. With a 256x256 matrix unit, it takes 9 steps to tile 600x600, for a total of 18 us of time. The larger 512x512 unit requires only four steps, but each step takes four times longer, for 32 us of time. Our CISC instructions are long, so decode is insignificant and does not hide the overhead of loading from the DRAM.
Bảng 8 cho thấy mức sử dụng của Unified Buffer 24 MiB, ban đầu được định kích thước để cho phép MLP chạy với kích thước lô lên đến 2048. Gần đây chúng tôi đã cải thiện bộ cấp phát lưu trữ cho Unified Buffer, giúp giảm bộ nhớ cần thiết cho ứng dụng lớn nhất trong sáu ứng dụng xuống còn 14 MiB. Trong 18 tháng đầu tiên triển khai, TPU sử dụng toàn bộ dung lượng của nó trong khi bộ cấp phát mới được phát triển. Hiện nay dung lượng bổ sung tạo ra khoảng dự phòng cho việc áp dụng các mô hình lớn hơn.
Table 8 shows the utilization of the 24 MiB Unified Buffer, which was initially sized to allow MLPs to run at batch sizes up to 2048. We recently improved the storage allocator for the Unified Buffer, which reduces the memory needed for the largest of the six applications to 14 MiB. For the first 18 months of deployment, the TPU used its full capacity while the new allocator was being developed. Now the extra capacity adds margin for adopting bigger models.
Tiếp theo chúng tôi sử dụng mô hình hiệu năng để đánh giá một khuôn TPU giả định (TPU') có thể đã được thiết kế trong cùng công nghệ quy trình nếu chúng tôi có hơn 15 tháng. Việc tổng hợp logic và thiết kế khối tích cực hơn có thể đã tăng tần số xung nhịp lên 50%. Thiết kế một mạch giao diện cho bộ nhớ GDDR5, như trong K80, sẽ cải thiện băng thông Weight Memory hơn năm lần, dịch chuyển điểm gờ roofline của nó từ 1350 xuống 250. Như Hình 11 cho thấy, tăng tần số xung nhịp lên 1050 MHz nhưng không hỗ trợ bộ nhớ hầu như không tạo ra thay đổi. Nếu chúng tôi giữ xung nhịp ở 700 MHz nhưng sử dụng GDDR5 cho Weight Memory, mức tăng trung bình hình học tăng lên 2.6 đầy ấn tượng và trung bình có trọng số tăng lên 3.9. Thực hiện cả hai việc làm tăng trung bình hình học (2.9) nhưng không tăng trung bình có trọng số, vì vậy TPU’ chỉ có bộ nhớ nhanh hơn.
We next used the performance model to evaluate a hypothetical TPU die (TPU') that might have been designed in the same process technology if we had more than 15 months. More aggressive logic synthesis and block design might have increased the clock rate by 50%. Designing an interface circuit for GDDR5 memory, as in the K80, would improve Weight Memory bandwidth by more than a factor of five, shifting its roofline ridge point from 1350 to 250. As Figure 11 shows, increasing clock rate to 1050 MHz but not helping memory makes almost no change. If we left the clock at 700 MHz but used GDDR5 for Weight Memory, the geometric mean increase jumps to an impressive 2.6 and the weighted mean to 3.9. Doing both raises the geometric mean (2.9) but not the weighted mean, so TPU’ just has faster memory.
Hình 11 không bao gồm thời gian của server máy chủ. Chúng tôi sử dụng Bảng 5 để tính toán thời gian cho chi phí phụ trội tương tác với server máy chủ của TPU. Việc thêm cùng khoảng thời gian bổ sung đó làm giảm các giá trị trung bình của TPU’ từ 2.6 xuống 1.9 và từ 3.9 xuống 3.2. Thay đổi này vừa lạc quan, vì nó không bao gồm thời gian CPU để chạy phần ứng dụng của nó, vừa bi quan, vì chúng tôi có khả năng sẽ tinh chỉnh mạnh mã máy chủ khi có một TPU’ nhanh hơn 3X.
Figure 11 does not include host server time. We used Table 5 to calculate time for the host server interaction overhead for the TPU. Adding that same extra time drops TPU’ means from 2.6 to 1.9 and 3.9 to 3.2. This change is both optimistic, since it doesn’t include CPU time to run its share of the app, and pessimistic, as we likely would aggressively tune the host code given a 3X faster TPU’.
Thay thế chỉ Weight Memory DDR3 bằng bộ nhớ GDDR5 tương đương yêu cầu tăng gấp đôi số kênh bộ nhớ lên bốn. Cải tiến này sẽ mở rộng kích thước khuôn khoảng 10%. Tuy nhiên, băng thông bộ nhớ cao hơn làm giảm áp lực lên Unified Buffer, vì vậy việc giảm Unified Buffer xuống 14 MiB có thể lấy lại 10% diện tích. GDDR5 cũng sẽ tăng ngân sách công suất hệ thống TPU từ 861 Watts lên khoảng 900 Watts, vì có 4 TPU trên mỗi server.
Replacing just the DDR3 Weight Memory with the equivalent GDDR5 memory requires doubling the number of memory channels to four. This improvement would expand die size by about 10%. However, higher memory bandwidth reduces pressure on the Unified Buffer, so reducing the Unified Buffer to 14 MiB could gain back 10% in area. GDDR5 would also increase the TPU system power budget from 861 Watts to about 900 Watts, as there are 4 TPUs per server.
Hình 9 ở trên cho thấy hiệu năng tổng thể/Watt/khuôn tương đối của TPU’ tăng vọt lên 31X - 86X so với Haswell và 25X - 41X so với K80. Chỉ số gia tăng tăng vọt lên mức đáng kinh ngạc 69X - 196X so với Haswell và 42X - 68X so với K80.
Figure 9 above shows the relative total-performance/Watt/die of TPU’ leaps to 31X - 86X over Haswell and 25X - 41X over the K80. The incremental metric soars to an amazing 69X - 196X over Haswell and 42X - 68X over the K80.
| MLP0 | MLP1 | LSTM0 | LSTM1 | CNN0 | CNN1 |
|---|---|---|---|---|---|
| 11.0 | 2.3 | 4.8 | 4.5 | 1.5 | 13.9 |
| MLP0 | MLP1 | LSTM0 | LSTM1 | CNN0 | CNN1 |
|---|---|---|---|---|---|
| 11.0 | 2.3 | 4.8 | 4.5 | 1.5 | 13.9 |
Bảng 8. MiB tối đa của Unified Buffer 24 MiB được sử dụng cho mỗi ứng dụng NN. Một Unified Buffer 14 MiB là đủ cho các ứng dụng này.
Table 8. Maximum MiB of the 24 MiB Unified Buffer used per NN app. A 14 MiB Unified Buffer is sufficient for these apps.
8 Thảo luận
8 Discussion
Phần này tuân theo kiểu bác bỏ của [Hen18] đối với các ngụy biện và cạm bẫy. • Ngụy biện: Các ứng dụng suy luận NN trong các datacenter coi trọng thông lượng ngang với thời gian phản hồi. Chúng tôi rất ngạc nhiên khi các nhà phát triển của mình có những yêu cầu mạnh mẽ về thời gian phản hồi, vì một số người đã đề xuất vào năm 2014 rằng kích thước lô sẽ đủ lớn để TPU đạt hiệu năng cực đại hoặc rằng các yêu cầu về độ trễ sẽ không quá chặt chẽ. Một ứng dụng thúc đẩy là xử lý ảnh ngoại tuyến, và trực giác là nếu các dịch vụ tương tác cũng muốn sử dụng TPU, hầu hết chúng sẽ chỉ tích lũy các lô lớn hơn. Ngay cả các nhà phát triển của một ứng dụng vào năm 2014 quan tâm đến thời gian phản hồi (LSTM1) cũng nói rằng giới hạn là 10 ms vào năm 2014, nhưng đã giảm xuống còn 7 ms khi họ thực sự chuyển nó sang TPU. Mong muốn bất ngờ đối với TPU của nhiều dịch vụ như vậy kết hợp với tác động và sự ưu tiên dành cho thời gian phản hồi thấp đã thay đổi phương trình, với các nhà viết ứng dụng thường chọn giảm độ trễ thay vì chờ tích lũy các lô lớn hơn. May mắn thay, TPU có một mô hình thực thi đơn giản và có thể lặp lại để giúp đáp ứng các mục tiêu về thời gian phản hồi của các dịch vụ tương tác và có thông lượng cực đại cao đến mức ngay cả các kích thước lô nhỏ cũng tạo ra hiệu năng cao hơn các CPU và GPU đương thời. • Ngụy biện: Kiến trúc GPU K80 là sự phù hợp tốt cho suy luận NN. GPU theo truyền thống được xem là các kiến trúc có thông lượng cao dựa vào DRAM băng thông cao và hàng nghìn luồng để đạt được mục tiêu của chúng. Góc nhìn này giúp giải thích tại sao K80 chỉ nhanh hơn một chút khi suy luận so với Haswell và chậm hơn nhiều so với TPU. Các thế hệ kế nhiệm của K80 chắc chắn sẽ bao gồm các tối ưu hóa để cải thiện hiệu năng suy luận cực đại, nhưng do cách tiếp cận kiến trúc hướng tới thông lượng của chúng, việc GPU đáp ứng các giới hạn độ trễ nghiêm ngặt có thể khó khăn hơn. Và như Section 7 chỉ ra, vẫn còn nhiều dư địa để cải thiện TPU, vì vậy đây không phải là một mục tiêu dễ dàng.
This section follows the fallacy and pitfall with rebuttal style of [Hen18]. • Fallacy: NN inference applications in datacenters value throughput as much as response time. We were surprised that our developers had strong response-time demands, as some suggested in 2014 that batch sizes would be large enough for the TPU to reach peak performance or that latency requirements wouldn’t be as tight. One driving application was off-line image processing, and the intuition was that if interactive services also wanted TPUs, most of them would just accumulate larger batches. Even the developers of one application in 2014 that cared about response time (LSTM1) said the limit was 10 ms in 2014, but shrank it to 7 ms when they actually ported it to the TPU. The unexpected desire for TPUs by many such services combined with the impact on and preference for low response time changed the equation, with application writers often opting for reduced latency over waiting for bigger batches to accumulate. Fortunately, the TPU has a simple and repeatable execution model to help meet the response-time targets of interactive services and such high peak throughput that even small batch sizes result in higher performance than contemporary CPUs and GPUs. • Fallacy: The K80 GPU architecture is a good match to NN inference. GPUs have traditionally been seen as high-throughput architectures that rely on high-bandwidth DRAM and thousands of threads to achieve their goals. This perspective helps explain why the K80 is only a little faster at inference than Haswell and much slower than the TPU. Successors to the K80 will surely include optimizations to improve peak inference performance, but given their throughput-oriented architectural approach, it may be more challenging for GPUs to meet the strict latency limits. And as Section 7 shows, there is plenty of headroom to improve the TPU, so it’s not an easy target.
• Cạm bẫy: Các kiến trúc sư đã bỏ qua các tác vụ NN quan trọng. Chúng tôi hài lòng với sự chú ý mà cộng đồng kiến trúc đang dành cho NN: 15% các bài báo tại ISCA 2016 nói về các bộ tăng tốc phần cứng cho NN [Alb16] [Che16a][Chi16][Han16][Kim16][LiK16][Liu16][Rea16] [Sha16]! Tuy nhiên, cả chín bài báo đều xem xét CNN, và chỉ hai bài đề cập đến các NN khác. CNN phức tạp hơn MLP và nổi bật trong các cuộc thi NN [Rus15], điều này có thể giải thích sức hấp dẫn của chúng, nhưng chúng chỉ chiếm khoảng 5% tải công việc NN trong datacenter của chúng tôi. Mặc dù CNN có thể phổ biến trong các thiết bị biên, khối lượng các mô hình tích chập vẫn chưa bắt kịp MLP và LSTM trong datacenter. Chúng tôi hy vọng các kiến trúc sư sẽ cố gắng tăng tốc MLP và LSTM với ít nhất sự nhiệt tình tương đương. • Cạm bẫy: Đối với phần cứng NN, Inferences Per Second (IPS) là một chỉ số hiệu năng tổng hợp không chính xác. Kết quả của chúng tôi cho thấy IPS là một bản tóm tắt hiệu năng tổng thể kém cho phần cứng NN, vì nó đơn giản là nghịch đảo của độ phức tạp của suy luận điển hình trong ứng dụng (ví dụ: số lượng, kích thước và kiểu của các lớp NN). Ví dụ, TPU chạy MLP1 4 lớp ở 360,000 IPS nhưng CNN1 89 lớp chỉ ở 4,700 IPS, vì vậy IPS của TPU thay đổi 75X! Do đó, việc sử dụng IPS làm chỉ số tốc độ duy nhất là gây hiểu lầm nhiều hơn nữa đối với các bộ tăng tốc NN so với việc MIPS hoặc FLOPS là đối với các bộ xử lý thông thường [Hen18], vì vậy IPS thậm chí còn nên bị xem nhẹ hơn. Để so sánh các máy NN tốt hơn, chúng ta cần một bộ phép đo chuẩn được viết ở mức cao để chuyển nó sang nhiều kiến trúc NN khác nhau. Fathom là một nỗ lực mới đầy hứa hẹn cho một bộ phép đo chuẩn như vậy [Ado16]. • Ngụy biện: Kết quả GPU K80 sẽ tốt hơn nhiều nếu bật chế độ Boost. Bỏ qua tác động tiêu cực của chế độ Boost của K80 lên TCO (Section 3), chúng tôi đã đo nó trên LSTM1. Chế độ Boost tăng tốc độ xung nhịp lên hệ số tối đa 1.6—từ 560 đến 875 MHz—làm tăng hiệu năng 1.4X, nhưng nó cũng tăng công suất lên 1.3X. Mức tăng ròng về hiệu năng/Watt là 1.1X, và do đó đối với LSTM1, chế độ boost sẽ có tác động nhỏ đến phân tích tốc độ năng lượng của chúng tôi. • Ngụy biện: Kết quả CPU và GPU sẽ tương đương với TPU nếu chúng ta sử dụng chúng hiệu quả hơn hoặc so sánh với các phiên bản mới hơn. Ban đầu chúng tôi có kết quả 8-bit chỉ cho một DNN trên CPU, do lượng công việc đáng kể cần thiết để sử dụng hỗ trợ số nguyên AVX2 một cách hiệu quả. Lợi ích là ~3.5X. Việc trình bày tất cả kết quả CPU ở dạng dấu phẩy động ít gây nhầm lẫn hơn (và tốn ít không gian hơn), thay vì có một ngoại lệ với roofline riêng của nó. Nếu tất cả DNN có mức tăng tốc tương tự, tỷ lệ hiệu năng/Watt sẽ giảm từ 41-83X xuống 12-24X. GPU datacenter P40 mới 16-nm, 1.5GHz, 250W có thể thực hiện 47 Tera 8-bit ops/sec, nhưng không có sẵn vào đầu năm 2015, nên không cùng thời với ba nền tảng của chúng tôi. Chúng tôi cũng không thể biết phần tỷ lệ của đỉnh P40 được cung cấp trong các giới hạn thời gian cứng nhắc của mình. Nếu chúng tôi so sánh các chip mới hơn, Section 7 cho thấy chúng tôi có thể tăng gấp ba hiệu năng của TPU 28-nm, 0.7GHz, 40W chỉ bằng cách sử dụng bộ nhớ GDDR5 của K80 (với chi phí thêm 10W). • Cạm bẫy: Các bộ đếm hiệu năng được thêm vào như một ý nghĩ sau đối với phần cứng NN. TPU có 106 bộ đếm hiệu năng, và nếu có điều gì thì chúng tôi muốn có thêm một vài bộ nữa (xem Table 3). Lý do tồn tại của các bộ tăng tốc NN là hiệu năng, và còn quá sớm trong quá trình phát triển của chúng để có trực giác tốt về những gì đang diễn ra. • Ngụy biện: Sau hai năm tinh chỉnh phần mềm, con đường duy nhất còn lại để tăng hiệu năng TPU là nâng cấp phần cứng. Hiệu năng của CNN1 trên TPU có thể được cải thiện nếu các nhà phát triển và người viết trình biên dịch làm nhiều công việc hơn để ghép CNN1 với phần cứng TPU. Ví dụ, các nhà phát triển có thể tổ chức lại các ứng dụng để tổng hợp nhiều lô ngắn từ các lớp tích chập thành một lô đơn, sâu hơn (từ 32 đến 128) cho bốn lớp kết nối đầy đủ. Một lớp đơn như vậy sẽ cải thiện mức sử dụng của đơn vị ma trận (Table 3). Vì CNN1 hiện chạy nhanh hơn CPU hơn 70 lần trên TPU, các nhà phát triển CNN1 đã rất hài lòng, vì vậy không rõ liệu hoặc khi nào các tối ưu hóa như vậy sẽ được thực hiện.
• Pitfall: Architects have neglected important NN tasks. We are pleased by the attention that the architecture community is paying to NN: 15% of the papers at ISCA 2016 were on hardware accelerators for NN [Alb16] [Che16a][Chi16][Han16][Kim16][LiK16][Liu16][Rea16] [Sha16]! Alas, all nine papers looked at CNNs, and only two mentioned other NNs. CNNs are more complex than MLPs and prominent in NN competitions [Rus15], which might explain their allure, but they are only about 5% of our datacenter NN workload. While CNNs may be common in edge devices, the volume of convolutional models hasn’t yet caught up with MLPs and LSTMs in the datacenter. We hope that architects try to accelerate MLPs and LSTMs with at least as much gusto. • Pitfall: For NN hardware, Inferences Per Second (IPS) is an inaccurate summary performance metric. Our results show that IPS is a poor overall performance summary for NN hardware, as it’s simply the inverse of the complexity of the typical inference in the application (e.g., the number, size, and type of NN layers). For example, the TPU runs the 4-layer MLP1 at 360,000 IPS but the 89-layer CNN1 at only 4,700 IPS, so TPU IPS vary by 75X! Thus, using IPS as the single-speed summary is even more misleading for NN accelerators than MIPS or FLOPS are for regular processors [Hen18], so IPS should be even more disparaged. To compare NN machines better, we need a benchmark suite written at a high-level to port it to the wide variety of NN architectures. Fathom is a promising new attempt at such a benchmark suite [Ado16]. • Fallacy: The K80 GPU results would be much better if Boost mode were enabled. Setting aside the negative impact of K80 Boost mode on TCO (Section 3), we measured it on LSTM1. Boost mode increased the clock rate by a factor of up to 1.6—from 560 to 875 MHz—which increased performance by 1.4X, but it also raised power by 1.3X. The net gain in performance/Watt is 1.1X, and thus for LSTM1, boost mode would have a minor impact on our energy-speed analysis. • Fallacy: CPU and GPU results would be comparable to the TPU if we used them more efficiently or compared to newer versions. We originally had 8-bit results for just one DNN on the CPU, due to the significant work to use AVX2 integer support efficiently. The benefit was ~3.5X. It was less confusing (and less space) to present all CPU results in floating point, rather than having one exception, with its own roofline. If all DNNs had similar speedup, performance/Watt ratio would drop from 41-83X to 12-24X. The new 16-nm, 1.5GHz, 250W P40 datacenter GPU can perform 47 Tera 8-bit ops/sec, but was unavailable in early 2015, so isn’t contemporary with our three platforms. We also can’t know the fraction of P40 peak delivered within our rigid time bounds. If we compared newer chips, Section 7 shows that we could triple performance of the 28-nm, 0.7GHz, 40W TPU just by using the K80’s GDDR5 memory (at a cost of an additional 10W). • Pitfall: Performance counters added as an afterthought for NN hardware. The TPU has 106 performance counters, and if anything we would like a few more (see Table 3). The raison d'etre for NN accelerators is performance, and it is way too early in their evolution to have good intuition about what is going on. • Fallacy: After two years of software tuning, the only path left to increase TPU performance is hardware upgrades. The performance of CNN1 on the TPU could improve if developers and compiler writers did more work to match CNN1 to the TPU hardware. For example, developers could reorganize the applications to aggregate multiple short batches out of the convolution layers into a single, deeper batch (from 32 to 128) for the four fully connected layers. Such a single layer would improve utilization of the matrix unit (Table 3). As CNN1 currently runs more than 70 times faster on the TPU than the CPU, the CNN1 developers are already very happy, so it’s not clear whether or when such optimizations would be performed.
9 Công trình liên quan
9 Related Work
Hai bài báo khảo sát ghi nhận rằng các ASIC NN tùy chỉnh đã xuất hiện từ ít nhất 25 năm trước [Ien96][Asa02]. Ví dụ, các chip CNAPS chứa một mảng SIMD 64 phần tử gồm các bộ nhân 16-bit với 8-bit, và một số chip CNAPS có thể được kết nối với nhau bằng một bộ tuần tự [Ham90]. Hệ thống Synapse-1 dựa trên một chip nhân-tích lũy dạng tâm thu tùy chỉnh có tên MA-16, thực hiện mười sáu phép nhân 16-bit cùng một lúc [Ram91]. Hệ thống ghép nối nhiều chip MA-16 với nhau và có phần cứng tùy chỉnh để thực hiện các hàm kích hoạt.
Two survey articles document that custom NN ASICs go back at least 25 years [Ien96][Asa02]. For example, CNAPS chips contained a 64 SIMD array of 16-bit by 8-bit multipliers, and several CNAPS chips could be connected together with a sequencer [Ham90]. The Synapse-1 system was based on a custom systolic multiply-accumulate chip called the MA-16, which performed sixteen 16-bit multiplies at a time [Ram91]. The system concatenated several MA-16 chips together and had custom hardware to do activation functions.
Hai mươi lăm máy trạm SPERT-II, được tăng tốc bởi ASIC tùy chỉnh T0, đã được triển khai bắt đầu từ năm 1995 để thực hiện cả huấn luyện NN và suy luận cho nhận dạng tiếng nói [Asa98]. T0 40-Mhz đã bổ sung các lệnh vectơ vào kiến trúc tập lệnh MIPS. Đơn vị vectơ tám làn có thể tạo ra tối đa mười sáu kết quả số học 32-bit mỗi chu kỳ xung nhịp dựa trên các đầu vào 8-bit và 16-bit, khiến nó nhanh hơn 25 lần trong suy luận và nhanh hơn 20 lần trong huấn luyện so với một máy trạm SPARC-20. Họ nhận thấy rằng 16 bit không đủ cho huấn luyện, vì vậy họ sử dụng hai từ 16-bit thay thế, làm tăng gấp đôi thời gian huấn luyện. Để khắc phục nhược điểm đó, họ đưa vào các “bunches” (batches) gồm 32 đến 1000 tập dữ liệu để giảm thời gian dành cho việc cập nhật trọng số, giúp nó nhanh hơn so với huấn luyện bằng một từ nhưng không có batches.
Twenty-five SPERT-II workstations, accelerated by the T0 custom ASIC, were deployed starting in 1995 to do both NN training and inference for speech recognition [Asa98]. The 40-Mhz T0 added vector instructions to the MIPS instruction set architecture. The eight-lane vector unit could produce up to sixteen 32-bit arithmetic results per clock cycle based on 8-bit and 16-bit inputs, making it 25 times faster at inference and 20 times faster at training than a SPARC-20 workstation. They found that 16 bits were insufficient for training, so they used two 16-bit words instead, which doubled training time. To overcome that drawback, they introduced “bunches” (batches) of 32 to 1000 data sets to reduce time spent updating weights, which made it faster than training with one word but no batches.
Họ kiến trúc NN DianNao gần đây hơn giảm thiểu các truy cập bộ nhớ cả trên chip và tới DRAM bên ngoài bằng cách có hỗ trợ kiến trúc hiệu quả cho các mẫu truy cập bộ nhớ xuất hiện trong các ứng dụng NN [Keu16]
The more recent DianNao family of NN architectures minimizes memory accesses both on the chip and to external DRAM by having efficient architectural support for the memory access patterns that appear in NN applications [Keu16]
[Che16a]. Tất cả đều sử dụng các phép toán số nguyên 16-bit và tất cả các thiết kế đều đi sâu đến mức bố trí, nhưng không có chip nào được chế tạo. DianNao ban đầu sử dụng một mảng gồm 64 đơn vị nhân-tích lũy số nguyên 16-bit với 44 KB bộ nhớ trên chip và được ước tính có kích thước 3 mm² (65 nm), chạy ở 1 GHz, và tiêu thụ 0.5W [Che14a]. Phần lớn năng lượng này dành cho các truy cập DRAM tới các trọng số, vì vậy một phiên bản kế nhiệm DaDianNao ("big computer") bao gồm eDRAM để giữ 36 MiB trọng số trên chip [Che14b]. Mục tiêu là có đủ bộ nhớ trong một hệ thống nhiều chip để tránh các truy cập DRAM bên ngoài. PuDianNao kế nhiệm ("general computer") hướng tới các thuật toán học máy truyền thống hơn ngoài DNN, chẳng hạn như máy vectơ hỗ trợ [Liu15]. Một nhánh khác là ShiDianNao ("vision computer") hướng tới CNN, tránh các truy cập DRAM bằng cách kết nối bộ tăng tốc trực tiếp với cảm biến [Du15].
[Che16a]. All use 16-bit integer operations and all designs dove down to layout, but no chips were fabricated. The original DianNao uses an array of 64 16-bit integer multiply-accumulate units with 44 KB of on-chip memory and is estimated to be 3 mm² (65 nm), to run at 1 GHz, and to consume 0.5W [Che14a]. Most of this energy went to DRAM accesses for weights, so one successor DaDianNao ("big computer") includes eDRAM to keep 36 MiB of weights on chip [Che14b]. The goal was to have enough memory in a multichip system to avoid external DRAM accesses. The follow-on PuDianNao ("general computer") is aimed at more traditional machine learning algorithms beyond DNNs, such as support vector machines [Liu15]. Another offshoot is ShiDianNao ("vision computer") aimed at CNNs, which avoids DRAM accesses by connecting the accelerator directly to the sensor [Du15].
Convolution Engine cũng tập trung vào CNN cho xử lý ảnh [Qad13]. Thiết kế này triển khai 64 đơn vị nhân-tích lũy 10-bit và tùy chỉnh một bộ xử lý Tensilica được ước tính chạy ở 800 MHz trong 45 nm. Nó được dự đoán có hiệu quả năng lượng-diện tích cao hơn từ 8X đến 15X so với một bộ xử lý SIMD, và nằm trong khoảng từ 2X đến 3X so với phần cứng tùy chỉnh chỉ được thiết kế cho một kernel cụ thể.
The Convolution Engine is also focused on CNNs for image processing [Qad13]. This design deploys 64 10-bit multiply-accumulator units and customizes a Tensilica processor estimated to run at 800 MHz in 45 nm. It is projected to be 8X to 15X more energy-area efficient than an SIMD processor, and within 2X to 3X of custom hardware designed just for a specific kernel.
Bài báo phép đo chuẩn Fathom dường như báo cáo các kết quả trái ngược với chúng tôi, với GPU thực hiện suy luận nhanh hơn nhiều so với CPU [Ado16]. Tuy nhiên, CPU và GPU của họ không thuộc lớp server, CPU chỉ có bốn lõi, các ứng dụng không sử dụng các lệnh AVX của CPU, và không có giới hạn thời gian đáp ứng (xem Table 4) [Bro16].
The Fathom benchmark paper seemingly reports results contradictory to ours, with the GPU running inference much faster than the CPU [Ado16]. However, their CPU and GPU are not server-class, the CPU has only four cores, the applications do not use the CPU’s AVX instructions, and there is no response-time cutoff (see Table 4) [Bro16].
Catapult là ví dụ được triển khai rộng rãi nhất về việc sử dụng khả năng cấu hình lại để hỗ trợ DNN, điều mà nhiều nghiên cứu đã đề xuất [Far09][Cha10][Far11][Pee13][Cav15][Zha15]. Họ chọn FPGA thay vì GPU để giảm công suất cũng như rủi ro rằng các ứng dụng nhạy cảm với độ trễ sẽ không ánh xạ tốt lên GPU. FPGA cũng có thể được tái sử dụng, chẳng hạn như cho tìm kiếm, nén và các card giao diện mạng [Put15]. Dự án TPU thực sự bắt đầu với FPGA, nhưng chúng tôi đã từ bỏ chúng khi nhận thấy rằng các FPGA thời điểm đó không có hiệu năng cạnh tranh so với GPU thời điểm đó, và TPU có thể có công suất thấp hơn nhiều so với GPU trong khi nhanh tương đương hoặc nhanh hơn, mang lại các lợi ích đáng kể tiềm năng so với cả FPGA và GPU.
Catapult is the most widely deployed example of using reconfigurability to support DNNs, which many have proposed [Far09][Cha10][Far11][Pee13][Cav15][Zha15]. They chose FPGAs over GPUs to reduce power as well as the risk that latency-sensitive applications wouldn’t map well to GPUs. FPGAs can also be re-purposed, such as for search, compression, and network interface cards [Put15]. The TPU project actually began with FPGAs, but we abandoned them when we saw that the FPGAs of that time were not competitive in performance compared to the GPUs of that time, and the TPU could be much lower power than GPUs while being as fast or faster, giving it potentially significant benefits over both of FPGAs and GPUs.
Mặc dù được công bố lần đầu vào năm 2014 [Put14], Catapult là một sản phẩm cùng thời với TPU vì nó triển khai FPGA Stratix V 28-nm vào các trung tâm dữ liệu đồng thời với TPU vào năm 2015. Catapult có xung nhịp 200 MHz, 3,926 MAC 18-bit, 5 MiB bộ nhớ trên chip, băng thông bộ nhớ 11 GB/s, và sử dụng 25 Watts. TPU có xung nhịp 700 MHz, 65,536 MAC 8-bit, 28 MiB, 34 GB/s, và thường sử dụng 40 Watts. Một phiên bản sửa đổi của Catapult sử dụng các FPGA mới hơn và được triển khai ở quy mô lớn hơn vào năm 2016 [Cau16].
Although first published in 2014 [Put14], Catapult is a TPU contemporary since it deployed 28-nm Stratix V FPGAs into datacenters concurrently with the TPU in 2015. Catapult has a 200 MHz clock, 3,926 18-bit MACs, 5 MiB of on-chip memory, 11 GB/s memory bandwidth, and uses 25 Watts. The TPU has a 700 MHz clock, 65,536 8-bit MACs, 28 MiB, 34 GB/s, and typically uses 40 Watts. A revised version of Catapult uses newer FPGAs and was deployed at larger scale in 2016 [Cau16].
Catapult V1 chạy CNN, sử dụng một bộ nhân ma trận dạng tâm thu, nhanh gấp 2.3X so với một server 2.1 GHz, 16 lõi, hai socket [Ovt15a]. Sử dụng thế hệ FPGA tiếp theo (14-nm Arria 10) của Catapult V2, hiệu năng có thể tăng lên 7X, và thậm chí có thể đạt 17X với việc floorplanning cẩn thận hơn [Ovt15b]. Mặc dù đây là so sánh giữa táo và cam, một die TPU hiện tại chạy các CNN của nó nhanh hơn từ 40X đến 70X so với một server nhanh hơn đôi chút (Tables 2 và 6). Có lẽ khác biệt lớn nhất là để đạt hiệu năng tốt nhất, người dùng phải viết các chương trình dài bằng ngôn ngữ thiết kế phần cứng cấp thấp Verilog [Met16][Put16] thay vì viết các chương trình ngắn sử dụng khung TensorFlow cấp cao. Nghĩa là, khả năng lập trình lại đến từ phần mềm cho TPU thay vì từ firmware cho FPGA.
Catapult V1 runs CNNs—using a systolic matrix multiplier—2.3X as fast as a 2.1 GHz, 16-core, dual-socket server [Ovt15a]. Using the next generation of FPGAs (14-nm Arria 10) of Catapult V2, performance might go up to 7X, and perhaps even 17X with more careful floorplanning [Ovt15b]. Although it’s apples versus oranges, a current TPU die runs its CNNs 40X to 70X versus a somewhat faster server (Tables 2 and 6). Perhaps the biggest difference is that to get the best performance the user must write long programs in the low-level hardware-design-language Verilog [Met16][Put16] versus writing short programs using the high-level TensorFlow framework. That is, reprogrammability comes from software for the TPU rather than from firmware for the FPGA.
Các nghiên cứu gần đây, xuất hiện sau khi TPU được triển khai, tăng tốc DNN bằng cách tối ưu hóa các trường hợp khi trọng số và dữ liệu rất nhỏ hoặc bằng không. Lịch trình chặt chẽ của chúng tôi đã ngăn cản các tối ưu hóa như vậy trong TPU, nhưng chúng tôi nhận thấy cùng cơ hội này trong các nghiên cứu của mình. Efficient Inference Engine dựa trên một bước đầu tiên làm giảm số lượng trọng số khoảng một hệ số 10 [Han15] như một bước riêng biệt bằng cách lọc ra các giá trị rất nhỏ, sau đó sử dụng mã hóa Huffman để thu nhỏ dữ liệu hơn nữa nhằm cải thiện hiệu năng suy luận [Han16]. Cnvlutin [Alb16] tránh các phép nhân khi đầu vào kích hoạt bằng không, điều xảy ra 44% thời gian, có lẽ một phần do hàm phi tuyến ReLU biến đổi các giá trị âm thành không, để cải thiện hiệu năng trung bình 1.4 lần.
Recent research, which appeared after the TPU was deployed, accelerates DNNs by optimizing the cases when weights and data are very small or zero. Our tight schedule precluded such optimizations in the TPU, but we saw the same opportunity in our studies. The Efficient Inference Engine is based on a first pass that reduces the number of weights by about a factor of 10 [Han15] as a separate step by filtering out very small values and then uses Huffman encoding to shrink the data even further to improve inference performance [Han16]. Cnvlutin [Alb16] avoids multiplications when an activation input is zero—which it is 44% of the time, presumably in part due to ReLU nonlinear function that transforms negative values to zero—to improve performance by an average 1.4 times.
Eyeriss là một kiến trúc luồng dữ liệu mới, công suất thấp, tận dụng các giá trị 0 bằng cách mã hóa độ dài chạy dữ liệu để giảm dấu chân bộ nhớ và tiết kiệm năng lượng bằng cách tránh các phép tính khi đầu vào là 0 [Che16a]. Sử dụng thuật ngữ Eyeriss, một lớp tích chập TPU ánh xạ C và M tới các hàng và cột của đơn vị ma trận, mất HWN chu kỳ để thực hiện một lượt quét. Với C/M cao, cần RS lượt quét để xử lý lớp; với C/M thấp, một số kỹ thuật làm giảm số lượt quét và cải thiện mức sử dụng. (Có thể tìm thêm trong các tài liệu tham khảo trực tuyến [Ros15a][Ros15b][Ros15c][Ros15f][Tho15][You15]).
Eyeriss is a novel, low-power dataflow architecture that takes advantage of zeros by run-length encoding data to reduce the memory footprint and saves power by avoiding computations when an input is zero [Che16a]. Using Eyeriss terminology, a TPU convolutional layer maps C and M to the rows and columns of the matrix unit, taking HWN cycles to perform one pass. With high C/M, it takes RS passes to process the layer; for low C/M, a number of techniques reduce passes and improve utilization. (More can be found in the online references [Ros15a][Ros15b][Ros15c][Ros15f][Tho15][You15]).
Minerva là một hệ thống đồng thiết kế vượt qua các lĩnh vực thuật toán, kiến trúc và mạch để giảm công suất 8X, một phần bằng cách cắt tỉa dữ liệu kích hoạt với các giá trị nhỏ và một phần bằng cách lượng tử hóa dữ liệu [Rea16]. [Gup15] xem xét phép toán dấu phẩy cố định 16-bit cho huấn luyện thay vì cho suy luận. Các công trình khác tận dụng độ chính xác thấp hơn của các phép tính DNN bằng cách sử dụng các mạch tương tự trong quá trình tính toán để cải thiện năng lượng và hiệu năng [LiK16] [Sha16]. Bằng cách điều chỉnh một tập lệnh cho DNN, Cambricon giảm kích thước mã [Liu16]. Các công trình gần đây xem xét các kiến trúc bộ xử lý trong bộ nhớ cho NN [Chi16][Kim16].
Minerva is a co-design system that crosses algorithm, architecture, and circuit disciplines to reduce power by 8X in part by pruning activation data with small values and in part by quantizing the data [Rea16]. [Gup15] looks at 16-bit fixed-point arithmetic for training instead of for inference. Others leverage the lower precision of DNN calculations by utilizing analog circuits during the computation to improve energy and performance [LiK16] [Sha16]. By tailoring an instruction set to DNNs, Cambricon reduces code size [Liu16]. Recent work looked at processor-in-memory architectures for NNs [Chi16][Kim16].
So sánh TPU với một số kiến trúc này: • [Che14a] DMA dữ liệu từ DRAM tới các bộ đệm đầu vào và trọng số. Chúng được đọc bởi NFU có đường ống 3 giai đoạn, thực hiện các phép nhân, phép cộng và các hàm phi tuyến; các kết quả đi tới bộ đệm đầu ra, sau đó tới DRAM. NFU không có lưu trữ và không phải là systolic.
Comparing the TPU to some of these architectures: • [Che14a] DMAs data from DRAM to input and weight buffers. They are read by the 3-stage pipelined NFU that performs multiplies, adds, and non-linear-functions; the results go to the output buffer, and then to DRAM. The NFU has no storage and isn’t systolic.
• [Gup15] dường như truyền luồng cả hai đầu vào ma trận trong khi lưu các tổng từng phần trong mảng systolic; TPU lưu tile ma trận trọng số trong khi truyền luồng đầu vào còn lại và các tổng từng phần trước kích hoạt. TPU không hỗ trợ làm tròn ngẫu nhiên. • [Zha15] được xây dựng từ các đơn vị tính toán tương đương với phiên bản 4x2 của đơn vị ma trận TPU. Trong một ASIC, chi phí nối dây của các crossbar kết nối bộ đệm đầu vào và đầu ra với các engine tính toán này sẽ rất đáng kể. Chúng tôi ngạc nhiên khi không thấy hỗ trợ kiến trúc cho các phép rút gọn bổ sung để kết hợp các kết quả từ các engine tính toán trong [Zha15]. Cả ba công trình [Gup15][Che14][Zha15] đều lưu các giá trị kích hoạt trong DRAM trong quá trình tính toán; Unified Buffer của TPU có kích thước đủ lớn để không xảy ra việc tràn sang DRAM hoặc nạp lại trong quá trình hoạt động bình thường.
• [Gup15] appears to stream both matrix inputs while storing partial sums in the systolic array; the TPU stores the weight matrix tile while streaming the other input and the pre-activation partial sums. The TPU doesn’t support stochastic rounding. • [Zha15] is built out of computation units equivalent to a 4x2 version of the TPU matrix unit. In an ASIC, the wiring cost of the crossbars that connect input and output buffers to these compute engines would be significant. We are surprised that we didn’t see architectural support for additional reductions to combine results from compute engines in [Zha15]. All three of [Gup15][Che14][Zha15] store activations in DRAM during computation; the TPU’s Unified Buffer is sized so that no DRAM spilling or reloading happens during normal operation.
10 Kết luận
10 Conclusion
Mặc dù sống trên một bus I/O và có băng thông bộ nhớ tương đối nhỏ làm hạn chế việc sử dụng TPU—bốn trong sáu ứng dụng NN bị giới hạn bởi bộ nhớ—một phần nhỏ của một con số lớn vẫn có thể tương đối lớn, như mô hình hiệu năng Roofline chứng minh. Kết quả này gợi ý một “Hệ quả Cornucopia” đối với Định luật Amdahl: mức sử dụng thấp của một tài nguyên khổng lồ, giá rẻ vẫn có thể mang lại hiệu năng cao, hiệu quả về chi phí.
Despite living on an I/O bus and having relatively little memory bandwidth that limits utilization of the TPU—four of the six NN applications are memory-bound—a small fraction of a big number can nonetheless be relatively large, as the Roofline performance model demonstrates. This result suggests a “Cornucopia Corollary” to Amdahl’s Law: low utilization of a huge, cheap resource can still deliver high, cost-effective performance.
TPU tận dụng sự giảm bậc độ lớn về năng lượng và diện tích của các bộ nhân ma trận dạng tâm thu số nguyên 8-bit so với các đường dẫn dữ liệu dấu phẩy động 32-bit của GPU K80 để tích hợp số lượng MAC gấp 25 lần (65,536 8-bit so với 2,496 32-bit) và bộ nhớ trên chip lớn gấp 3.5 lần (28 MiB so với 8 MiB) trong khi sử dụng ít hơn một nửa công suất của K80 trong một die tương đối nhỏ. Bộ nhớ lớn hơn này giúp tăng cường độ hoạt động của các ứng dụng để cho phép chúng tận dụng các MAC dồi dào một cách đầy đủ hơn nữa.
The TPU leverages the order-of-magnitude reduction in energy and area of 8-bit integer systolic matrix multipliers over 32-bit floating-point datapaths of a K80 GPU to pack 25 times as many MACs (65,536 8-bit vs. 2,496 32-bit) and 3.5 times the on-chip memory (28 MiB vs. 8 MiB) while using less than half the power of the K80 in a relatively small die. This larger memory helps increase the operational intensity of applications to let them utilize the abundant MACs even more fully.
Chúng tôi nhận thấy rằng mặc dù gần đây cộng đồng kiến trúc nhấn mạnh vào CNN, chúng chỉ chiếm khoảng 5% tải công việc NN đại diện cho các datacenter của chúng tôi, điều này cho thấy cần chú ý nhiều hơn đến MLP và LSTM. Lặp lại lịch sử, điều này tương tự như khi nhiều kiến trúc sư tập trung vào hiệu năng dấu phẩy động trong khi phần lớn tải công việc chính thống hóa ra lại bị chi phối bởi các phép toán số nguyên.
We found that despite a recent emphasis on CNNs in the architecture community, they constitute only about 5% of the representative NN workload for our datacenters, which suggests more attention should be paid to MLPs and LSTMs. Repeating history, it’s similar to when many architects concentrated on floating-point performance when most mainstream workloads turned out to be dominated by integer operations.
Chúng tôi quan sát thấy rằng số lượng suy luận mỗi giây (IPS) phụ thuộc nhiều hơn vào NN chứ không phải phần cứng bên dưới, và do đó IPS là một chỉ số hiệu năng đơn lẻ còn tệ hơn đối với các bộ xử lý NN so với MIPS và MFLOPS đối với CPU và GPU.
We observed that inferences per second (IPS) is more a function of the NN than of the underlying hardware, and so IPS is an even worse single performance metric for NN processors than MIPS and MFLOPS are for CPUs and GPUs.
Chúng tôi cũng nhận thấy rằng các ứng dụng suy luận có các cận thời gian đáp ứng nghiêm ngặt vì chúng thường là một phần của các ứng dụng hướng tới người dùng, do đó kiến trúc NN cần hoạt động tốt khi xử lý các thời hạn độ trễ ở phân vị thứ 99. Mặc dù K80 có thể vượt trội trong huấn luyện, trung bình nó chỉ nhanh hơn Haswell một chút trong suy luận đối với tải công việc của chúng tôi, có lẽ vì nó nhấn mạnh vào thông lượng thay vì độ trễ; điều đó xung đột với các thời hạn đáp ứng nghiêm ngặt của các ứng dụng suy luận của chúng tôi.
We also learned that inference applications have serious response-time bounds because they are often part of user facing applications, thus NN architectures need to perform well when coping with 99th-percentile latency deadlines. While the K80 may excel at training, on average it is just a little faster than Haswell at inference for our workload, perhaps because of its emphasis on throughput rather than latency; that conflicts with the strict response-time deadlines of our inference applications.
Die TPU tận dụng lợi thế về MAC và bộ nhớ trên chip để chạy các chương trình ngắn được viết bằng khung TensorFlow chuyên biệt theo miền nhanh gấp 15 lần die GPU K80, dẫn đến lợi thế hiệu năng/Watt là 29 lần, tương quan với hiệu năng/tổng chi phí sở hữu. So với die CPU Haswell, các tỷ lệ tương ứng là 29 và 83. Mặc dù các CPU và GPU tương lai chắc chắn sẽ chạy suy luận nhanh hơn, một TPU được thiết kế lại sử dụng bộ nhớ GPU vào khoảng năm 2015 sẽ nhanh hơn từ hai đến ba lần và nâng lợi thế hiệu năng/Watt lên gần 70 lần so với K80 và 200 lần so với Haswell.
The TPU die leverages its advantage in MACs and on-chip memory to run short programs written using the domain-specific TensorFlow framework 15 times as fast as the K80 GPU die, resulting in a performance/Watt advantage of 29 times, which is correlated with performance/total cost of ownership. Compared to the Haswell CPU die, the corresponding ratios are 29 and 83. While future CPUs and GPUs will surely run inference faster, a redesigned TPU using circa 2015 GPU memory would go two to three times as fast and boost the performance/Watt advantage of nearly 70 over the K80 and 200 over Haswell.
Tóm lại, TPU thành công nhờ đơn vị nhân ma trận lớn—nhưng không quá lớn; bộ nhớ trên chip đáng kể được điều khiển bằng phần mềm; khả năng chạy toàn bộ mô hình suy luận để giảm sự phụ thuộc vào CPU máy chủ; mô hình thực thi đơn luồng, xác định đã chứng minh là phù hợp với các giới hạn thời gian đáp ứng ở phân vị thứ 99; đủ tính linh hoạt để phù hợp với các NN của năm 2017 cũng như năm 2013; việc loại bỏ các tính năng đa dụng giúp tạo ra một die nhỏ và công suất thấp mặc dù có đường dẫn dữ liệu và bộ nhớ lớn hơn; việc sử dụng số nguyên 8-bit bởi các ứng dụng lượng tử hóa; và việc các ứng dụng được viết bằng TensorFlow, giúp dễ dàng chuyển chúng sang TPU với hiệu năng cao thay vì phải viết lại để chạy tốt trên phần cứng TPU rất khác biệt.
In summary, the TPU succeeded because of the large—but not too large—matrix multiply unit; the substantial software-controlled on-chip memory; the ability to run whole inference models to reduce dependence on host CPU; a single-threaded, deterministic execution model that proved to be a good match to 99th-percentile response time limits; enough flexibility to match the NNs of 2017 as well as of 2013; the omission of general-purpose features that enabled a small and low power die despite the larger datapath and memory; the use of 8-bit integers by the quantized applications; and that applications were written using TensorFlow, which made it easy to port them to the TPU at high-performance rather than them having to be rewritten to run well on the very different TPU hardware.
Sự khác biệt bậc độ lớn giữa các sản phẩm thương mại là hiếm trong kiến trúc máy tính, điều này có thể khiến TPU trở thành một nguyên mẫu cho các kiến trúc chuyên biệt theo miền. Chúng tôi kỳ vọng rằng nhiều người sẽ xây dựng các thế hệ kế nhiệm, nâng cao tiêu chuẩn hơn nữa.
Order-of-magnitude differences between commercial products are rare in computer architecture, which may lead to the TPU becoming an archetype for domain-specific architectures. We expect that many will build successors that will raise the bar even higher.
Lời cảm ơn
Acknowledgments
Chúng tôi cảm ơn ban lãnh đạo công ty vì đã nhận ra nhu cầu về một TPU và cung cấp các tài nguyên để xây dựng, phân phối, đánh giá và công bố. Đặc biệt cảm ơn Luiz Barroso và James Laudon vì đã giúp khởi đầu dự án. Cần có sự đóng góp của nhiều người để thiết kế, xác minh và triển khai phần cứng cùng phần mềm của một hệ thống như TPU, cũng như để sản xuất, triển khai và sử dụng nó ở quy mô lớn, đó là lý do có nhiều tác giả. (Tất cả tác giả ngoại trừ David Patterson đều làm việc trên TPU; ông tham gia vào năm 2016.) Bốn tác giả đầu tiên thực hiện phần lớn việc đánh giá trong bài báo này, đó là lý do họ đứng trước, với những người còn lại theo thứ tự bảng chữ cái. Jouppi cũng là kiến trúc sư trưởng của toàn bộ dự án; phần thưởng cho những nỗ lực bền bỉ của ông là trở thành tác giả chính.
We thank the leadership of our company for recognizing the need for a TPU and for providing the resources to build, distribute, evaluate, and publish. Special thanks go to Luiz Barroso and James Laudon for helping start the project. It takes a village to design, verify, and implement the hardware and software of a system like a TPU and to manufacture, deploy, and use it at scale, which is why there are many authors. (All authors but David Patterson worked on the TPU; he joined in 2016.) The first four authors did the bulk of the evaluation in this paper, which is why they are in front, with the rest in alphabetical order. Jouppi was also the senior architect of the whole project; the reward for his yeoman’s work is being the lead author.
References
- Abadi, M., Agarwal, A., Barham, P., Brevdo, E., Chen, Z., Citro, C., Corrado, G.S., Davis, A., Dean, J., Devin, M. and Ghemawat, S., 2016. Tensorflow: Large-scale machine learning on heterogeneous distributed systems. arXiv preprint arXiv:1603.04467.
- Albericio, J., Judd, P., Hetherington, T., Aamodt, T., Jerger, N.E. and Moshovos, A., 2016 Cnvlutin: Ineffectual-Neuron-Free Deep Neural Network Computing. Proceedings of the 43rd International Symposium on Computer Architecture.
- Adolf, R., Rama, S., Reagen, B., Wei, G.Y. and Brooks, D., 2016, September. Fathom: reference workloads for modern deep learning methods. IEEE International Symposium on Workload Characterization (IISWC).
- Asanović, K. 2002. Programmable Neurocomputing, in The Handbook of Brain Theory and Neural Networks: Second Edition, M. A. Arbib (Ed.), MIT Press, ISBN 0-262-01197-2, November 2002. https://people.eecs.berkeley.edu/~krste/papers/neurocomputing.pdf
- Asanović, K. 1998. Asanović, K., Beck, Johnson, J., Wawrzynek, J., Kingsbury, B. and Morgan, N., November 1998. Training Neural Networks with Spert-II. Chapter 11 in Parallel Architectures for Artificial Networks: Paradigms and Implementations, N. Sundararajan and P. Saratchandran (Eds.), IEEE Computer Society Press, ISBN 0-8186-8399-6. https://people.eecs.berkeley.edu/~krste/papers/annbook.pdf
- Barroso, L.A. and Hölzle, U., 2007. The case for energy-proportional computing. IEEE Computer, vol. 40.
- Barr, J. September 29, 2016, New P2 Instance Type for Amazon EC2 – Up to 16 GPUs. https://aws.amazon.com/blogs/aws/new-p2-instance-type-for-amazon-ec2-up-to-16-gpus/
- Brooks, D. November 4, 2016. Private communication.
- Caulfield, A.M., Chung, E.S., Putnam, A., Haselman, H.A.J.F.M., Humphrey, S.H.M., Daniel, P.K.J.Y.K., Ovtcharov, L.T.M.K., Lanka, M.P.L.W.S. and Burger, D.C.D., 2016. A Cloud-Scale Acceleration Architecture. MICRO conference.
- Cavigelli, L., Gschwend, D., Mayer, C., Willi, S., Muheim, B. and Benini, L., 2015, May. Origami: A convolutional network accelerator. Proceedings of the 25th edition on Great Lakes Symposium on VLSI.
- Chakradhar, S., Sankaradas, M., Jakkula, V. and Cadambi, S., 2010, June. A dynamically configurable coprocessor for convolutional neural networks. Proceedings of the 37th International Symposium on Computer Architecture.
- Chen, T., Du, Z., Sun, N., Wang, J., Wu, C., Chen, Y. and Temam, O., 2014. Diannao: A small-footprint high-throughput accelerator for ubiquitous machine-learning. Proceedings of ASPLOS.
- Chen, Y., Luo, T., Liu, S., Zhang, S., He, L., Wang, J., Li, L., Chen, T., Xu, Z., Sun, N. and Temam, O., 2014, December. Dadiannao: A machine-learning supercomputer. Proceedings of the 47th Annual International Symposium on Microarchitecture.
- Chen, Y.H., Emer, J. and Sze, V., 2016. Eyeriss: A Spatial Architecture for Energy-Efficient Dataflow for Convolutional Neural Networks. Proceedings of the 43rd International Symposium on Computer Architecture.
- Chen, Y., Chen, T.,Xu, Z., Sun, N., and Teman, O., 2016. DianNao Family: Energy-Efficient Hardware Accelerators for Machine Learning, Research Highlight, Communications of the ACM, 59(11).
- Chi, P., Li, S., Qi, Z., Gu, P., Xu, C., Zhang, T., Zhao, J., Liu, Y., Wang, Y. and Xie, Y., 2016. PRIME: A Novel Processing-In-Memory Architecture for Neural Network Computation in ReRAM-based Main Memory. Proceedings of the 43rd International Symposium on Computer Architecture.
- Clark, J. October 26, 2015, Google Turning Its Lucrative Web Search Over to AI Machines. Bloomberg Technology, www.bloomberg.com.
- Dally, W. February 9, 2016. High Performance Hardware for Machine Learning, Cadence ENN Summit.
- Dean, J. and Barroso, L.A., 2013. The tail at scale. Communications of the ACM, 56(2).
- Dean, J. July 7, 2016 Large-Scale Deep Learning with TensorFlow for Building Intelligent Systems, ACM Webinar.
- Du, Z., Fasthuber, R., Chen, T., Ienne, P., Li, L., Luo, T., Feng, X., Chen, Y. and Temam, O., 2015, June. ShiDianNao: shifting vision processing closer to the sensor. Proceedings of the 42nd International Symposium on Computer Architecture.
- Farabet, C., Poulet, C., Han, J.Y. and LeCun, Y., 2009, August. Cnp: An FPGA-based processor for convolutional networks. 2009 International Conference on Field Programmable Logic and Applications.
- Farabet, C., Martini, B., Corda, B., Akselrod, P., Culurciello, E. and LeCun, Y., 2011, June. Neuflow: A runtime reconfigurable dataflow processor for vision. In CVRP 2011 Workshops.
- Gupta, S., Agrawal, A., Gopalakrishnan, K. and Narayanan, P., 2015, July. Deep Learning with Limited Numerical Precision. ICML.
- Hammerstrom, D., 1990, June. A VLSI architecture for high-performance, low-cost, on-chip learning. 1990 IJCNN International Joint Conference on Neural Networks.
- Han, S.; Pool, J.; Tran, J.; and Dally, W., 2015. Learning both weights and connections for efficient neural networks. In Advances in Neural Information Processing Systems.
- Han, S., Liu, X., Mao, H., Pu, J., Pedram, A., Horowitz, M.A. and Dally, W.J., 2016. EIE: efficient inference engine on compressed deep neural network. Proceedings of the 43rd International Symposium on Computer Architecture.
- He, K., Zhang, X., Ren, S. and Sun, J., 2016. Identity mappings in deep residual networks. Also in arXiv preprint arXiv:1603.05027.
- Hennessy, J.L. and Patterson, D.A., 2018. Computer architecture: a quantitative approach, 6th edition, Elsevier.
- Hölzle, U. and Barroso, L., 2009. The datacenter as a computer. Morgan and Claypool.
- Ienne, P., Cornu, T. and Kuhn, G., 1996. Special-purpose digital hardware for neural networks: An architectural survey. Journal of VLSI signal processing systems for signal, image and video technology, 13(1).
- Intel, 2016, Intel® Xeon® Processor E5-4669 v3, http://ark.intel.com/products/85766/Intel-Xeon-Processor-E5-4669-v3-45M-Cache-2_10-GHz
- Jouppi, N. May 18, 2016. Google supercharges machine learning tasks with TPU custom chip. https://cloudplatform.googleblog.com
- Keutzer, K., 2016. If I could only design one circuit…: technical perspective. Communications of the ACM, 59(11),.
- Kim, D., Kung, J.H., Chai, S., Yalamanchili, S. and Mukhopadhyay, S., 2016. Neurocube: A Programmable Digital Neuromorphic Architecture with High-Density 3D Memory. Proceedings of the 43rd International Symposium on Computer Architecture.
- Krizhevsky, A., Sutskever, I. and Hinton, G., 2012. Imagenet classification with deep convolutional neural networks. Advances in neural information processing systems. Read it here
- Kung, H.T. and Leiserson, C.E., 1980. Algorithms for VLSI processor arrays. Introduction to VLSI systems.
- Lange, K.D., 2009. Identifying shades of green: The SPECpower benchmarks. IEEE Computer, 42(3).
- Larabel, M. March 10, 2016, Google Looks To Open Up StreamExecutor To Make GPGPU Programming Easier, Phoronix, https://www.phoronix.com/scan.php?page=news_item&px=Google-StreamExec-Parallel.
- LiKamWa, R., Hou, Y., Gao, J., Polansky, M. and Zhong, L., 2016. RedEye: Analog ConvNet Image Sensor Architecture for Continuous Mobile Vision. *Proceedings of the 43rd International Symposium on Computer Architecture.*
- Liu, D., Chen, T., Liu, S., Zhou, J., Zhou, S., Teman, O., Feng, X., Zhou, X. and Chen, Y., 2015, March. Pudiannao: A polyvalent machine learning accelerator. *Proceedings of the 42nd International Symposium on Computer Architecture.*
- Liu, S., Du, Z.D., Tao, J.H., Han, D., Luo, T., Xie, Y., Chen, Y. and Chen, T., 2016. Cambricon: An instruction set architecture for neural networks. *Proceedings of the 43rd International Symposium on Computer Architecture.*
- Metz, C. September 26, 2016, Microsoft Bets Its Future On A Reprogrammable Computer Chip, *Wired Magazine*, https://www.wired.com/2016/09/microsoft-bets-future-chip-reprogram-fly/ 17-001-v05.pdf.
- Nvidia, 2016. Tesla GPU Accelerators For Servers. http://www.nvidia.com/object/tesla-servers.html.
- Ovtcharov, K., Ruwase, O., Kim, J.Y., Fowers, J., Strauss, K. and Chung, E.S., February 2, 2015. Accelerating deep convolutional neural networks using specialized hardware. Microsoft Research Whitepaper. https://www.microsoft.com/en-us/research/publication/accelerating-deep-convolutional-neural-networks-using-specialized-hardware/
- Ovtcharov, K., Ruwase, O., Kim, J.Y., Fowers, J., Strauss, K. and Chung, E.S., 2015, August. Toward accelerating deep learning at scale using specialized hardware in the datacenter. *2015 IEEE Hot Chips 27 Symposium.*
- Patterson, D.A., 2004. Latency lags bandwith. *Communications of the ACM*, 47(10).
- Peemen, M., Setio, A.A., Mesman, B. and Corporaal, H., 2013, October. Memory-centric accelerator design for convolutional neural networks. In *2013 IEEE 31st International Conference on Computer Design (ICCD).*
- Putnam, A., Caulfield, A.M., Chung, E.S., Chiou, D., Constantinides, K., Demme, J., Esmaeilzadeh, H., Fowers, J., Gopal, G.P., Gray, J., Haselman, M., Hauck, S., Heil, S., Hormati, A., Kim, J-Y., Lanka, S., Larus, J., Peterson, E., Pope, S ., Smith, A., Thong, J., Xiao, P.Y., Burger, D. 2014, June. A reconfigurable fabric for accelerating large-scale datacenter services. *41st International Symposium on Computer Architecture.*
- Putnam, A., Caulfield, A.M., Chung, E.S., Chiou, D., Constantinides, K., Demme, J., Esmaeilzadeh, H., Fowers, J., Gopal, G.P., Gray, J., Haselman, M., Hauck, S., Heil, S., Hormati, A., Kim, J-Y., Lanka, S., Larus, J., Peterson, E., Pope, S ., Smith, A., Thong, J., Xiao, P.Y., Burger, D. 2015. A Reconfigurable Fabric for Accelerating Large-Scale Datacenter Services. *IEEE Micro*, 35(3).
- Putnam, A., Caulfield, A.M., Chung, E.S., Chiou, D., Constantinides, K., Demme, J., Esmaeilzadeh, H., Fowers, J., Gopal, G.P., Gray, J., Haselman, M., Hauck, S., Heil, S., Hormati, A., Kim, J-Y., Lanka, S., Larus, J., Peterson, E., Pope, S ., Smith, A., Thong, J., Xiao, P.Y., Burger, D. 2016. A Reconfigurable Fabric for Accelerating Large-Scale Datacenter Services. *Communications of the ACM.*
- Qadeer, W., Hameed, R., Shacham, O., Venkatesan, P., Kozyrakis, C. and Horowitz, M.A., 2013, June. Convolution engine: balancing efficiency & flexibility in specialized computing. *Proceedings of the 40th International Symposium on Computer Architecture.*
- Ramacher, U., Beichter, J., Raab, W., Anlauf, J., Bruels, N., Hachmann, U. and Wesseling, M., 1991. Design of a 1st Generation Neurocomputer. In *VLSI design of Neural Networks*. Springer US.
- Reagen, B., Whatmough, P., Adolf, R., Rama, S., Lee, H., Lee, S.K., Hernández-Lobato, J.M., Wei, G.Y. and Brooks, D., 2016. Minerva: Enabling low-power, highly-accurate deep neural network accelerators. *Proceedings of the 43rd International Symposium on Computer Architecture.*
- Ross, J., Jouppi, N., Phelps, A., Young, C., Norrie, T., Thorson, G., Luu, D., 2015. Neural Network Processor, Patent Application No. 62/164,931.
- Ross, J., Phelps, A., 2015. Computing Convolutions Using a Neural Network Processor, , Patent Application No. 62/164,902.
- Ross, J., 2015. Prefetching Weights for a Neural Network Processor, Patent Application No. 62/164,981.
- Ross, J., Thorson, G., 2015. Rotating Data for Neural Network Computations, Patent Application No. 62/164,908.
- Russakovsky, O., Deng, J., Su, H., Krause, J., Satheesh, S., Ma, S., Huang, Z., Karpathy, A., Khosla, A., Bernstein, M. and Berg, A.C., 2015. Imagenet large scale visual recognition challenge. *International Journal of Computer Vision*, 115(3).
- Schurman, E. and Brutlag, J., 2009, June. The user and business impact of server delays, additional bytes, and HTTP chunking in web search. In *Velocity Web Performance and Operations Conference.*
- Shafiee, A., Nag, A., Muralimanohar, N., Balasubramonian, R., Strachan, J.P., Hu, M., Williams, R.S. and Srikumar, V., 2016. ISAAC: A Convolutional Neural Network Accelerator with In-Situ Analog Arithmetic in Crossbars. *Proceedings of the 43rd International Symposium on Computer Architecture.*
- Silver, D., Huang, A., Maddison, C.J., Guez, A., Sifre, L., Van Den Driessche, G., Schrittwieser, J., Antonoglou, I., Panneershelvam, V., Lanctot, M. and Dieleman, S., 2016. Mastering the game of Go with deep neural networks and tree search. *Nature*, 529(7587). Read it here
- Smith, J.E., 1982, April. Decoupled access/execute computer architectures. *Proceedings of the 11th International Symposium on Computer Architecture.*
- Steinberg, D., 2015. Full-Chip Simulations, Keys to Success. *Proceedings of the Synopsys Users Group (SNUG) Silicon Valley 2015.*
- Szegedy, C., Liu, W., Jia, Y., Sermanet, P., Reed, S., Anguelov, D., Erhan, D., Vanhoucke, V. and Rabinovich, A., 2015. Going deeper with convolutions. *Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition.*
- Thorson, G., Clark, C., Luu, D., 2015. Vector Computation Unit in a Neural Network Processor, Patent Application No. 62/165,022.
- Williams, S., Waterman, A. and Patterson, D., 2009. Roofline: an insightful visual performance model for multicore architectures. *Communications of the ACM.*
- Wu, Y., Schuster, M., Chen, Z., Le, Q., Norouzi, M., Macherey, W., Krikun, M., Cao, Y., Gao, Q., Macherey, K., Klingner, J., Shah, A., Johnson, M., Liu, X., Kaiser, L., Gouws, S., Kato, Y., Kudo, T., Kazawa, H., Stevens, K., Kurian, G., Patil, N., Wang, W., Young, C., Smith, J., Riesa, J., Rudnick, A., Vinyals, O., Corrado, G., Hughes, M., and Dean, J. September 26, 2016, Google's Neural Machine Translation System: Bridging the Gap between Human and Machine Translation, http://arxiv.org/abs/1609.08144. Read it here
- Young, C., 2015. Batch Processing in a Neural Network Processor, Patent Application No. 62/165,020.
- Zhang, C., Li, P., Sun, G., Guan, Y., Xiao, B. and Cong, J., 2015, February. Optimizing FPGA-based accelerator design for deep convolutional neural networks. *Proceedings of the 2015 ACM/SIGDA International Symposium on Field-Programmable Gate Arrays.*
Read off the page by a vision model reading the page images using olmOCR-2-7B-1025-FP8. Translated from the English.
Read off the page by a vision model reading the page images using olmOCR-2-7B-1025-FP8.